 TrackMedia
 TrackRev

 Informatica
 Matillion
 Alteryx
 Talend
 Amazon Web Services
 MotherDuck
 Confluent
 Azure Data Factory
 Exasol
 Starburst
 Vertica
 Keboola
 Azure Data Explorer
 Amazon Kinesis
 Pentaho
 IBM DataStage
 Amazon Athena
 DataSpell
 Astronomer
 Cloudera
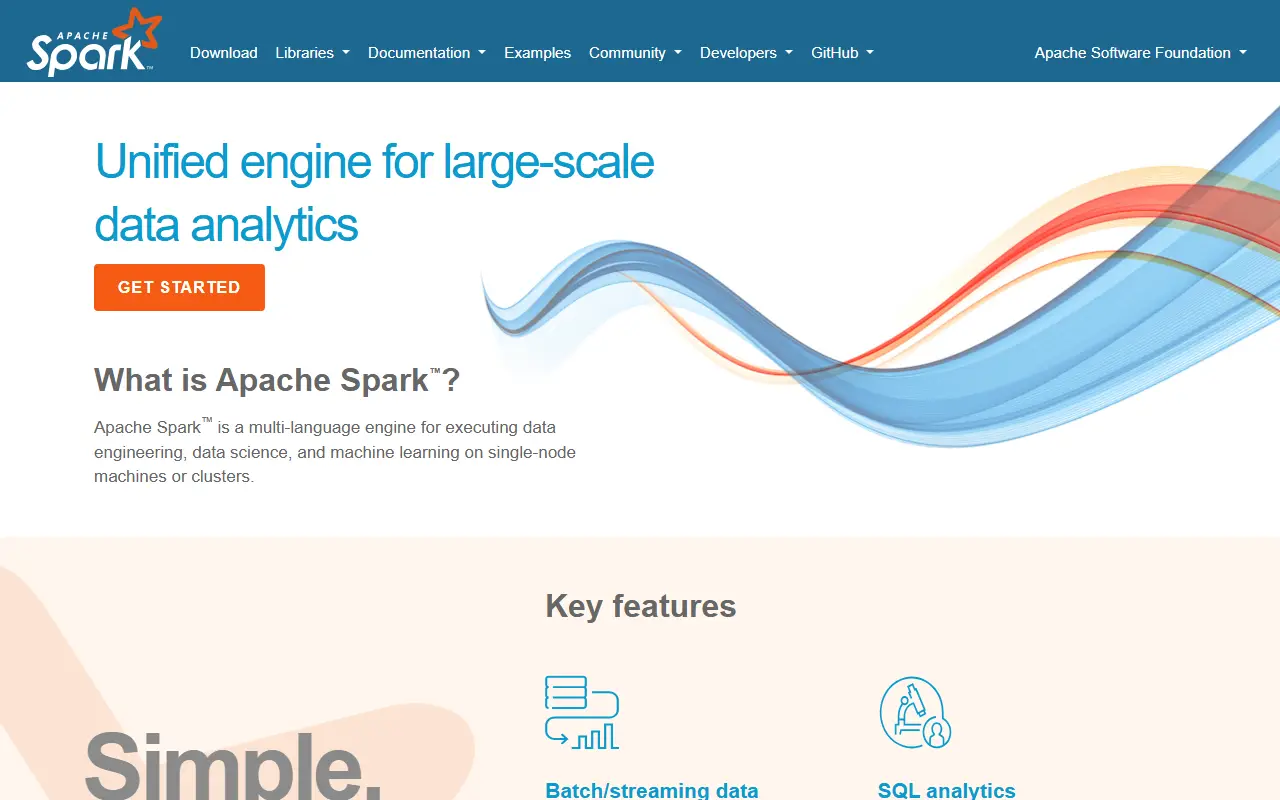
About Apache Spark
Apache Spark is an analytics engine that brings batch, SQL, machine learning, graph and streaming workloads together for processing data at scale. It is maintained by the Apache Software Foundation under the Apache-2.0 license. It is written mainly in Scala and offers high-level APIs in Scala, Java and Python, with an R API that is now deprecated, on top of an engine optimized to execute general computation graphs.
A set of higher-level tools is included: Spark SQL for queries and DataFrames, MLlib for machine learning, GraphX for graphs, Structured Streaming for streams, and a pandas-style API for existing pandas workloads. Together they let teams run batch analytics, machine learning and streaming jobs on a single engine and share code between them.
The README points to the project website for full documentation and programming guides, and it contains only basic setup and build instructions. Spark suits data engineers and data scientists who process datasets too large for a single machine, and organizations that want one framework for ETL, analytics and machine learning on clusters.
Key features
- High-level APIs in Scala, Java and Python
- Optimized engine for computation graphs
- Spark SQL and DataFrames
- MLlib for machine learning
- GraphX for graph analytics
- Structured Streaming for stream processing
- Pandas API on Spark
Good fit for
- Large-scale ETL pipelines
- Distributed machine learning
- Stream processing
Apache Spark: questions and answers
- What is Apache Spark used for?
- Apache Spark is an analytics engine for processing large datasets, with APIs in Scala, Java, Python and R and libraries for SQL, machine learning, graphs and streaming. It is a good fit for large-scale ETL pipelines, distributed machine learning and stream processing.
- Is Apache Spark open source?
- Yes. Apache Spark is open source under the Apache-2.0 licence. Its source code is on GitHub at apache/spark and is written mainly in Scala.
- Is Apache Spark free?
- Yes. Apache Spark is open source, so the software itself is free to use.
- Can I self-host Apache Spark?
- Yes. Apache Spark can be self-hosted on your own server or infrastructure.
- What is Apache Spark an alternative to?
- Apache Spark is an open-source alternative to Databricks, AWS Glue, Google Cloud Dataflow and Amazon EMR. Other open-source alternatives to AWS Glue include Flink, Airflow and Airbyte.
- Is Apache Spark actively maintained?
- Yes. The most recent commit to Apache Spark was on 11 November 2026. The project has 44k stars on GitHub, with 303 added in the last 30 days.
Open-source alternatives to Apache Spark
See all
Flink
Open source
Apache Flink
Apache-2.0vs Matillion★ 26k
Airflow
Data Pipelines & ETL
Apache Airflow - A platform to programmatically author, schedule, and monitor workflows
Apache-2.0vs Astronomer★ 47k
Trino
Databases
Official repository of Trino, the distributed SQL query engine for big data, formerly know
Apache-2.0vs Amazon Redshift★ 14k
Airbyte
Data Pipelines & ETL
Airbyte is the open-source data movement platform. Run ELT pipelines across 700+ connector
OSSvs Fivetran★ 22k
dbt
Data Pipelines & ETL
dbt enables data analysts and engineers to transform their data using the same practices t
Apache-2.0vs Matillion★ 14k
ClickHouse
Databases
ClickHouse is a fast open-source column-oriented database management system that allows ge
Apache-2.0vs Snowflake★ 51k
SaaS alternatives to Apache Spark
See all
Databricks
Data Pipelines & ETL
Lakehouse platform for data engineering, analytics and machine learning
SaaS
AWS Glue
Data Pipelines & ETL
Serverless data integration service on AWS for ETL jobs and data catalogs
SaaS
Google Cloud Dataflow
Data Pipelines & ETL
Managed stream and batch data processing service on Google Cloud based on Apache Beam
SaaS
Amazon EMR
Data Pipelines & ETL
Managed big data platform on AWS for running Spark, Hive, Presto and other frameworks
SaaS
Microsoft Fabric
Data Pipelines & ETL
Unified analytics platform combining data engineering, warehousing and Power BI
SaaS
Snowflake
Databases
Cloud data platform for warehousing, data sharing and analytics
SaaS