#1
An Apache workflow orchestration platform where data teams author, schedule and monitor pipelines as Python code, widely used for data engineering and ELT jobs.
- GitHub stars
- 47k
- Last commit
- today
- Latest release
- 3.4.0
- Licence
- Apache-2.0
- Self-hosted
- Yes
airflow.apache.org
Apache Airflow is a workflow platform where you write, schedule and watch over pipelines in code. Workflows are defined as Python code in the form of directed acyclic graphs, or DAGs, where each task and its dependencies are explicit, so pipelines can be versioned, tested and reviewed like any other software.
A scheduler runs tasks on a defined cadence and workers execute them, while a web interface shows the status of each run, lets you inspect logs and retry failures. Airflow is used heavily in data engineering, including data integration, ELT and ETL pipelines, data orchestration and machine learning workflows, and its topics cover data science and automation. It has a large ecosystem of providers and operators for connecting to databases, cloud services and other systems, and the 3.x line is the current series.
Airflow is an Apache Software Foundation project under the Apache-2.0 license and runs on your own infrastructure, from a single machine to Kubernetes. Several vendors offer managed Airflow services, but the project itself is self-hosted software. It suits data engineers who prefer code-first orchestration over drag-and-drop tools.
Key features
- Workflows defined as Python DAGs
- Scheduler for recurring and dependent tasks
- Web UI for monitoring runs and logs
- Retries and task dependency management
- Large provider ecosystem of integrations
- Runs on single machines or Kubernetes
Pricing: Free and open source under the Apache-2.0 license.
#2
An analytics engine for processing large datasets, with APIs in Scala, Java, Python and R and libraries for SQL, machine learning, graphs and streaming.
- GitHub stars
- 44k
- Last commit
- yesterday
- Licence
- Apache-2.0
- Self-hosted
- Yes
spark.apache.org
Apache Spark is an analytics engine that brings batch, SQL, machine learning, graph and streaming workloads together for processing data at scale. It is maintained by the Apache Software Foundation under the Apache-2.0 license. It is written mainly in Scala and offers high-level APIs in Scala, Java and Python, with an R API that is now deprecated, on top of an engine optimized to execute general computation graphs.
A set of higher-level tools is included: Spark SQL for queries and DataFrames, MLlib for machine learning, GraphX for graphs, Structured Streaming for streams, and a pandas-style API for existing pandas workloads. Together they let teams run batch analytics, machine learning and streaming jobs on a single engine and share code between them.
The README points to the project website for full documentation and programming guides, and it contains only basic setup and build instructions. Spark suits data engineers and data scientists who process datasets too large for a single machine, and organizations that want one framework for ETL, analytics and machine learning on clusters.
Key features
- High-level APIs in Scala, Java and Python
- Optimized engine for computation graphs
- Spark SQL and DataFrames
- MLlib for machine learning
- GraphX for graph analytics
- Structured Streaming for stream processing
- Pandas API on Spark
Pricing: Free and open source under the Apache-2.0 license.
#3
An open-source data movement platform with hundreds of connectors for ELT pipelines from APIs, databases and files into warehouses, lakes and AI applications.
- GitHub stars
- 22k
- Last commit
- today
- Latest release
- v2.0.0
- Self-hosted
- Yes
- Hosted version
- Available
airbyte.com
Airbyte is an open-source data movement platform for moving data from APIs, databases and files into data warehouses, data lakes and AI applications. Its premise is that only an open-source project can reach the long tail of data sources while letting engineers tailor existing connectors, with the aim of moving data from any source to any destination.
It offers a catalog of 600 or more connectors for APIs, databases, warehouses, lakes and AI applications, with warehouse destinations such as BigQuery, Redshift and Snowflake, and topics also mention change data capture. The README distinguishes products by job: Airbyte Open Source or Airbyte Cloud for ELT and ETL into warehouses, lakes or databases, and Airbyte Agents, a managed data and context layer, plus an open-source Agent SDK for giving AI agents and MCP clients real-time access to business data.
Airbyte is written in Python and Java, and its license is listed as 'Other' on GitHub because the project uses a mix of licenses, so review the terms for your use. It can be self-hosted or run as the managed Airbyte Cloud, and suits data teams that need many integrations without writing each pipeline by hand.
Key features
- 600+ source and destination connectors
- ELT pipelines into warehouses and lakes
- Change data capture support
- Customizable open-source connectors
- Agent SDK for AI agent data access
- Self-hosted or Airbyte Cloud
Pricing: The open-source Core edition is free to self-host. Managed cloud starts at $20 a month (Standard) or $189 a month for 40 credits (Plus); Pro and Enterprise Flex are custom. 30-day trial.
#4
A data transformation framework that lets analysts and engineers build analytics models with software-engineering practices; v2.0 is a ground-up rewrite in Rust.
- GitHub stars
- 14k
- Last commit
- today
- Latest release
- v1.12.7
- Licence
- Apache-2.0
- Self-hosted
- Yes
- Hosted version
- Available
getdbt.com
dbt is a framework for transforming data in a warehouse using the same practices that software engineers apply to applications. Analysts and analytics engineers write models, and dbt parses, compiles and runs the project so that transformations are version-controlled and repeatable.
The repository now holds the Apache 2.0 source of dbt v2.0, a ground-up rewrite in Rust. According to its README, v2.0 parses and compiles projects much faster than v1, enforces a stricter language specification at parse time, produces Parquet artifacts alongside the existing JSON ones, and ships as one standalone executable, so no Python installation is needed. The local documentation experience was rebuilt around those artifacts to handle large projects.
The Apache 2.0 code is available to everyone, while the packaged dbt distribution adds dbt-specific customizations under a separate dbt product license. v2.0 supports macOS and Linux on x86-64 and ARM. The v1 Python implementation continues on the 1.latest branch. dbt Labs also offers dbt as a commercial cloud platform.
Key features
- Data transformation using software engineering practices
- Faster parsing and compiling in v2.0
- Strict language specification checks at parse time
- Parquet artifacts for querying project metadata
- Single binary without a Python runtime
- Rebuilt local documentation experience
Pricing: A single-seat Developer plan to start free. Starter costs $100 per user per month; Enterprise and Enterprise+ are custom. A trial is available and add-ons are billed on usage.
#5
An open-source ETL and ELT platform built on DuckDB that you deploy yourself, with visual or SQL pipelines, dbt, CDC, data quality and an MCP server.
- GitHub stars
- 1.6k
- Last commit
- today
- Latest release
- v0.8.0
- Licence
- Apache-2.0
- Self-hosted
- Yes
duckle.org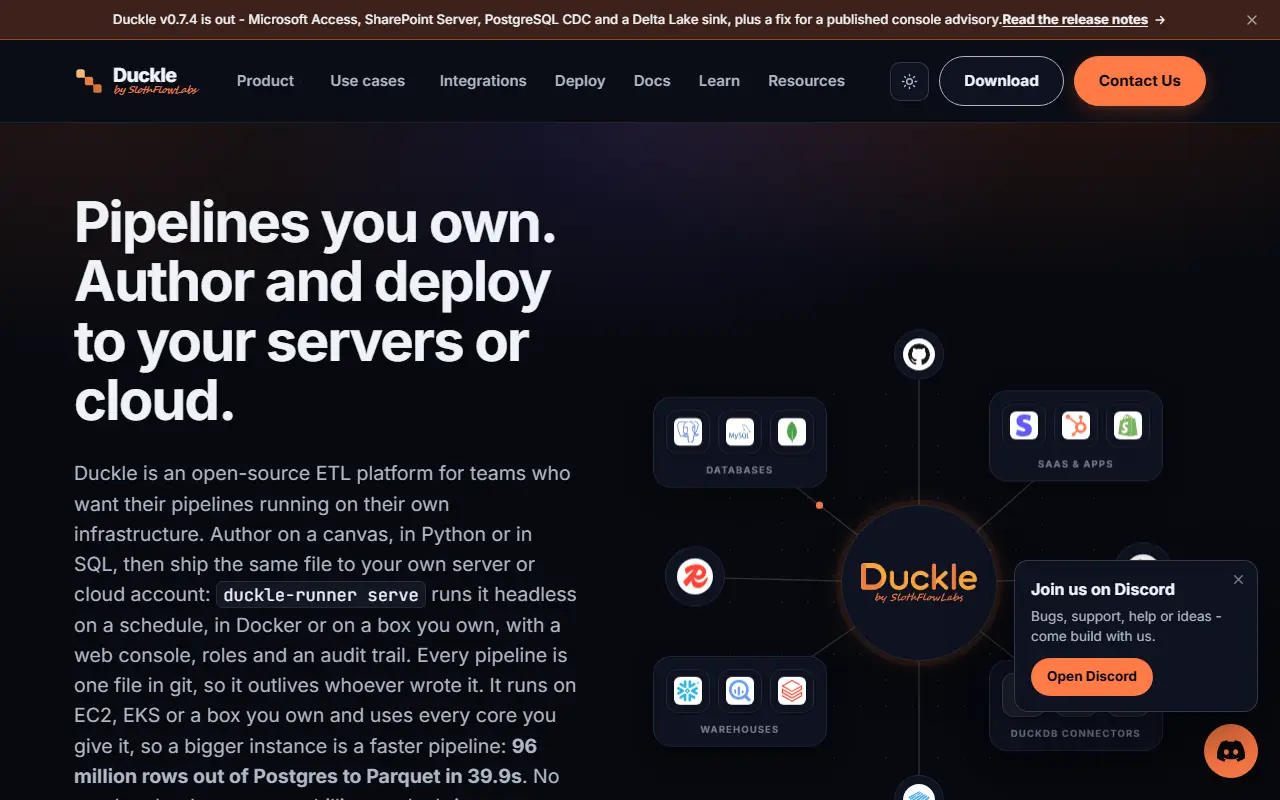
Duckle is an open-source ETL and ELT platform for teams that want their data pipelines running on their own infrastructure. You build pipelines on a visual canvas, in Python or in SQL, then ship the same file to your own server or cloud account, where a headless runner executes it on a schedule.
Pipelines compile to SQL on DuckDB and use all the cores available, so a larger machine runs them faster. The platform lists support for a large catalog of components, dbt, change data capture, data quality checks, reverse ETL and lineage, along with a web console, roles, an audit trail and an MCP server so AI agents such as Claude or Cursor can work with it. Each pipeline is a single file that can live in git.
Duckle is written in Rust and licensed under Apache-2.0, and it runs headless in Docker or on a plain server, with Kubernetes among its topics. It states there is no vendor cloud and no per-row billing. It is an independent project by SlothFlowLabs and is not affiliated with DuckDB Labs or MotherDuck. It suits data engineers who want a self-hosted alternative to managed pipeline services.
Key features
- Visual canvas, Python, or SQL pipeline authoring
- Runs on DuckDB across all CPU cores
- dbt, CDC, and reverse ETL support
- Data quality checks and lineage
- Web console with roles and audit trail
- MCP server for AI agents
Pricing: Free and open source under the Apache-2.0 licence, with no vendor cloud or per-row billing according to the README.
#6
Mage is an open-source data pipeline tool for building, scheduling and debugging ETL and transformation jobs in Python, SQL or R through a notebook-style UI.
- GitHub stars
- 8.8k
- Last commit
- 20 days ago
- Latest release
- 0.9.80
- Licence
- Apache-2.0
- Self-hosted
- Yes
- Hosted version
- Available
mage.ai
Mage, called Mage OSS in its README, is a self-hosted development environment for building data pipelines. It is meant for teams that automate ETL tasks, design data flows or orchestrate transformations, and it presents the work in a notebook-style interface made of modular blocks of code.
Pipelines are written block by block in Python, SQL or R. Jobs can be run manually or on a schedule, including cron expressions, and prebuilt connectors reach databases, APIs and cloud storage. Debugging is visual, with logs, live data previews and execution you can follow step by step, and dbt models can be built and run inside Mage. Topics on the repository also reference Spark, reverse ETL and machine learning workloads.
Mage OSS is licensed under Apache-2.0 and installs with Docker, pip or conda, with no cloud account required. For larger deployments the vendor offers Mage Pro, a commercial platform that adds enterprise orchestration, collaboration and AI-assisted workflows.
Key features
- Modular pipelines in Python, SQL or R
- Notebook-style interactive editor
- Prebuilt connectors for databases, APIs and storage
- Manual and cron-based scheduling
- Visual debugging with logs and previews
- dbt model support inside pipelines
Pricing: Managed Mage starts at $29 per month (Starter) and $100 per month (Team), plus $0.50 per CPU-hour, with a 7-day free trial. Enterprise is by contract.
#7
An open-source data pipeline tool that combines ingestion, SQL and Python transformations, and quality checks in one framework you can run locally or in CI.
- GitHub stars
- 1.8k
- Last commit
- today
- Latest release
- v0.11.821
- Licence
- Apache-2.0
- Self-hosted
- Yes
getbruin.com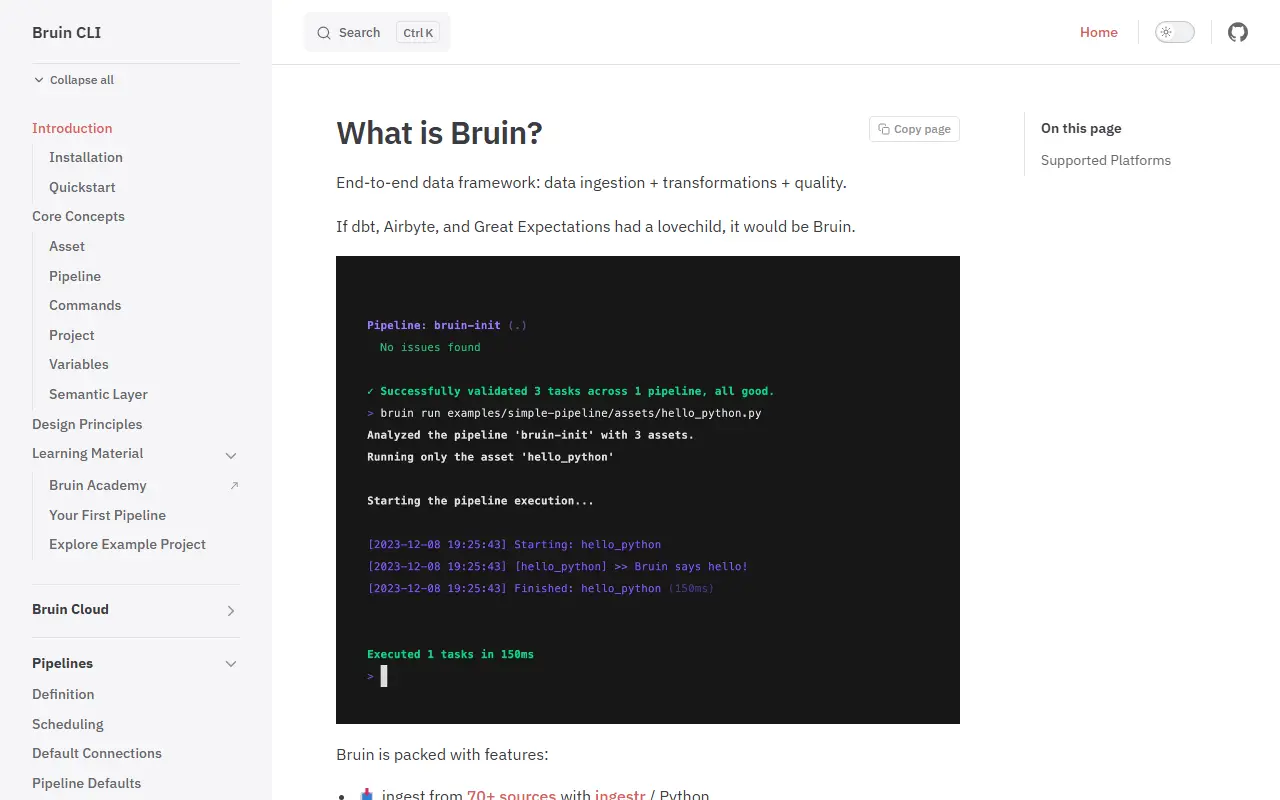
Bruin is a data pipeline tool that brings data ingestion, transformation and data quality into a single framework. Instead of stitching together separate tools for loading, modeling and testing, you describe a pipeline with SQL, Python or R assets and run it against the major data platforms, such as BigQuery and Snowflake.
Pipelines can ingest data from different sources, materialize tables and views, and build incremental tables. Python assets run in isolated environments using uv, Jinja templating cuts down on repetition, and built-in quality checks validate results. A dry-run mode validates a pipeline end to end, secrets are injected through environment variables, and a VS Code extension supports day-to-day development.
Bruin is written in Go, licensed under Apache-2.0 and distributed as a command-line tool that is easy to install. It runs on your local machine, an EC2 instance or GitHub Actions, so no dedicated orchestration server is required. It suits data engineers and analytics teams who want pipelines defined as code in a repository.
Key features
- SQL, Python, and R transformations
- Data ingestion from multiple sources
- Table and view materializations with incremental loads
- Built-in data quality checks
- Dry-run validation of whole pipelines
- VS Code extension for development
Pricing: Free and open source under the Apache-2.0 licence.
#8
Apache Camel Karavan is a low-code platform and VS Code extension for visually designing, running and deploying Apache Camel integration microservices.
- GitHub stars
- 599
- Last commit
- 3 days ago
- Latest release
- 4.22.2
- Licence
- Apache-2.0
- Self-hosted
- Yes
camel.apache.org
Apache Camel Karavan is a low-code data integration platform that simplifies the Apache Camel experience by letting teams design integration microservices visually and deploy them quickly. It aims to give the full power of Apache Camel through a visual tool, from low-code use cases to pro-code projects, drawing on more than ten years of community experience.
The designer supports Enterprise Integration Patterns, over 300 integration components, a REST API designer with an OpenAPI to REST DSL generator, YAML for integrations with Java for custom code, a route designer and a topology view. The deployer provides shell scripts for building and deploying and predefined customizable configurations for different platforms, and a developer dashboard offers hot reload, live logs and tracing of exchange data. Architecturally, the Karavan app manages projects, a build container packages and runs integrations, a Git repository stores project files as the source of truth, and an image registry holds built container images.
A VS Code extension provides a local developer experience for designing and running integrations on a laptop and deploying to Kubernetes or OpenShift. The platform can be installed on Docker, Kubernetes or OpenShift, is part of the Apache Software Foundation and is licensed under Apache-2.0.
Key features
- Visual route and REST API designer
- 300+ Camel integration components
- Enterprise Integration Patterns
- Hot reload and live logs
- VS Code extension for local development
- Deployment to Docker, Kubernetes and OpenShift
Pricing: Free and open source under the Apache-2.0 license.
Informatica alternatives: questions
- What is the best open-source alternative to Informatica?
- Airflow is the top-ranked open-source alternative to Informatica on Enlisted: An Apache workflow orchestration platform where data teams author, schedule and monitor pipelines as Python code, widely used for data engineering and ELT jobs. Other strong options are Apache Spark, Airbyte, dbt and Duckle.
- What are the best commercial alternatives to Informatica?
- Fivetran, Azure Data Factory, Cyclr, Matillion and Oracle GoldenGate are among the hosted, closed-source alternatives to Informatica listed on Enlisted, which lists 37 in total. Compare their pricing and features on each tool page.
- Are these Informatica alternatives free?
- All 8 are open source, so the code is free to use under its licence, and all of them can be self-hosted on your own server or computer. 3 also offer a paid or managed cloud version if you'd rather not host it yourself.
- How is this list of Informatica alternatives ranked?
- By a score built from GitHub stars, star growth over the last 30 days and how recently the code changed. 8 of these projects shipped code in the last 30 days. Data is refreshed daily, and nobody can pay to move up.
 TrackMedia
 TrackRev