#1
An in-memory data store used as a cache, session store, data structure server, message broker and vector query engine for real-time applications.
- GitHub stars
- 77k
- Last commit
- yesterday
- Latest release
- 8.10.3
- Self-hosted
- Yes
- Hosted version
- Available
redis.io
Redis is an in-memory data store that developers use as a cache, a session store, a database and a message broker. Because data lives in memory it answers requests quickly, which makes it popular for real-time applications. The project describes itself as a cache, a data structure server, and a document and vector query engine.
Rather than just strings, it offers data structures such as lists, sets, hashes, sorted sets and JSON, with higher-level patterns built on them, such as counters, queues, leaderboards and rate limiters, plus transactions and scripting. For caching it offers multiple eviction policies along with expiry for keys and for individual hash fields. It also handles key-value, document and time series storage, vector search and messaging. Client libraries cover most languages, and redis-cli and Redis Insight provide command line and graphical access.
The source is on GitHub, written in C, and can be built from source with documented flags for allocators, TLS and more. The license is listed as 'Other' in repository metadata, so check the current terms. Redis can be run on your own servers or consumed as a cloud-hosted service from the vendor.
Key features
- Rich data types including hashes and sorted sets
- Caching with eviction and key expiration
- JSON, time series and document storage
- Vector search for AI applications
- Message broker and queue support
- Transactions and server-side scripting
Pricing: Redis Cloud has a free 30 MB tier. Essentials starts at about $5 per month ($0.007 per hour) and Pro at $0.014 per hour with a $200 monthly minimum, billed on demand.
#2
A distributed, RESTful search and analytics engine written in Java, used for full-text search, log analysis and vector search across large datasets.
- GitHub stars
- 79k
- Last commit
- today
- Latest release
- v9.5.6
- Self-hosted
- Yes
- Hosted version
- Available
elastic.co
Elasticsearch is a distributed, RESTful search engine written in Java. It stores documents as JSON, indexes them so they can be searched quickly, and exposes everything through an HTTP API, which makes it a common backbone for site search, application search and log analytics. It is built on the Apache Lucene library.
Beyond full-text queries it supports filtering, aggregations for analytics and, in recent versions, vector search for semantic and AI-assisted retrieval. Data is spread across nodes in a cluster using shards and replicas, so capacity and resilience grow by adding machines. It is the core of the Elastic Stack, usually paired with Kibana for exploration and with ingestion tools for logs and metrics.
The repository describes the project as free and open source, while its license metadata is listed as 'Other', so review the current license terms before relying on it commercially. It can be self-managed on your own servers or used as a managed service through Elastic Cloud.
Key features
- Distributed full-text search over JSON documents
- RESTful HTTP API
- Aggregations for analytics
- Vector search for semantic retrieval
- Clustering with shards and replicas

An open-source column-oriented database management system built for real-time analytical reports, available to self-host or as the managed ClickHouse Cloud service.
- GitHub stars
- 51k
- Last commit
- today
- Latest release
- v26.10.2.103-stable
- Licence
- Apache-2.0
- Self-hosted
- Yes
- Hosted version
- Available
clickhouse.com
ClickHouse is an open-source database management system built to generate analytical reports in real time. Its column-oriented storage makes scans and aggregations over very large tables efficient, which is why it is widely used for event data, logs, metrics and product analytics. It is written in C++ and queried with SQL.
The project's topics describe it as an OLAP, massively parallel and distributed system, and it is used for big data workloads where query latency matters. You can install it on Linux, macOS or FreeBSD, follow a tutorial that sets up a small cluster, or skip installation by trying ClickHouse Cloud, a managed service built by its creators. Releases arrive monthly, with a community call for each one, and there are Slack and Telegram channels for help.
ClickHouse is Apache-2.0 licensed. It is a good fit for analytics engineers and platform teams who need fast aggregations over billions of rows and are comfortable operating a database, or who prefer to hand that operation to the vendor's cloud.
Key features
- Column-oriented storage for analytics
- SQL queries over large datasets
- Distributed, massively parallel processing
- Real-time analytical reporting
- Install on Linux, macOS or FreeBSD
- Managed ClickHouse Cloud option
Pricing: The open-source distribution is free. ClickHouse Cloud is usage-based, with plans from $53 (Basic), $437 (Scale) and $571 (Enterprise) per month and a 30-day trial with $300 in credits.
#4
A fast search engine API written in Rust that adds typo-tolerant, filterable and hybrid semantic search to websites and apps, available self-hosted or as a cloud service.
- GitHub stars
- 60k
- Last commit
- yesterday
- Latest release
- v1.56.2
- Self-hosted
- Yes
- Hosted version
- Available
meilisearch.com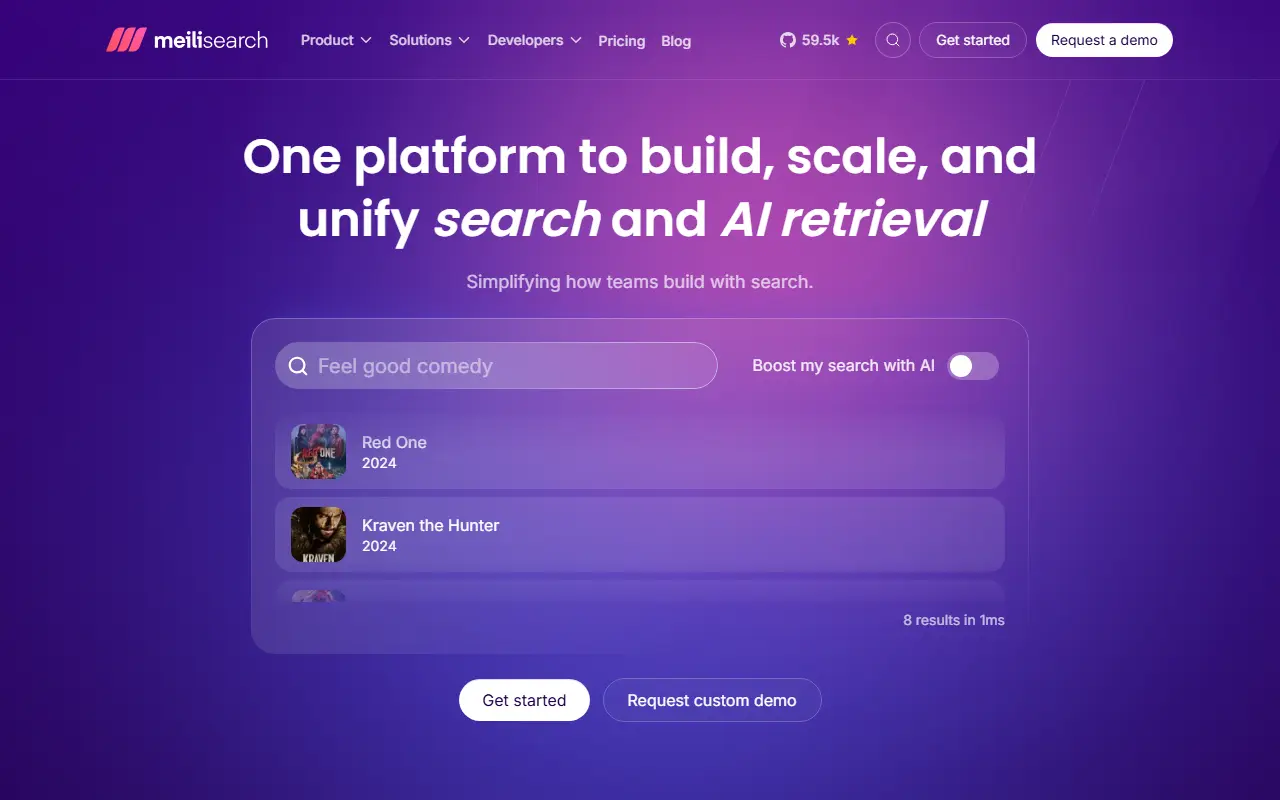
Meilisearch is a search engine exposed through an API, written in Rust and designed to be dropped into applications and websites. It aims to give developers a good search experience quickly, with features that work out of the box rather than needing extensive tuning.
Its capabilities include hybrid search that combines semantic and full-text results, search-as-you-type with a target response time under 50 milliseconds, typo tolerance, filtering and faceted search, sorting and geosearch. The topics also describe it as a vector database for AI use cases. The project maintains example applications for movies, ecommerce with facets and filters, conversational home booking, personalization and a multi-tenant CRM, which show how the features fit together.
The license is listed as 'Other', so confirm the terms for your use case. Meilisearch can be run on your own infrastructure, and Meilisearch Cloud offers it as a managed service. It is a common pick for site search, product catalogs and in-app search where a lighter alternative to a large cluster is attractive.
Key features
- Hybrid semantic and full-text search
- Instant search-as-you-type results
- Typo tolerance and fuzzy matching
- Filtering and faceted search
- Sorting and geosearch
- Vector storage for AI search
- REST API with example demo apps
Pricing: Self-hosting is free under the MIT license. Meilisearch Cloud starts at $20 per month with a 14-day free trial, billed by usage or instance resources; Enterprise is quoted on request.
#5
A multi-model database written in Rust that combines document, graph, relational, time-series and vector data with real-time features, from embedded use to distributed clusters.
- GitHub stars
- 33k
- Last commit
- 4 days ago
- Latest release
- v4.0.1
- Self-hosted
- Yes
- Hosted version
- Available
surrealdb.com
SurrealDB is a Rust-based multi-model database that brings several data models into one engine: key-value, document, graph, relational, time-series and geospatial data. Search and retrieval options include full-text, vector and hybrid, and it adds real-time and event-driven capabilities, queried through its SQL-like language, SurrealQL.
Because it supports end-user authentication, SurrealDB can also act as a backend-as-a-service, reducing the amount of server-side code an app needs. It ships as a single Rust binary that can run embedded inside an application, in the browser via WebAssembly, at the edge, as a self-hosted single node, or as a distributed cluster in the cloud. Typical workloads include data-intensive systems that need several data types, storage for AI agents, knowledge graphs, live applications such as recommenders and fraud detection, and embedded or edge deployments.
The repository license is listed as 'Other' on GitHub, so confirm the terms before commercial use. SurrealDB also offers cloud-hosted database service, and topics tag it as a serverless, realtime database for the web.
Key features
- Document, graph and relational models in one engine
- Full-text, vector and hybrid search
- Real-time and event-driven queries
- Built-in user authentication
- Single binary: embedded, edge or cluster
- SurrealQL SQL-like query language
Pricing: The Start plan includes one free instance with 1GB of storage; extra instances are from $0.021 per hour. Scale is $0.192 per node hour with a three-node minimum; self-hosted Enterprise is custom.
#6
A fast, typo-tolerant, in-memory search engine for site and app search, pitched as an open-source Algolia alternative and an easier-to-run Elasticsearch alternative.
- GitHub stars
- 27k
- Last commit
- 2 days ago
- Latest release
- v30.2
- Licence
- GPL-3.0
- Self-hosted
- Yes
- Hosted version
- Available
typesense.org
Typesense is an open-source search engine for building fast, typo-tolerant search experiences in websites and applications. It is pitched as an open-source substitute for Algolia and Pinecone, and as a simpler option than Elasticsearch. It keeps its index in memory and is written in C++.
The project's feature topics include typo tolerance and fuzzy matching, full-text search, faceting, geosearch, synonyms, merchandising rules and instant search, and it supports semantic and hybrid search. Public demos let you try it on large datasets, such as 32 million songs from MusicBrainz, 28 million books from OpenLibrary, a recipe set, Linux kernel commit messages, an ecommerce store experience, a geosearch listing browser and semantic search over Hacker News comments.
Typesense is licensed under GPL-3.0 and can be run on your own servers, and a managed Typesense Cloud service is also available. Documentation, a roadmap, a Slack community and video introductions are provided. It suits developers who want Algolia-style search with the option to self-host and keep costs predictable.
Key features
- Typo-tolerant, in-memory search
- Faceting, filtering and synonyms
- Geosearch for location-based results
- Semantic and hybrid search
- Merchandising controls for ranking
- Self-hosted or Typesense Cloud

A graph database that stores data as connected nodes and relationships and is queried with the Cypher language, widely used for highly connected data.
- GitHub stars
- 17k
- Last commit
- 7 days ago
- Latest release
- 3.2.0-alpha08
- Licence
- GPL-3.0
- Self-hosted
- Yes
- Hosted version
- Available
neo4j.com
Neo4j is a graph database written in Java. Instead of tables, it stores data as nodes and relationships, which makes it a good fit for problems where the connections between records matter, such as social networks, fraud detection, recommendations and knowledge graphs. Data is queried with Cypher, the graph query language associated with the project.
The repository contains the open-source community edition of the database engine. Topics tag it as a NoSQL graph database and graphdb, and the project's tagline is simply that graphs are for everyone. The repository's homepage could not be fetched while preparing this entry, so details here are limited to the repository description and widely known facts about the product.
The community edition is licensed under GPL-3.0, while commercial editions with additional enterprise features and a managed cloud service are sold by Neo4j, Inc. You can run the database on your own servers or use the hosted service. It is aimed at developers and data teams modeling relationship-heavy data.
Key features
- Native graph storage with nodes and relationships
- Cypher query language
- NoSQL graph database engine
- Community edition source code
- Suited to connected-data problems
Pricing: A free AuraDB tier exists. Professional starts at $0.09 per GB per hour and Business Critical at $0.20 per GB per hour; Virtual Dedicated Cloud is quoted on request.
#8
A horizontally scalable, distributed graph database with native GraphQL support, ACID transactions and consistent replication, written in Go.
- GitHub stars
- 22k
- Last commit
- 7 days ago
- Latest release
- v25.5.1
- Licence
- Apache-2.0
- Self-hosted
- Yes
dgraph.io
Dgraph is a distributed database that stores data as a graph while exposing it through GraphQL. It scales horizontally across machines and offers ACID transactions, consistent replication and linearizable reads, so a cluster behaves predictably even as it grows.
The project was built from scratch around the way graph data is laid out on disk, which it says reduces disk seeks and network calls in a cluster and improves query performance and throughput. The stated aim is production-level scale with latency low enough to answer live user queries across terabytes of structured data. Clients send queries in GraphQL syntax and receive JSON or Protocol Buffers over gRPC and HTTP. Topics point to uses such as knowledge graphs.
Dgraph is written in Go and licensed under Apache-2.0. The README describes it as production-ready at version 25 and in use at multiple large companies, and it officially supports Linux on amd64 and arm64 architectures. It is a fit for teams modeling highly connected data, such as social graphs, recommendations or knowledge bases, who also want a GraphQL API.
Key features
- Native GraphQL database with graph backend
- ACID transactions across a cluster
- Consistent replication and linearizable reads
- Horizontal scaling and distribution
- JSON and Protocol Buffers responses
- gRPC and HTTP APIs
Pricing: Free and open source under the Apache-2.0 license.
#9
A high-throughput C++ NoSQL database on the Seastar framework that speaks the Apache Cassandra and Amazon DynamoDB APIs.
- GitHub stars
- 16k
- Last commit
- today
- Self-hosted
- Yes
- Hosted version
- Available
scylladb.com
ScyllaDB is a NoSQL database that implements the Apache Cassandra and Amazon DynamoDB APIs, so existing applications and drivers for those systems can talk to it. It is written in C++ on the Seastar framework and is aimed at real-time big data workloads that need high throughput and predictable latency.
The project describes a shared-nothing approach in which each CPU core manages its own slice of data, which it says increases throughput and storage capacity per machine and cuts hardware costs. Building the database is demanding: it needs a very recent C++23 compiler and many up-to-date libraries, so the project offers a frozen toolchain as a pre-configured Docker image that includes everything required. You then only need Docker or Podman to compile it.
The repository's license is listed as 'Other' on GitHub, so confirm the current terms before using it commercially. You can run ScyllaDB on your own servers or consume it as a managed cloud service from the company. It suits teams that have outgrown Cassandra's resource footprint or want a DynamoDB-compatible database they can run themselves.
Key features
- Compatible with the Cassandra API
- Compatible with the DynamoDB API
- Shared-nothing architecture on Seastar
- C++ implementation for high throughput
- Frozen Docker toolchain for building
- Self-hosted or managed cloud
Pricing: ScyllaDB Cloud comes in Standard, Professional and Premium tiers with no list prices on the page; Standard is costed with an online calculator and the other two by quote. A self-managed edition is also listed.
#10
A native multi-model database for documents, graphs and key-values, queried with an SQL-like language and including built-in search, available self-managed or as a cloud service.
- GitHub stars
- 14k
- Last commit
- today
- Self-hosted
- Yes
- Hosted version
- Available
arangodb.com
ArangoDB is a multi-model database that stores documents, graphs and key-value data in a single engine. Instead of running separate systems for each data model, applications query connected data through one SQL-like language, with JavaScript extensions available for custom logic.
Every node in a graph is a JSON document, so existing document data can be imported and relationships can be queried across multiple levels of joins. ArangoSearch, an integrated search engine, adds text search and ranking. For scale and resilience the database can shard data horizontally across machines and replicate it to cluster nodes with automatic failover.
ArangoDB can be installed from a download or started in Docker, and runs on-premises or in any cloud. The Arango Managed Platform (AMP) creates deployments on major cloud providers and can be tried for free. A free Community Edition and a commercial Enterprise Edition without a dataset size limit are offered; the repository lists its license simply as Other, so check the terms before production use.
Key features
- Document, graph and key-value data models
- SQL-like query language
- JavaScript extensions for custom logic
- ArangoSearch full-text search and ranking
- Horizontal scaling through sharding
- Replication with automatic failover
- Managed cloud deployments via AMP
Pricing: The Community Edition is open source and free for evaluation and non-commercial use. Enterprise Edition, the platform suites and the managed cloud are priced on request.
6 more MarkLogic alternatives
MarkLogic alternatives: questions
- What is the best open-source alternative to MarkLogic?
- Redis is the top-ranked open-source alternative to MarkLogic on Enlisted: An in-memory data store used as a cache, session store, data structure server, message broker and vector query engine for real-time applications. Other strong options are Elasticsearch, ClickHouse, Meilisearch and SurrealDB.
- What are the best commercial alternatives to MarkLogic?
- InterSystems IRIS, Amazon OpenSearch Service, Apple CloudKit, Back4App and Couchbase Capella are among the hosted, closed-source alternatives to MarkLogic listed on Enlisted, which lists 19 in total. Compare their pricing and features on each tool page.
- Are these MarkLogic alternatives free?
- All 16 are open source, so the code is free to use under its licence, and all of them can be self-hosted on your own server or computer. 11 also offer a paid or managed cloud version if you'd rather not host it yourself.
- How is this list of MarkLogic alternatives ranked?
- By a score built from GitHub stars, star growth over the last 30 days and how recently the code changed. 16 of these projects shipped code in the last 30 days. Data is refreshed daily, and nobody can pay to move up.
 TrackMedia
 TrackRev