#1
An in-memory data store used as a cache, session store, data structure server, message broker and vector query engine for real-time applications.
- GitHub stars
- 77k
- Last commit
- yesterday
- Latest release
- 8.10.3
- Self-hosted
- Yes
- Hosted version
- Available
redis.io
Redis is an in-memory data store that developers use as a cache, a session store, a database and a message broker. Because data lives in memory it answers requests quickly, which makes it popular for real-time applications. The project describes itself as a cache, a data structure server, and a document and vector query engine.
Rather than just strings, it offers data structures such as lists, sets, hashes, sorted sets and JSON, with higher-level patterns built on them, such as counters, queues, leaderboards and rate limiters, plus transactions and scripting. For caching it offers multiple eviction policies along with expiry for keys and for individual hash fields. It also handles key-value, document and time series storage, vector search and messaging. Client libraries cover most languages, and redis-cli and Redis Insight provide command line and graphical access.
The source is on GitHub, written in C, and can be built from source with documented flags for allocators, TLS and more. The license is listed as 'Other' in repository metadata, so check the current terms. Redis can be run on your own servers or consumed as a cloud-hosted service from the vendor.
Key features
- Rich data types including hashes and sorted sets
- Caching with eviction and key expiration
- JSON, time series and document storage
- Vector search for AI applications
- Message broker and queue support
- Transactions and server-side scripting
Pricing: Redis Cloud has a free 30 MB tier. Essentials starts at about $5 per month ($0.007 per hour) and Pro at $0.014 per hour with a $200 monthly minimum, billed on demand.
#2
A high-performance, open-source key-value data store forked from Redis before its license change, built for caching and realtime workloads with a module system.
- GitHub stars
- 28k
- Last commit
- yesterday
- Latest release
- 9.1.3
- Licence
- BSD-3-Clause
- Self-hosted
- Yes
valkey.io
Valkey is a distributed key-value database optimized for caching and other realtime workloads. It was forked from the open-source Redis project just before Redis moved to source-available licenses, and it continues as a community-driven alternative under the permissive BSD-3-Clause license.
It acts as a data structure server that mainly handles key-value workloads, supporting many native data structures along with an extensible module system for adding new structures and access patterns. The code is written in C and can be compiled with a simple make command on Linux, macOS, OpenBSD, NetBSD and FreeBSD, on both big and little endian and 32 and 64-bit systems. Support for Solaris-derived systems is limited and not guaranteed. TLS needs OpenSSL development libraries and can be built in or as a module.
The README is a quick-start only, with fuller documentation on valkey.io. Valkey is self-run software and is compatible with the Redis ecosystem of clients, so teams use it as a replacement for Redis in caching, session storage and queues when they prefer a fully open-source license.
Key features
- Distributed key-value data store
- Native data structures
- Extensible module system
- Builds on Linux, macOS and BSD systems
- TLS support built in or as a module
- Permissive BSD-3-Clause open-source license
Pricing: Free and open source under the BSD-3-Clause license.
#3
An in-memory data store written in C++ that speaks the Redis and Memcached protocols, using a multi-threaded design to use modern hardware more efficiently.
- GitHub stars
- 32k
- Last commit
- yesterday
- Latest release
- v2.1
- Self-hosted
- Yes
- Hosted version
- Available
dragonflydb.io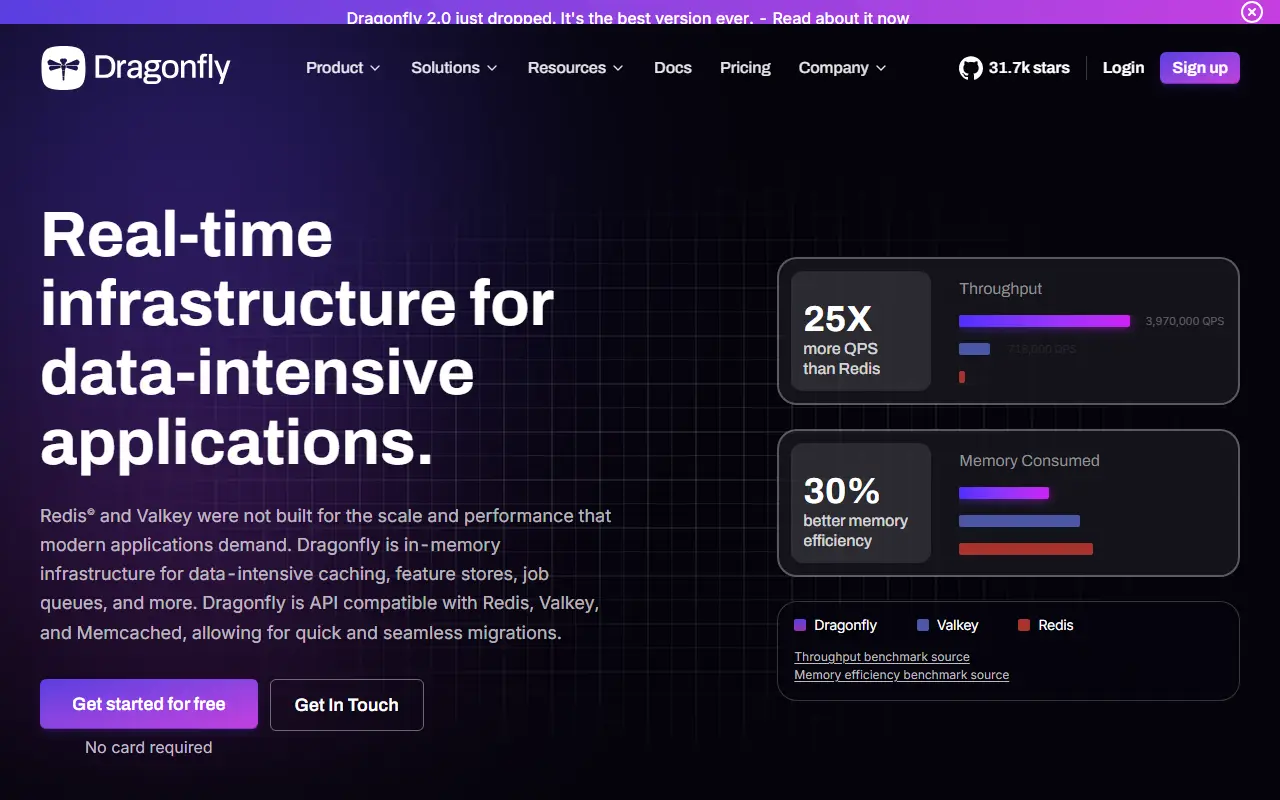
Dragonfly is an in-memory data store designed for modern application workloads and positioned as a replacement for Redis and Memcached. It implements the Redis and Memcached APIs, so existing applications and client libraries can point at it without code changes.
Unlike the single-threaded design of classic Redis, Dragonfly is multi-threaded and built around fibers, which lets one instance use many CPU cores. The project reports much higher throughput, better cache hit rates with lower tail latency and up to 80 percent fewer resources for a workload of the same size, with benchmarks against Redis on cloud instances in its documentation. Topics also link it to caching, key-value storage, message brokering and the Valkey and KeyDB ecosystems. Documentation covers a quick start, configuration, design decisions and building from source.
Dragonfly's license is listed as 'Other' on GitHub, so check the terms before using it in a commercial product. You can run it on your own servers or through Dragonfly Cloud, the company's hosted service, and a guide for AI agents is provided for tooling integration.
Key features
- Compatible with Redis and Memcached APIs
- Multi-threaded, fiber-based architecture
- Drop-in adoption without code changes
- Caching, key-value and message broker uses
- Published benchmarks against Redis
- Managed Dragonfly Cloud option
Pricing: Dragonfly Cloud Flex starts at $36 per month and Business at $2,000 per month. Self-Managed enterprise deployments are quoted on request; Flex has a free trial.
#4
A high-throughput C++ NoSQL database on the Seastar framework that speaks the Apache Cassandra and Amazon DynamoDB APIs.
- GitHub stars
- 16k
- Last commit
- today
- Self-hosted
- Yes
- Hosted version
- Available
scylladb.com
ScyllaDB is a NoSQL database that implements the Apache Cassandra and Amazon DynamoDB APIs, so existing applications and drivers for those systems can talk to it. It is written in C++ on the Seastar framework and is aimed at real-time big data workloads that need high throughput and predictable latency.
The project describes a shared-nothing approach in which each CPU core manages its own slice of data, which it says increases throughput and storage capacity per machine and cuts hardware costs. Building the database is demanding: it needs a very recent C++23 compiler and many up-to-date libraries, so the project offers a frozen toolchain as a pre-configured Docker image that includes everything required. You then only need Docker or Podman to compile it.
The repository's license is listed as 'Other' on GitHub, so confirm the current terms before using it commercially. You can run ScyllaDB on your own servers or consume it as a managed cloud service from the company. It suits teams that have outgrown Cassandra's resource footprint or want a DynamoDB-compatible database they can run themselves.
Key features
- Compatible with the Cassandra API
- Compatible with the DynamoDB API
- Shared-nothing architecture on Seastar
- C++ implementation for high throughput
- Frozen Docker toolchain for building
- Self-hosted or managed cloud
Pricing: ScyllaDB Cloud comes in Standard, Professional and Premium tiers with no list prices on the page; Standard is costed with an online calculator and the other two by quote. A self-managed edition is also listed.
#5
A native multi-model database for documents, graphs and key-values, queried with an SQL-like language and including built-in search, available self-managed or as a cloud service.
- GitHub stars
- 14k
- Last commit
- today
- Self-hosted
- Yes
- Hosted version
- Available
arangodb.com
ArangoDB is a multi-model database that stores documents, graphs and key-value data in a single engine. Instead of running separate systems for each data model, applications query connected data through one SQL-like language, with JavaScript extensions available for custom logic.
Every node in a graph is a JSON document, so existing document data can be imported and relationships can be queried across multiple levels of joins. ArangoSearch, an integrated search engine, adds text search and ranking. For scale and resilience the database can shard data horizontally across machines and replicate it to cluster nodes with automatic failover.
ArangoDB can be installed from a download or started in Docker, and runs on-premises or in any cloud. The Arango Managed Platform (AMP) creates deployments on major cloud providers and can be tried for free. A free Community Edition and a commercial Enterprise Edition without a dataset size limit are offered; the repository lists its license simply as Other, so check the terms before production use.
Key features
- Document, graph and key-value data models
- SQL-like query language
- JavaScript extensions for custom logic
- ArangoSearch full-text search and ranking
- Horizontal scaling through sharding
- Replication with automatic failover
- Managed cloud deployments via AMP
Pricing: The Community Edition is open source and free for evaluation and non-commercial use. Enterprise Edition, the platform suites and the managed cloud are priced on request.
#6
A PostgreSQL-compatible, cloud-native distributed SQL database for transactional workloads that need scale, fault tolerance or multi-region deployment.
- GitHub stars
- 11k
- Last commit
- today
- Latest release
- v2026.1.3.0
- Self-hosted
- Yes
yugabyte.com
YugabyteDB is a distributed SQL database that is compatible with PostgreSQL. It combines the relational features of traditional databases with the scale-out design of NoSQL systems, and is intended for cloud-native OLTP applications that need correct data and at least one of scalability, tolerance to failures or global distribution.
Its SQL layer, YSQL, reuses the PostgreSQL query layer and so supports most PostgreSQL features, including data types, stored procedures, triggers and extensions. Its transaction model follows the design of Google Spanner, using Raft consensus for replication and hybrid logical clocks for distributed ACID transactions, with snapshot, serializable and read committed isolation. Reads are strongly consistent by default and can be tuned to read from followers and replicas.
The database can be configured to withstand failures at the level of a disk, rack, node, zone, region or whole cloud, recovering on its own, and the topics mention multi-region, multi-cloud and Kubernetes deployments. The project is written mainly in C and C++, the repository lists its license as Other, and documentation covers architecture, roadmap and how to build applications.
Key features
- PostgreSQL-compatible SQL layer
- Distributed ACID transactions
- Replication using Raft consensus
- Snapshot, serializable and read committed isolation
- Automatic failover and repair
- Multi-region and multi-cloud deployments
- Kubernetes deployment support
Pricing: The open-source database is free. The managed Aeon service starts at $125 (Standard) or $167 (Professional) per vCPU per month plus storage and transfer, with a free trial; Enterprise is quoted.
#7
Apache Cassandra is an open-source distributed NoSQL database built for linear scalability and fault tolerance on commodity hardware or cloud infrastructure.
- GitHub stars
- 10k
- Last commit
- yesterday
- Licence
- Apache-2.0
- Self-hosted
- Yes
cassandra.apache.org
Apache Cassandra is an open-source, transactional, distributed NoSQL database. It is built to manage very large amounts of data across many machines, aiming for linear scalability and proven fault tolerance whether it runs on commodity servers or in the cloud, with no loss of performance. It is written in Java and developed under the Apache Software Foundation.
The project site presents Cassandra 5.0 along with documentation, a quickstart and community resources, and recent talks from the community cover topics such as Storage Attached Indexes, the Accord transaction protocol, mutation tracking, backups with Medusa, a sidecar process and analytics integrations. Cassandra is queried through CQL and can be run in clusters spanning racks, data centers or cloud regions.
Cassandra is licensed under Apache-2.0 and you run it yourself, either on your own servers or on cloud virtual machines or Kubernetes. It is typically chosen for write-heavy, always-on applications such as time-series data, messaging, IoT and large user-facing systems that must stay available when individual nodes fail.
Key features
- Distributed NoSQL storage
- Linear scalability across nodes
- Fault tolerance on commodity hardware
- CQL query language
- Storage Attached Indexes in 5.0
- Multi data center deployments
Pricing: Free and open source under the Apache-2.0 licence.
#8
Apache CouchDB is a document database with multi-primary replication, a JSON-over-HTTP API and an offline-first sync model that scales from servers to mobile devices.
- GitHub stars
- 7k
- Last commit
- today
- Licence
- Apache-2.0
- Self-hosted
- Yes
couchdb.apache.org
Apache CouchDB is a database that stores JSON documents and is reached through an HTTP/JSON API. Its headline feature is multi-primary sync: the Couch Replication Protocol lets data flow between server clusters, mobile phones and web browsers, which supports offline-first applications that reconcile changes when connectivity returns.
It can run as a single-node database behind an application server or as a cluster, stores binary data alongside JSON, and offers a developer-friendly query language with optional MapReduce views. The protocol is implemented by a variety of projects and products across computing environments. CouchDB is written in Erlang, known for reliability, and the homepage presents the design as built for dependable operation.
Apache CouchDB is licensed under Apache-2.0 and runs on your own servers or with any cloud provider. Documentation, a technical overview and download packages are on the project site. It suits teams building apps that must keep working offline and sync later, or that want a simple, HTTP-native document store.
Key features
- Multi-primary replication between nodes
- JSON documents over an HTTP API
- Offline-first sync to mobile and browsers
- Binary attachments alongside JSON
- Query language and MapReduce views
- Single-node or clustered deployment
Pricing: Free and open source under the Apache-2.0 licence.
#9
Apache HBase is a distributed, versioned, column-oriented database modeled on Google's Bigtable and built on top of Apache Hadoop.
- GitHub stars
- 5.6k
- Last commit
- today
- Latest release
- rel/3.0.0
- Licence
- Apache-2.0
- Self-hosted
- Yes
hbase.apache.org
Apache HBase is an open-source database that is distributed, versioned and column-oriented, modeled on the Bigtable design described in a paper by Chang and colleagues at Google. Bigtable relies on the Google File System, and in the same way HBase delivers comparable capabilities on top of Apache Hadoop and its distributed file system.
It is intended for storing very large tables across a cluster, with rows indexed by key and columns grouped into families. The project documentation includes a Reference Guide with a quick start section, downloads on the project site, and mailing lists plus a Slack channel for discussion. The code is written in Java.
HBase is an Apache Software Foundation project under the Apache-2.0 license and is deployed on your own Hadoop-based clusters, though several cloud providers also bundle it in managed big data offerings. It suits data engineering teams that need low-latency random access to large datasets.
Key features
- Distributed column-oriented storage
- Bigtable-style data model
- Runs on top of Hadoop
- Versioned cell data
- Reference guide with quick start
- Written in Java
Pricing: Free and open source under the Apache-2.0 license.
#10
Multithreaded, event-driven in-memory key/value cache used to speed up distributed applications by keeping hot data in RAM.
- GitHub stars
- 14k
- Last commit
- 2 mo ago
- Licence
- BSD-3-Clause
- Self-hosted
- Yes
memcached.org
Memcached is an in-memory key/value cache store designed for distributed systems. Applications place frequently read data, such as query results or rendered fragments, in memory so they can skip slower backends. It is a long-established building block of web infrastructure and is released as open source under the BSD-3-Clause license.
The server is written in C, uses multiple threads and an event-based design built on libevent, and keeps its interface simple. Optional build features include TLS support through OpenSSL, process restrictions on Linux through libseccomp, and an experimental proxy mode. It can be compiled from a release tarball or from the git repository using the standard autotools workflow.
The project provides documentation on its website, including a tutorial, a wiki and a guide for diagnosing timeouts and odd behavior. Questions are handled through a mailing list rather than GitHub issues. Because it is a cache, operators typically run it on dedicated machines and avoid swapping when large memory is allocated.
Key features
- In-memory key/value storage for caching
- Multithreaded, event-based server in C
- Optional TLS support via OpenSSL
- Optional libseccomp process restrictions on Linux
- Experimental proxy mode
- Builds from tarball or git source
Pricing: Free and open source under the BSD-3-Clause license.
3 more Aerospike alternatives
Aerospike alternatives: questions
- What is the best open-source alternative to Aerospike?
- Redis is the top-ranked open-source alternative to Aerospike on Enlisted: An in-memory data store used as a cache, session store, data structure server, message broker and vector query engine for real-time applications. Other strong options are Valkey, Dragonfly, ScyllaDB and ArangoDB.
- What are the best commercial alternatives to Aerospike?
- Google Cloud Bigtable, Amazon DynamoDB, Azure Cosmos DB, IBM Cloudant and Couchbase Capella are among the hosted, closed-source alternatives to Aerospike listed on Enlisted, which lists 17 in total. Compare their pricing and features on each tool page.
- Are these Aerospike alternatives free?
- All 13 are open source, so the code is free to use under its licence, and all of them can be self-hosted on your own server or computer. 4 also offer a paid or managed cloud version if you'd rather not host it yourself.
- How is this list of Aerospike alternatives ranked?
- By a score built from GitHub stars, star growth over the last 30 days and how recently the code changed. 12 of these projects shipped code in the last 30 days. Data is refreshed daily, and nobody can pay to move up.
 TrackMedia
 TrackRev