 TrackMedia
 TrackRev
About StreamNative
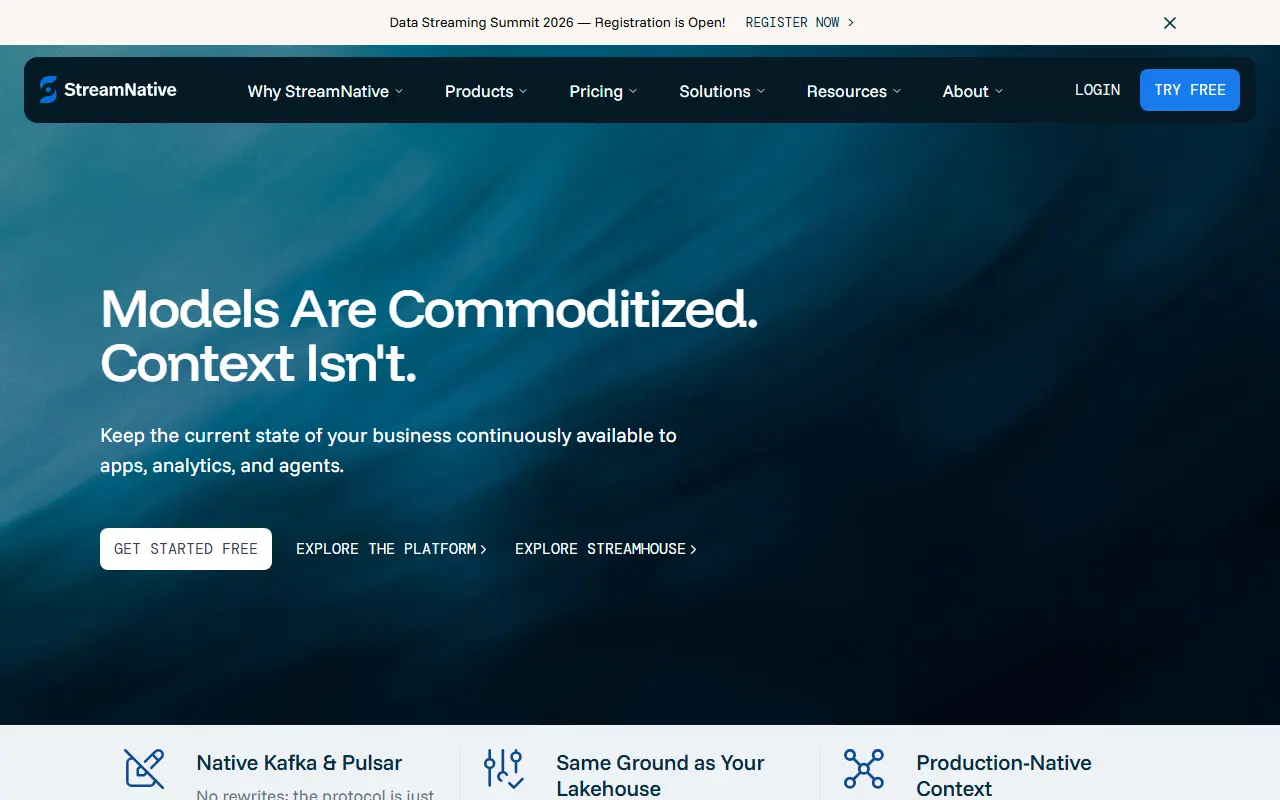
StreamNative describes its product as a streamhouse, meant to keep the current state of a business available to applications, analytics and agents. Kafka and Pulsar run on Lakestream, an open stream storage implemented by Ursa, so streams sit next to Iceberg and Delta tables on object storage.
Teams keep the Kafka and Pulsar protocols and avoid rewrites. Governance sits underneath: access scopes, audit and lineage apply to every read and action. The company aims the platform at teams that own real-time data and AI projects, including platform and infrastructure teams.
Three deployment paths are priced on its pricing page: Serverless on shared infrastructure from $73/month, Dedicated clusters on AWS, GCP or Azure from $505/month, and BYOC clusters in your own cloud account from $365/month. StreamNative manages all three.
Key features
- Native Kafka and Pulsar support without rewrites
- Streams stored alongside Iceberg and Delta tables
- Access scopes, audit and lineage on every read
- Multiple protocols: Pulsar, Kafka, MQTT, REST
- Bring-your-own-cloud clusters
- Dedicated clusters on AWS, GCP or Azure
Good fit for
- Modernizing Kafka and Pulsar clusters
- Feeding live data to applications and agents
- Running streams next to lakehouse tables
StreamNative: questions and answers
- What is StreamNative used for?
- StreamNative is a managed streaming data platform for Kafka and Pulsar, sold as serverless, dedicated or bring-your-own-cloud clusters. It is a good fit for modernizing Kafka and Pulsar clusters, feeding live data to applications and agents, and running streams next to lakehouse tables.
- Is StreamNative open source?
- No. StreamNative is proprietary (closed-source) software. In the Data Pipelines & ETL category, open-source options include Kafka, Apache Spark and Debezium.
- What are some alternatives to StreamNative?
- StreamNative competes with Confluent.
Open-source alternatives to StreamNative
See all
Kafka
Data Pipelines & ETL
Apache Kafka - A distributed event streaming platform
Apache-2.0vs Striim★ 34k
Apache Spark
Data Pipelines & ETL
Apache Spark - A unified analytics engine for large-scale data processing
Apache-2.0vs Databricks★ 44k
Debezium
Data Pipelines & ETL
Change data capture for a variety of databases. Please log issues at https://github.com/de
Apache-2.0vs Fivetran★ 13k
Logstash
Data Pipelines & ETL
Logstash - transport and process your logs, events, or other data
OSSvs Cribl★ 15k
RisingWave
Data Pipelines & ETL
Event streaming platform for agentic AI. Continuously ingest, transform, and serve event s
Apache-2.0vs Striim★ 9.4k
Delta Lake
Data Pipelines & ETL
An open-source storage framework that enables building a Lakehouse architecture with compu
Apache-2.0vs Snowflake★ 9.1k
SaaS alternatives to StreamNative
See all
Confluent
Data Pipelines & ETL
Managed Apache Kafka platform for streaming data in the cloud
SaaS
Amazon Kinesis
Data Pipelines & ETL
AWS services for collecting, processing and analyzing real-time streaming data
SaaS
Estuary
Data Pipelines & ETL
Real-time data pipeline platform that unifies CDC, streaming and batch ELT
SaaS
Google Cloud Dataflow
Data Pipelines & ETL
Managed stream and batch data processing service on Google Cloud based on Apache Beam
SaaS
Striim
Data Pipelines & ETL
Real-time data integration and streaming platform with change data capture
SaaS
Oracle GoldenGate
Data Pipelines & ETL
Real-time data replication and change data capture software from Oracle
SaaS