 TrackMedia
 TrackRev
About Gobblin
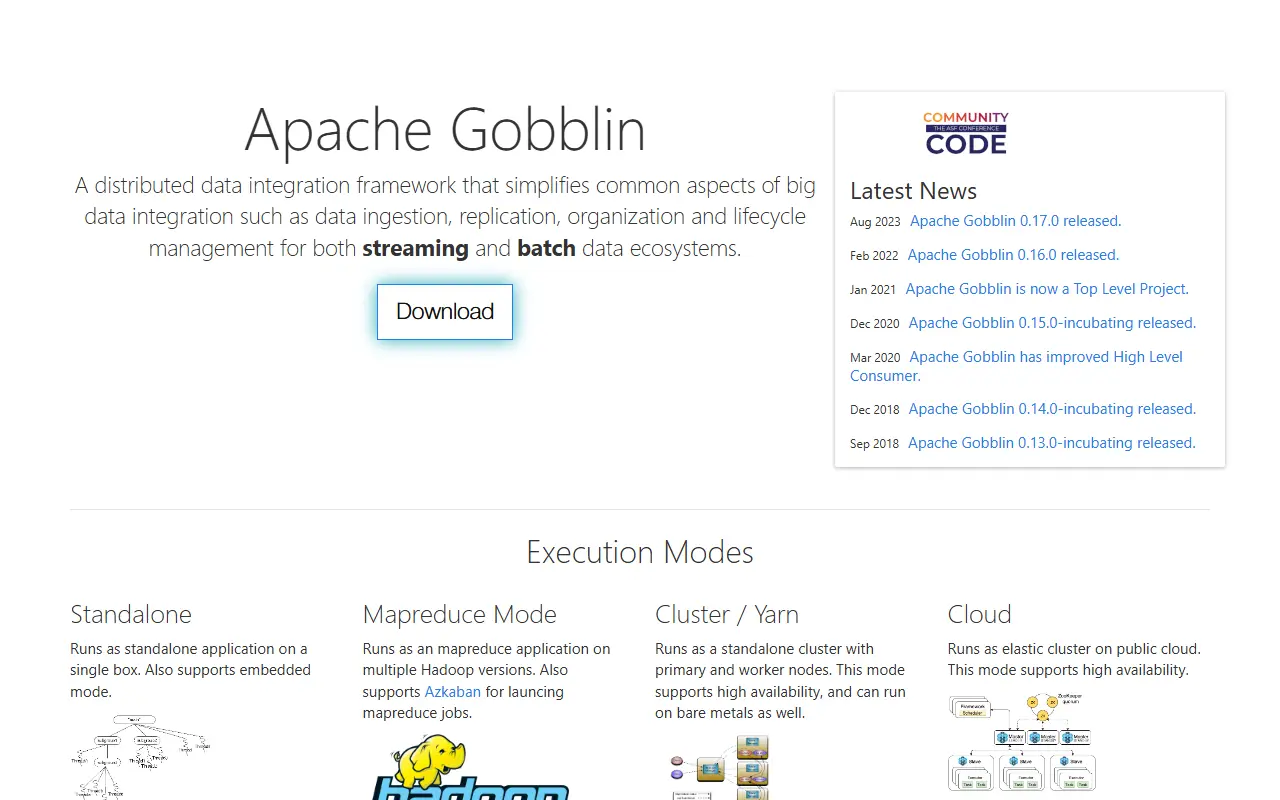
Apache Gobblin is a distributed framework for big data integration. It simplifies common work such as data ingestion, replication, organisation and lifecycle management, for both streaming and batch data ecosystems. It became an Apache Top Level Project in January 2021.
It can run in several execution modes. Standalone mode runs as a single application on one machine and also supports an embedded mode. MapReduce mode runs as a MapReduce application on multiple Hadoop versions, with Azkaban supported for launching jobs. A cluster mode using YARN has primary and worker nodes and supports high availability.
A cloud mode runs as an elastic cluster on a public cloud, also with high availability. The news list on the site shows releases from 0.13.0-incubating in 2018 up to 0.17.0 in August 2023, and the project is published by the Apache Software Foundation under the Apache licence.
Key features
- Data ingestion, replication and lifecycle management
- Handles both streaming and batch data
- Standalone mode on a single machine
- MapReduce mode across Hadoop versions
- Elastic cluster mode on public cloud
Good fit for
- Ingesting data into Hadoop or cloud stores
- Replicating datasets
- Managing data lifecycle
Gobblin: questions and answers
- What is Gobblin used for?
- Gobblin is a distributed data integration framework for ingestion, replication and lifecycle management of streaming and batch data. It is a good fit for ingesting data into Hadoop or cloud stores, replicating datasets and managing data lifecycle.
- Is Gobblin open source?
- Yes. Gobblin is open source under the Apache-2.0 licence. Its source code is on GitHub at apache/gobblin and is written mainly in Java.
- Is Gobblin free?
- Yes. Gobblin is open source, so the software itself is free to use.
- Can I self-host Gobblin?
- Yes. Gobblin can be self-hosted on your own server or infrastructure.
- What is Gobblin an alternative to?
- Gobblin is an open-source alternative to Google Cloud Dataflow. Other open-source alternatives to Google Cloud Dataflow include Apache Spark, Kafka and Airflow.
- Is Gobblin actively maintained?
- Yes. The most recent commit to Gobblin was on 15 October 2026. The project has 2.3k stars on GitHub, with 1 added in the last 30 days.
Open-source alternatives to Gobblin
See all
Apache Spark
Data Pipelines & ETL
Apache Spark - A unified analytics engine for large-scale data processing
Apache-2.0vs Databricks★ 44k
Kafka
Data Pipelines & ETL
Apache Kafka - A distributed event streaming platform
Apache-2.0vs Striim★ 34k
Airflow
Data Pipelines & ETL
Apache Airflow - A platform to programmatically author, schedule, and monitor workflows
Apache-2.0vs Astronomer★ 47k
RisingWave
Data Pipelines & ETL
Event streaming platform for agentic AI. Continuously ingest, transform, and serve event s
Apache-2.0vs Striim★ 9.4k
Beam
Media & Streaming
Apache Beam is a unified programming model for Batch and Streaming data processing.
Apache-2.0vs Matillion★ 8.7k
Flink
Open source
Apache Flink
Apache-2.0vs Matillion★ 26k
SaaS alternatives to Gobblin
See all
Google Cloud Dataflow
Data Pipelines & ETL
Managed stream and batch data processing service on Google Cloud based on Apache Beam
SaaS
Amazon EMR
Data Pipelines & ETL
Managed big data platform on AWS for running Spark, Hive, Presto and other frameworks
SaaS
Estuary
Data Pipelines & ETL
Real-time data pipeline platform that unifies CDC, streaming and batch ELT
SaaS
Amazon Kinesis
Data Pipelines & ETL
AWS services for collecting, processing and analyzing real-time streaming data
SaaS
AWS Glue
Data Pipelines & ETL
Serverless data integration service on AWS for ETL jobs and data catalogs
SaaS
Azure Data Factory
Data Pipelines & ETL
Managed Azure service for building data integration and ETL pipelines
SaaS