7,363 open-source and SaaS tools, with GitHub stats refreshed every day.

13 alternatives ranked by real activity

Open-source Splunk alternatives

A curated, ranked list of the 13 best open-source alternatives to Splunk.

The best open-source alternative to Splunk is Elasticsearch. If that doesn't suit you, other good options are Grafana, Grafana Loki, OpenObserve and Kibana.

Splunk alternatives are mainly monitoring & observability tools, but some are also search tools and security tools. 13 of them shipped code in the last 30 days, 13 can be self-hosted, and 5 use a permissive licence.

Last updated October 2, 2026 ยท ranked by GitHub stars, growth and recent commits

Elasticsearch

A distributed, RESTful search and analytics engine written in Java, used for full-text search, log analysis and vector search across large datasets.

GitHub stars
78k
Last commit
today
Latest release
v9.5.4
Self-hosted
Yes
Hosted version
Available
elastic.coElasticsearch homepage screenshot

Elasticsearch is a distributed, RESTful search engine written in Java. It stores documents as JSON, indexes them so they can be searched quickly, and exposes everything through an HTTP API, which makes it a common backbone for site search, application search and log analytics. It is built on the Apache Lucene library.

Beyond full-text queries it supports filtering, aggregations for analytics and, in recent versions, vector search for semantic and AI-assisted retrieval. Data is spread across nodes in a cluster using shards and replicas, so capacity and resilience grow by adding machines. It is the core of the Elastic Stack, usually paired with Kibana for exploration and with ingestion tools for logs and metrics.

The repository describes the project as free and open source, while its license metadata is listed as 'Other', so review the current license terms before relying on it commercially. It can be self-managed on your own servers or used as a managed service through Elastic Cloud.

Key features

  • Distributed full-text search over JSON documents
  • RESTful HTTP API
  • Aggregations for analytics
  • Vector search for semantic retrieval
  • Clustering with shards and replicas
Grafana

An open-source platform for visualizing metrics, logs and traces from many data sources, with dashboards, alerting and ad-hoc exploration.

GitHub stars
77k
Last commit
today
Latest release
v13.2.3
Licence
AGPL-3.0
Self-hosted
Yes
Hosted version
Available
grafana.comGrafana homepage screenshot

Grafana is a visualization and observability platform that lets you query, chart and alert on data wherever it is stored. It does not hold your data itself; it connects to sources such as Prometheus, Loki, Elasticsearch, InfluxDB, MySQL and PostgreSQL and brings their results together in shared dashboards.

Dashboards can be made reusable with template variables that appear as dropdowns, and a single graph may mix queries against different data sources. Explore views support ad-hoc queries, side-by-side comparison of time ranges and a jump from metrics to logs while keeping label filters. Alert rules are defined visually, and notifications go to systems like Slack, PagerDuty, VictorOps and OpsGenie. Panel plugins add further visualization types.

Grafana is AGPL-3.0 licensed, written in Go and TypeScript, and can be installed on your own servers; Grafana Labs also runs a hosted offering. It is common in DevOps and SRE teams as the dashboard layer on top of Prometheus-style monitoring, and a public demo site lets you try it first.

Key features

  • Dashboards with template variables
  • Mixed data sources in a single graph
  • Visual alert rules with Slack and PagerDuty
  • Explore view for ad-hoc metric and log queries
  • Panel plugins for extra visualizations
  • Connects to Prometheus, Loki and SQL databases

Pricing: Grafana Cloud has an always-free tier with usage limits. Pro starts at $19 per month plus usage; Enterprise starts at a $25,000 annual spend commit and is sold through sales.

Grafana Loki

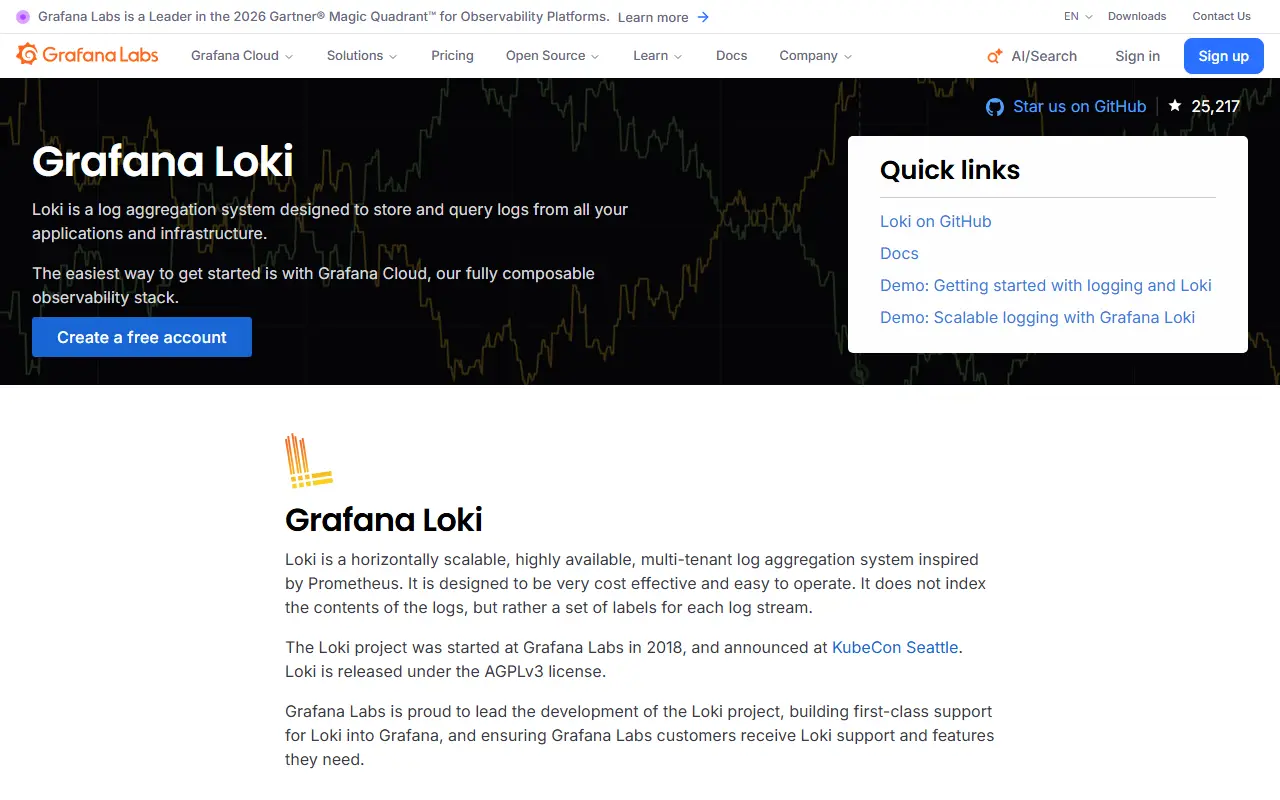
Grafana Loki is a horizontally scalable log aggregation system that indexes labels instead of log contents, inspired by Prometheus.

GitHub stars
29k
Last commit
today
Latest release
v3.7.8
Licence
AGPL-3.0
Self-hosted
Yes
Hosted version
Available
grafana.comGrafana Loki homepage screenshot

Loki is a log aggregation system from Grafana, described as Prometheus for logs. It is horizontally scalable, highly available and multi-tenant. Instead of indexing the contents of log lines, it indexes a set of labels for each log stream and stores the compressed log text, which the project says makes it simpler to operate and cheaper to run. It is written in Go and released under the AGPL-3.0 license.

Because Loki reuses the labels familiar from Prometheus, you can move between metrics and logs using the same label sets, and it has native support in Grafana. It works especially well for Kubernetes pod logs, since metadata such as pod labels is scraped and indexed automatically. A typical stack has three parts: Alloy as the collection agent, Loki for storage and queries, and Grafana for exploration. Alloy replaces Promtail, which is considered feature complete. Unlike Prometheus, Loki receives logs by push.

Key features

  • Label-based indexing instead of full-text indexing
  • Horizontally scalable, multi-tenant architecture
  • Native Grafana integration for querying logs
  • Automatic Kubernetes pod label indexing
  • Grafana Alloy agent for log collection
  • Single-binary deployment option

Pricing: Free and open source under the AGPL-3.0 license.

OpenObserve

A cloud-native observability platform covering logs, metrics, traces, RUM and LLM monitoring, with Parquet columnar storage on S3 and a pitch against Datadog and Splunk.

GitHub stars
22k
Last commit
today
Latest release
v1.1.0-rc1
Licence
AGPL-3.0
Self-hosted
Yes
Hosted version
Available
openobserve.aiOpenObserve homepage screenshot

OpenObserve, often shortened to O2, is open-source observability software spanning logs, metrics, traces and analytics, real user monitoring on web, Android and iOS, session replay, pipelines, SLOs and AI and LLM observability. It is pitched as a lower-cost option next to Datadog, Splunk and Elasticsearch for teams that want complete observability without the complexity or price.

Its architecture uses Parquet columnar storage and an S3-native design, which the project says can cut storage costs by up to 140 times compared with Elasticsearch, with petabyte-scale capacity. Topics reference OpenTelemetry, Prometheus, Jaeger and Kibana, showing the standards and tools it interoperates with. The README has sections on architecture, comparisons, production readiness, security and compliance, and an enterprise edition.

OpenObserve is AGPL-3.0 licensed, with a hosted cloud option and a self-hosted deployment, and documentation and a Slack community are provided. It suits engineering teams looking to consolidate logging, metrics and tracing in one tool while keeping storage costs under control.

Key features

  • Logs, metrics and traces in one platform
  • Real user monitoring and session replay
  • LLM and AI observability
  • Parquet columnar storage on S3
  • OpenTelemetry and Prometheus compatibility
  • Pipelines and SLO tracking

Pricing: Self-hosting is free. Cloud is pay-as-you-go at $0.50 per GB ingested plus $0.01 per GB queried, with unlimited users and a 14-day trial; Enterprise is custom.

Kibana

Kibana is the web interface for querying, visualizing and managing data stored in Elasticsearch, used for dashboards, observability and analytics.

GitHub stars
21k
Last commit
today
Latest release
v9.5.4
Self-hosted
Yes
Hosted version
Available
elastic.coKibana homepage screenshot

Kibana is the user interface that sits on top of Elasticsearch. It lets people query, analyze, visualize and manage the data stored there, turning indexes into charts, metrics views and dashboards. It is part of the Elastic Stack and is commonly used for log analysis, observability and general analytics work.

Teams build visualizations and assemble them into shared dashboards, explore documents with search, and use the interface to manage parts of an Elasticsearch deployment. The project advises running Kibana and Elasticsearch at the same version, with major versions required to match, because mismatches can cause problems and support may ask for an upgrade first.

The code is written in TypeScript. The repository lists its license as 'Other' rather than a standard SPDX identifier, so the license files should be read for the exact terms. Kibana can be downloaded and run on your own infrastructure, and Elastic also offers a hosted version through its Cloud service.

Key features

  • Query and explore Elasticsearch data
  • Visualizations and metrics charts
  • Shared dashboards for monitoring
  • Observability views for logs and metrics
  • Management tools for Elasticsearch data
  • Hosted option through Elastic Cloud

Wazuh

Wazuh is a free, open-source security platform combining XDR and SIEM capabilities for endpoints, servers and cloud workloads.

GitHub stars
17k
Last commit
today
Latest release
v4.14.8
Self-hosted
Yes
wazuh.comWazuh homepage screenshot

Wazuh is a free and open-source platform for threat prevention, detection and response. It protects workloads across on-premises, virtualized, containerized and cloud environments and combines XDR and SIEM functions in one product. The code is written mainly in C++.

The solution consists of an endpoint security agent installed on monitored systems and a management server that collects and analyzes the agents' data. It is integrated with the Wazuh Indexer, which offers a search engine and visualization for navigating security alerts. Agents scan for malware, rootkits and suspicious anomalies, read system and application logs, and monitor files for changes to content, permissions, ownership and attributes.

Rule-based analysis of collected logs, including data received from network devices through syslog, helps surface misconfigurations, policy violations and attempted or successful attacks. Repository topics also cover vulnerability detection, configuration assessment, incident response and compliance such as PCI DSS. The repository lists its license as 'Other', so review the license files for the exact terms.

Key features

  • Endpoint agents with a central management server
  • Intrusion and malware detection
  • Log data analysis with rule-based alerts
  • File integrity monitoring
  • Vulnerability detection and configuration assessment
  • Cloud and container workload coverage

OpenSearch

An Apache-licensed, distributed and RESTful search engine and observability suite for searching, analyzing and monitoring large volumes of unstructured data.

GitHub stars
14k
Last commit
yesterday
Latest release
3.9.0
Licence
Apache-2.0
Self-hosted
Yes
Hosted version
Available
opensearch.orgOpenSearch homepage screenshot

OpenSearch is an open-source search and observability suite that makes large amounts of unstructured data searchable and analyzable. It is a distributed engine with a RESTful API, written in Java, and developed in the open by the OpenSearch community under the Apache 2.0 licence.

Teams use it for full-text search, log and event analytics, and monitoring of applications and infrastructure. The project provides downloads, documentation, forums and Slack channels, and it follows a formal release and maintainer process. Because it is distributed, clusters can be scaled across multiple nodes as data volumes grow.

OpenSearch includes certain Apache-licensed code derived from Elasticsearch, as its trademark notice explains. You can run it on your own servers, or use managed services offered by cloud providers. Security issues are reported privately by email rather than through public issues, and the project maintains a code of conduct for contributors.

Key features

  • Distributed search with a RESTful API
  • Full-text search over unstructured data
  • Log and event analytics
  • Observability and monitoring use cases
  • Scales across nodes in a cluster
  • Apache 2.0 licensed Java codebase

Pricing: Free and open source under Apache 2.0; managed hosting is available from cloud providers.

Quickwit

A cloud-native open-source search engine for observability data, built in Rust to index logs and traces on object storage with an Elasticsearch-compatible API.

GitHub stars
12k
Last commit
yesterday
Latest release
v0.9.1
Licence
Apache-2.0
Self-hosted
Yes
quickwit.ioQuickwit homepage screenshot

Quickwit is an open-source, cloud-native search engine designed for observability, covering log management and distributed tracing, with metrics support listed on the roadmap. It is written in Rust, builds on the Tantivy search library, and is meant to search large volumes of data kept in cheap object storage.

It provides full-text search and aggregation queries, schemaless or strict-schema indexing, and a RESTful API that is compatible with a large subset of the Elasticsearch and OpenSearch APIs, so existing clients can often be reused. It is native to Jaeger and OpenTelemetry, works as a Grafana data source and can ingest from Kafka, Kinesis and Pulsar. Compute and storage are decoupled, with stateless indexers and searchers, and data can sit on Amazon S3, Azure Blob Storage or Google Cloud Storage.

Operational features include multi-tenancy with many indexes, partitioning, retention policies and delete tasks for GDPR use cases, and a Helm chart for Kubernetes. Quickwit is licensed under Apache-2.0 and you run it yourself. It suits teams looking for lower-cost log and trace storage with a familiar search API.

Key features

  • Full-text search and aggregation queries
  • API compatible with Elasticsearch clients
  • Native Jaeger and OpenTelemetry support
  • Search directly on cloud object storage
  • Decoupled compute and storage
  • Ingestion from Kafka, Kinesis and Pulsar
  • Retention policies and GDPR delete tasks
  • Helm chart for Kubernetes

Pricing: Free and open source under the Apache-2.0 licence.

Graylog

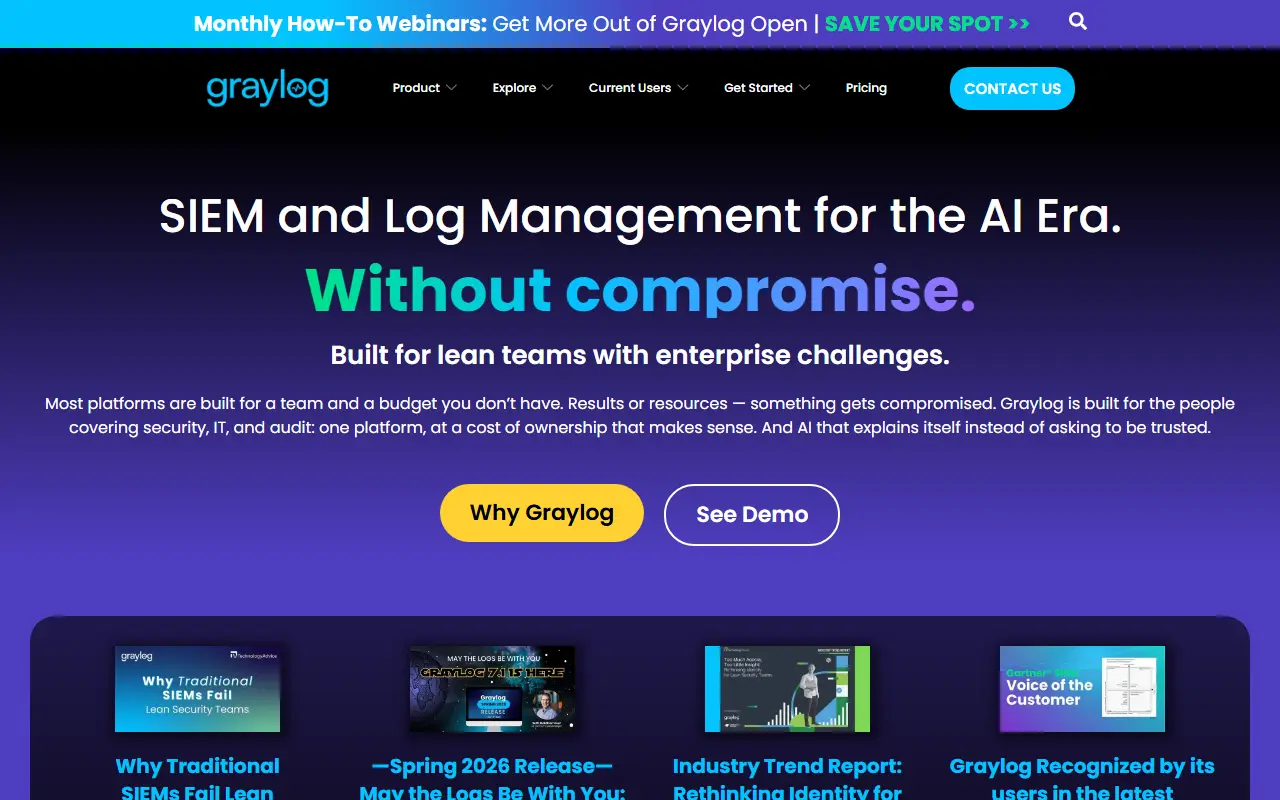
Graylog is a free, open log management platform written in Java that collects, searches and analyzes logs, with a focus on security use cases.

GitHub stars
8.2k
Last commit
today
Self-hosted
Yes
graylog.orgGraylog homepage screenshot

Graylog is a log management server written in Java and described by its maintainers as free and open. It centralizes log data from many systems so teams can search, view and analyze events in one place instead of connecting to each machine individually.

The repository topics point to support for common log formats and transports, including GELF and syslog, along with Kafka and AMQP inputs. Topics also place the project in log analysis, log collection, secure logging and SIEM territory, which reflects its use for monitoring and security work. Specific features were not available when this entry was written, because the vendor website could not be read.

Key features

  • Centralized log collection and search
  • GELF and syslog input formats
  • Kafka and AMQP integration
  • Log analysis and viewing
  • Security-oriented logging

GreptimeDB

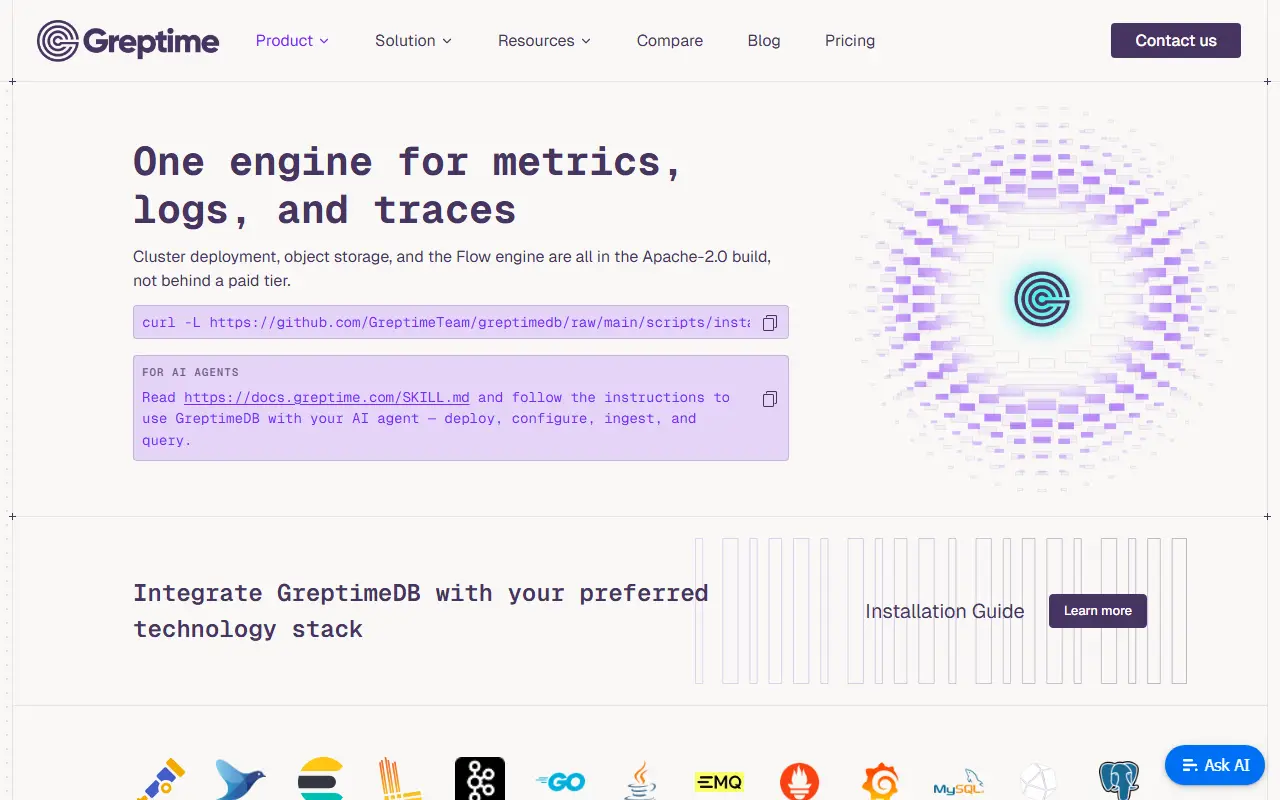
GreptimeDB is an open-source observability database that stores metrics, logs and traces in one columnar engine on object storage, queryable with SQL and PromQL.

GitHub stars
6.7k
Last commit
today
Latest release
v1.2.1
Licence
Apache-2.0
Self-hosted
Yes
greptime.comGreptimeDB homepage screenshot

GreptimeDB is an open-source observability database in which metrics, logs and traces share one columnar engine over object storage and one table model of tags, timestamp and fields. When signals share identifiers like service name, host or trace ID, they can be correlated with SQL joins rather than shuttling data between databases.

Ingestion works through OpenTelemetry, Prometheus Remote Write, the Loki push API or Elasticsearch Bulk, and queried with SQL across all signals and PromQL for metrics, so ingestion can migrate one signal at a time without rebuilding collectors. The README lists reasons to use it: replacing a Prometheus plus Loki or Elasticsearch combination with one backend, outgrowing Prometheus on cardinality or retention without the Thanos or Mimir complexity, long retention on object storage, and storing GenAI telemetry next to infrastructure signals.

GreptimeDB is written in Rust, with an Apache-2.0 licensed core, and is run self-hosted on your own infrastructure. Stable, canary and nightly builds are offered. It suits platform and SRE teams wanting a consolidated, cost-conscious observability backend.

Key features

  • Metrics, logs and traces in one engine
  • Columnar storage on object storage
  • SQL and PromQL queries
  • Ingestion via OpenTelemetry and Prometheus
  • Loki and Elasticsearch ingestion APIs
  • High-cardinality data support

Pricing: The open-source core is free to self-run. Fully-managed Enterprise starts at $290 per month; the bring-your-own-cloud edition has custom pricing.

3 more Splunk alternatives

Splunk alternatives: questions

What is the best open-source alternative to Splunk?
Elasticsearch is the top-ranked open-source alternative to Splunk on Enlisted: A distributed, RESTful search and analytics engine written in Java, used for full-text search, log analysis and vector search across large datasets. Other strong options are Grafana, Grafana Loki, OpenObserve and Kibana.
Are these Splunk alternatives free?
All 13 are open source, so the code is free to use under its licence, and all of them can be self-hosted on your own server or computer. 6 also offer a paid or managed cloud version if you'd rather not host it yourself.
How is this list of Splunk alternatives ranked?
By a score built from GitHub stars, star growth over the last 30 days and how recently the code changed. 13 of these projects shipped code in the last 30 days. Data is refreshed daily, and nobody can pay to move up.

People also look for alternatives toโ€ฆ

View all