
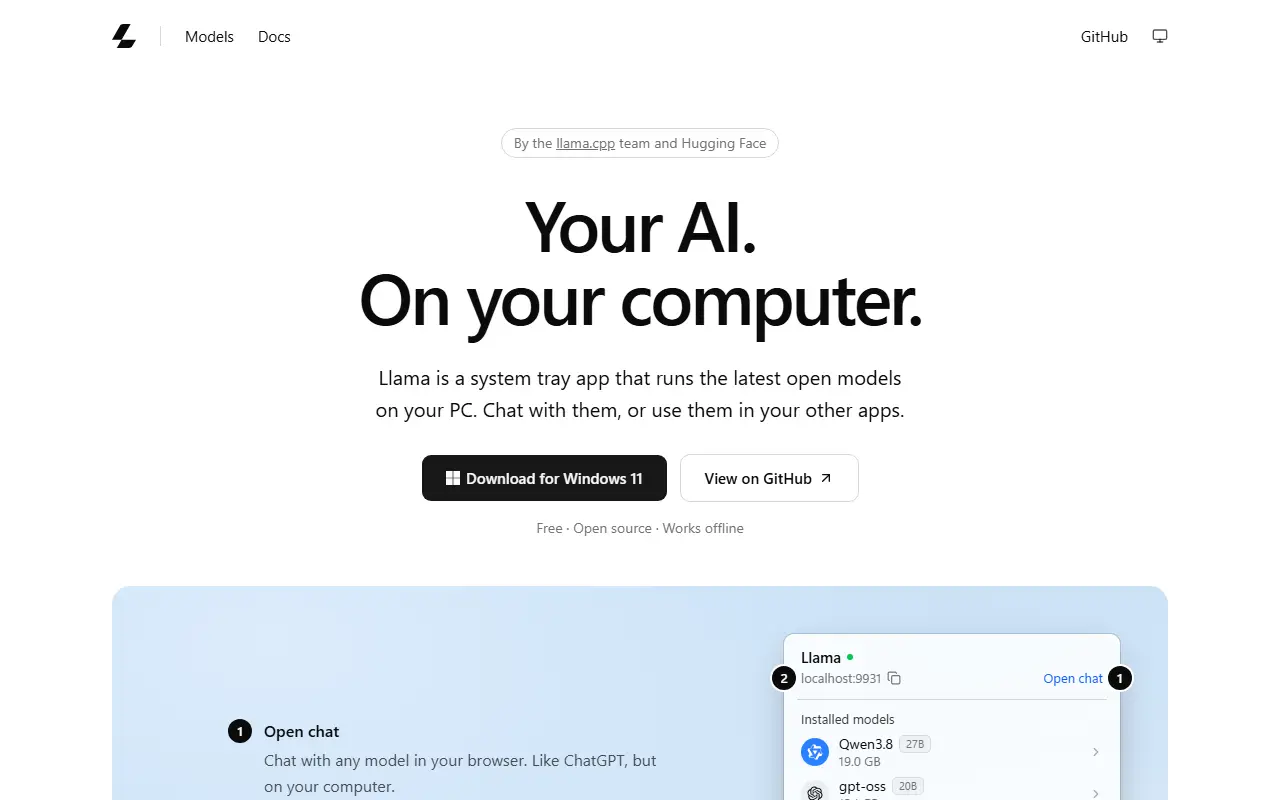
About llama.cpp
llama.cpp is an open-source library and set of tools for running large language model inference, including vision-language models, with minimal setup. The aim is strong performance across many kinds of hardware, whether local or in the cloud. It is a plain C/C++ implementation without external dependencies, built on the ggml library, and is licensed under MIT.
The project optimizes for many platforms: Apple silicon through ARM NEON, Accelerate and Metal, x86 with AVX, AVX2, AVX512 and AMX, and several RISC-V extensions. Quantization from 1.5-bit to 8-bit integers reduces memory use and speeds up inference. GPU backends include CUDA for NVIDIA, HIP for AMD, MUSA, Vulkan and SYCL, and hybrid CPU plus GPU inference lets you partly accelerate models larger than available VRAM.
It provides a command-line interface and llama-server, which offers a REST API and a built-in web UI. You can install it from pre-built binaries, Docker or by building from source. Other local-AI tools such as Ollama build on it, which makes it relevant to developers embedding inference in their own applications and hobbyists running models on modest hardware.
Key features
- Dependency-free C/C++ inference engine
- Quantization from 1.5-bit to 8-bit
- CUDA, HIP, Metal, Vulkan and SYCL backends
- CPU plus GPU hybrid inference
- llama-server with REST API and web UI
- Optimized for Apple silicon and x86
Good fit for
- →Running LLMs on laptops and desktops
- →Embedding inference in C/C++ applications
- →Serving local models over HTTP
- Built with
- C++
- Tags
- llm
- inference
- cpp
- quantization
- local-ai
- ggml
- gpu
- self-hosted
Open-source alternatives to llama.cpp
See all
Ollama
AI Infrastructure
Get up and running with Kimi, GLM, MiniMax, DeepSeek, gpt-oss, Qwen, Gemma and other model
MITvs ChatGPT★ 182k
LocalAI
AI Infrastructure
LocalAI is the open-source AI engine. Run any model - LLMs, vision, voice, image, video -
MITvs ChatGPT★ 49k
vLLM
AI Infrastructure
A high-throughput and memory-efficient inference and serving engine for LLMs
Apache-2.0vs Amazon Bedrock★ 93k
SGLang
AI Infrastructure
SGLang is a high-performance serving framework for large language models and multimodal mo
Apache-2.0vs Amazon Bedrock★ 37k
llamafile
AI Infrastructure
Distribute and run LLMs with a single file.
OSSvs ChatGPT★ 26k
Unsloth
AI Infrastructure
Unsloth is an open-source framework for running and training LLMs.
Apache-2.0vs Together AI★ 77k
SaaS alternatives to llama.cpp
See all
OpenAI API Platform
AI Infrastructure
Developer API and platform for accessing OpenAI models like GPT for text, vision and audio
SaaS
Mistral AI
AI Infrastructure
AI company offering open-weight and commercial language models via API and Le Chat
SaaS
Google AI Studio
AI Infrastructure
Web tool and API for prototyping with Gemini models
SaaS
xAI API
AI Infrastructure
Developer API for accessing Grok models from xAI
SaaS
Cohere
AI Infrastructure
Enterprise AI platform offering language models, embeddings and retrieval for businesses
SaaS
Voyage AI
AI Infrastructure
Embedding and reranking models for search and retrieval-augmented generation
SaaS