7 open-source alternatives ranked by real activity

Open-source Mistral AI alternatives

A curated, ranked list of the 7 best open-source alternatives to Mistral AI.

The best open-source alternative to Mistral AI is Ollama. If that doesn't suit you, other good options are vLLM, llama.cpp, LocalAI and Jan.

Commercial alternatives to Mistral AI include OpenAI API Platform, xAI API, Cohere and Google AI Studio. See all 25.

Mistral AI alternatives are mainly AI infrastructure tools, but some are also AI tools. 6 of them shipped code in the last 30 days, 7 can be self-hosted, and 6 use a permissive licence.

Last updated November 12, 2026 · ranked by GitHub stars, growth and recent commits

Ollama

A tool for downloading and running open large language models locally through a command line and REST API, with Docker support and many integrations.

GitHub stars
187k
Last commit
yesterday
Latest release
v0.40.16
Licence
MIT
Self-hosted
Yes
ollama.comOllama homepage screenshot

Ollama makes it straightforward to run open large language models on your own machine. You install it on macOS, Windows or Linux, or use the official Docker image, then pull a model and chat with it from the command line. It is written in Go and released under the MIT license, and it builds on the llama.cpp project for inference.

Besides the CLI, Ollama provides a REST API for managing and running models, with official Python and JavaScript client libraries. Models can be imported and customized through a Modelfile, and an online library lists what is available. It can be connected to coding agents and assistants such as Claude Code, OpenCode, Codex and OpenClaw, and many community chat interfaces, including Open WebUI and LibreChat, work with it.

Because models run on your own hardware, Ollama can serve as a self-hosted alternative to cloud assistants such as ChatGPT and Perplexity when privacy, offline use or cost control matter. It is aimed at developers and hobbyists experimenting with open models, and at teams that want to wire local models into their own applications.

Key features

  • Run open language models locally from the CLI
  • REST API for managing and running models
  • Official Python and JavaScript libraries
  • Modelfile for customizing and importing models
  • Official Docker image
  • Integrations with coding agents and chat interfaces

Pricing: Running models locally is free, and the Free plan includes starter cloud credits. Pro costs $20, Max $100 and Team $500 per month with included usage credits; Enterprise is custom.

Read more about OllamaWebsiteGitHub#1 Mistral AI alternative

vLLM

A Python library and server for fast, memory-efficient LLM inference and serving, with PagedAttention, continuous batching and broad quantization support.

GitHub stars
97k
Last commit
yesterday
Latest release
v0.33.0rc3
Licence
Apache-2.0
Self-hosted
Yes
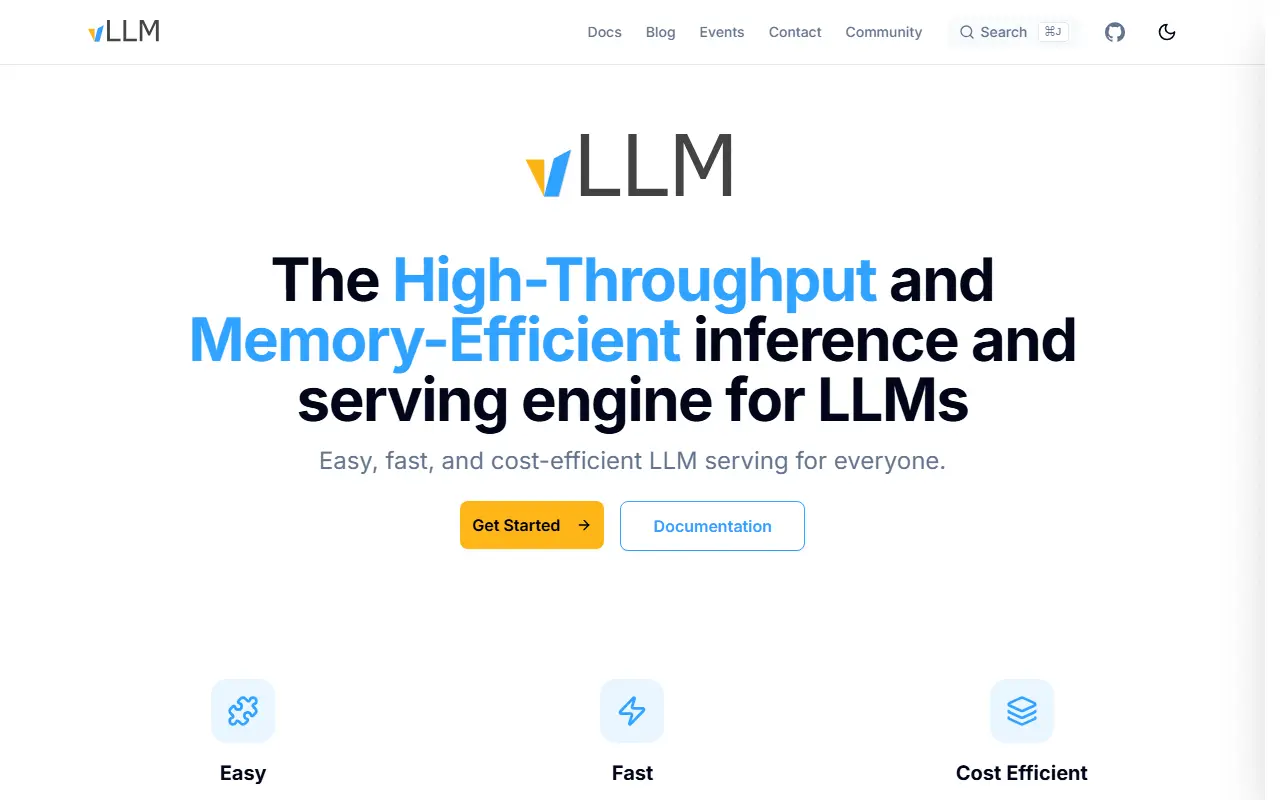
vllm.aivLLM homepage screenshot

vLLM is an open-source library for running and serving large language models efficiently. It originated at UC Berkeley's Sky Computing Lab and is now developed by a large community of contributors from academia and industry. It is written in Python and released under the Apache-2.0 license.

Speed comes from techniques such as PagedAttention for attention key-value memory, batching incoming requests continuously, chunked prefill, prefix caching, CUDA and HIP graphs, and optimized attention and mixture-of-experts kernels. It supports many quantization formats, including FP8, INT8, INT4, GPTQ and AWQ, as well as speculative decoding and disaggregated prefill and decode.

On the usability side, vLLM integrates with Hugging Face models and supports parallel sampling, beam search, streaming outputs, structured outputs and tool calling, plus several parallelism modes (tensor, pipeline, data, expert and context) for distributed inference. It targets NVIDIA, AMD and TPU hardware and suits teams that serve open models in production and need high throughput.

Key features

  • PagedAttention and continuous batching
  • Quantization including FP8, INT8, GPTQ and AWQ
  • Speculative decoding support
  • Tensor, pipeline and expert parallelism
  • OpenAI-compatible API server
  • Hugging Face model integration
  • Streaming and structured outputs

Pricing: Free and open source under the Apache-2.0 license.

Read more about vLLMWebsiteGitHub#2 Mistral AI alternative

llama.cpp

A dependency-free C/C++ engine for running large language models locally on CPUs and GPUs, with quantization, a CLI and an HTTP server.

GitHub stars
134k
Last commit
yesterday
Latest release
v0.9.0
Licence
MIT
Self-hosted
Yes
llama.appllama.cpp homepage screenshot

llama.cpp is an open-source library and set of tools for running large language model inference, including vision-language models, with minimal setup. The aim is strong performance across many kinds of hardware, whether local or in the cloud. It is a plain C/C++ implementation without external dependencies, built on the ggml library, and is licensed under MIT.

The project optimizes for many platforms: Apple silicon through ARM NEON, Accelerate and Metal, x86 with AVX, AVX2, AVX512 and AMX, and several RISC-V extensions. Quantization from 1.5-bit to 8-bit integers reduces memory use and speeds up inference. GPU backends include CUDA for NVIDIA, HIP for AMD, MUSA, Vulkan and SYCL, and hybrid CPU plus GPU inference lets you partly accelerate models larger than available VRAM.

It provides a command-line interface and llama-server, which offers a REST API and a built-in web UI. You can install it from pre-built binaries, Docker or by building from source. Other local-AI tools such as Ollama build on it, which makes it relevant to developers embedding inference in their own applications and hobbyists running models on modest hardware.

Key features

  • Dependency-free C/C++ inference engine
  • Quantization from 1.5-bit to 8-bit
  • CUDA, HIP, Metal, Vulkan and SYCL backends
  • CPU plus GPU hybrid inference
  • llama-server with REST API and web UI
  • Optimized for Apple silicon and x86

Pricing: Free and open source under the MIT license.

LocalAI

An open-source AI engine that runs LLMs, vision, voice, image and video models on your own hardware behind OpenAI-compatible APIs, with no GPU required.

GitHub stars
50k
Last commit
yesterday
Latest release
v4.12.1
Licence
MIT
Self-hosted
Yes
localai.ioLocalAI homepage screenshot

LocalAI is an open-source AI engine for running models of many kinds, including language, vision, voice, image and video models, on your own hardware. A GPU is not required. It is written in Go and released under the MIT license, was started by Ettore Di Giacinto and is looked after by the LocalAI team.

Its design is a small core with separate backends that are pulled on demand, so nothing unused gets installed. Backends wrap engines such as llama.cpp, vLLM, whisper.cpp, stable-diffusion and MLX, and you can write your own in any language against an open interface. It can run on CPU alone, through Vulkan, or on NVIDIA, AMD, Intel and Apple Silicon hardware.

APIs are drop-in compatible with OpenAI, Anthropic and ElevenLabs across every backend. Multi-user features include API key authentication, user quotas and role-based access, and built-in agents support tool use, RAG, MCP and skills. The project stresses that data stays on your infrastructure. It suits developers and teams who want a private, self-hosted replacement for cloud AI APIs.

Key features

  • Runs LLM, vision, voice, image and video models
  • Composable backends pulled on demand
  • OpenAI, Anthropic and ElevenLabs API compatibility
  • Runs on CPU, NVIDIA, AMD, Intel and Apple Silicon
  • API key authentication, quotas and role-based access
  • Built-in agents with tools, RAG and MCP

Pricing: Free and open source under the MIT license.

Read more about LocalAIWebsiteGitHub#4 Mistral AI alternative

Jan

An open-source desktop app that acts as a ChatGPT replacement, running local language models offline or connecting to cloud providers, with an OpenAI-compatible local server.

GitHub stars
46k
Last commit
yesterday
Latest release
v0.8.8
Self-hosted
Yes
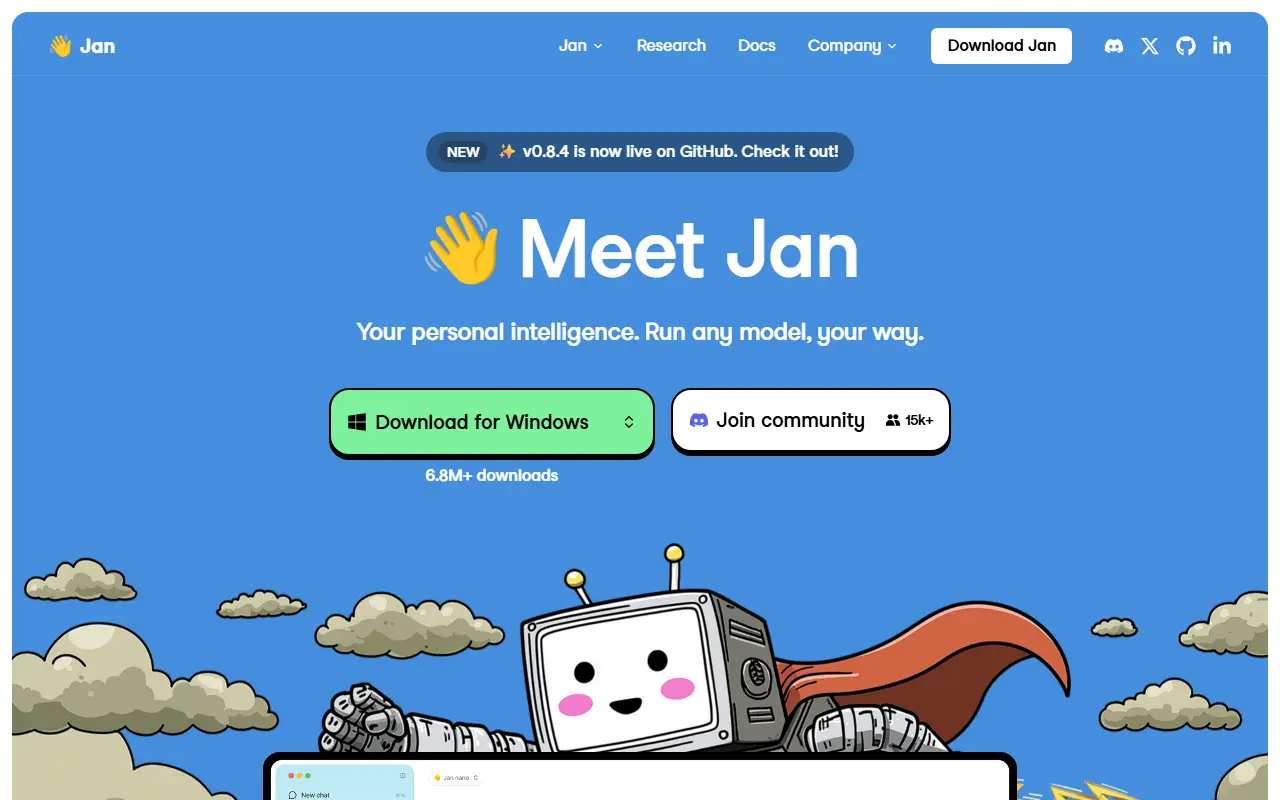
jan.aiJan homepage screenshot

Jan is an open-source desktop application that serves as a ChatGPT alternative you control. It can download and run language models such as Llama, Gemma, Qwen and GPT-oss from Hugging Face entirely on your own computer, so conversations stay private and work without an internet connection.

When you want more capability than local hardware allows, Jan can connect to cloud models from OpenAI, Anthropic, Mistral, Groq, MiniMax and others from the same interface. You can create custom assistants for specific tasks, and Model Context Protocol support adds agentic abilities. A built-in local server on localhost port 1337 exposes an OpenAI-compatible API, so other applications can use your local models as a drop-in backend.

Jan is built with Rust and Tauri and ships installers for Windows, macOS and Linux in deb and AppImage form. Its license is listed as 'Other' on GitHub, so check the repository terms before redistributing it. It is meant for people who want local AI with a polished interface rather than a command line.

Key features

  • Download and run local LLMs from Hugging Face
  • Connect to OpenAI, Anthropic, Mistral and Groq
  • Custom assistants for specific tasks
  • OpenAI-compatible local server
  • Model Context Protocol integration
  • Installers for Windows, macOS and Linux

Pricing: Free and open source; running local models costs nothing beyond your own hardware, and cloud providers bill you separately.

Read more about JanWebsiteGitHub#5 Mistral AI alternative

Hugging Face Chat UI

SvelteKit chat interface for large language models that connects to any OpenAI-compatible API and powers HuggingChat.

GitHub stars
11k
Last commit
yesterday
Latest release
v0.10.0
Licence
Apache-2.0
Self-hosted
Yes
Hosted version
Available
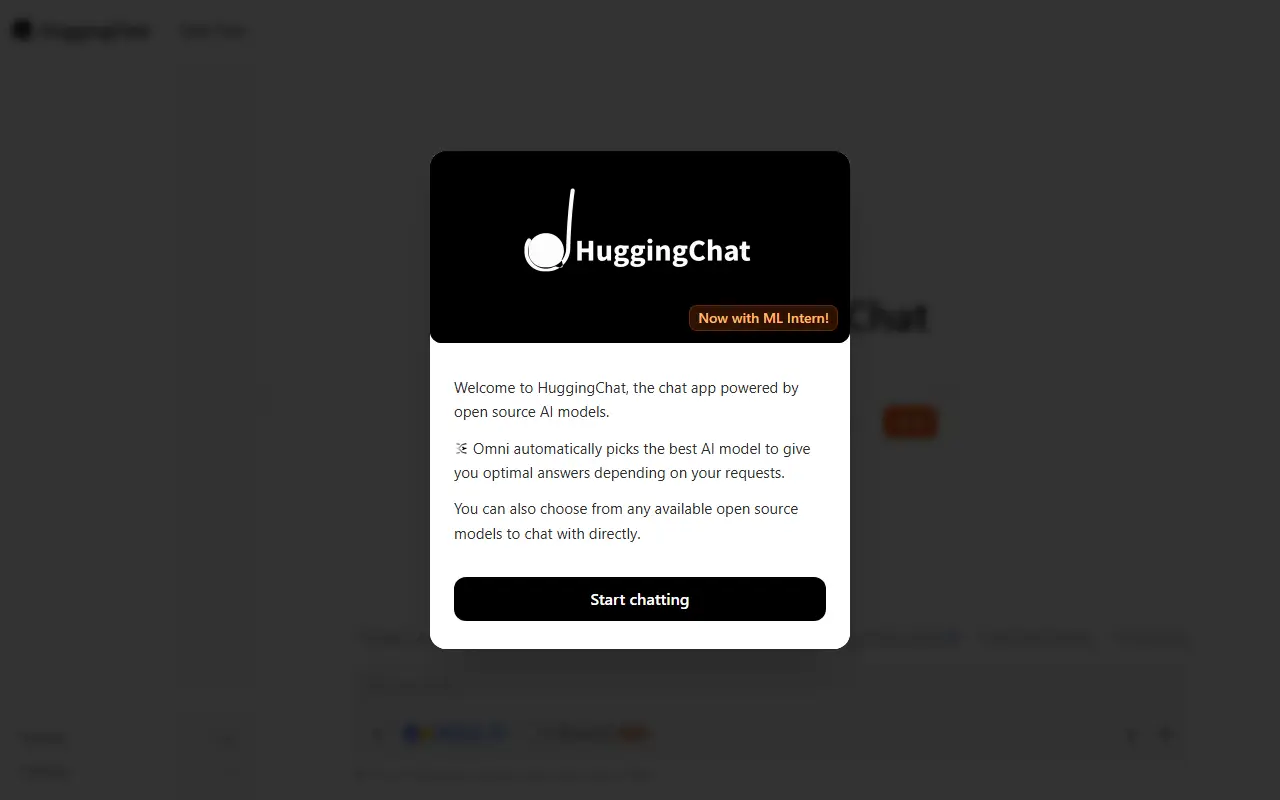
huggingface.coHugging Face Chat UI homepage screenshot

Chat UI is a chat interface for LLMs built as a SvelteKit application. It is the open source codebase behind HuggingChat on Hugging Face and lets you run a similar conversational front end against models you choose, whether hosted or running locally.

The current version speaks only to OpenAI-compatible APIs, configured through a base URL and a models endpoint. The README lists the Hugging Face Inference Providers router, a llama.cpp server, Ollama through its OpenAI-compatible bridge, OpenRouter and Poe as example backends. Older provider-specific integrations were removed from the main branch but remain available on a legacy branch.

Setup involves creating an .env.local file with the endpoint and key, choosing a database option, and launching the app, with an optional Docker image. The project is written in TypeScript with Tailwind CSS and is licensed under Apache-2.0, making it a base for self-hosted assistants.

Key features

  • Chat front end for any OpenAI-compatible API
  • Works with llama.cpp, Ollama and OpenRouter
  • Hugging Face Inference Providers support
  • Configured through a simple .env.local file
  • Optional Docker image
  • SvelteKit and Tailwind CSS codebase

Pricing: Free and open source under the Apache-2.0 license.

GPT4All

Desktop application and libraries for running large language models locally on everyday computers, without API calls or GPUs.

GitHub stars
77k
Last commit
1 yr ago
Latest release
v3.10.0
Licence
MIT

GPT4All runs large language models privately on ordinary desktops and laptops. The README says no API calls or GPUs are required: you download the application and start. Installers are listed for Windows, Windows ARM, macOS and Ubuntu, and a community-maintained Flathub package is also mentioned.

Besides the chat application there are Python bindings, installed with pip, that wrap llama.cpp implementations, and Node.js bindings. The Python example loads a Llama 3 8B Instruct model of about 4.66GB. Listed integrations include Langchain, the Weaviate vector database and OpenLIT monitoring. The repository describes the project as open source and available for commercial use under the MIT licence, and its news items mention DeepSeek R1 distillations and a redesigned chat UI in version 3.0.0.

Key features

  • Runs LLMs locally on desktops and laptops
  • No GPU or API calls needed
  • Python client built on llama.cpp
  • Node.js bindings for the same models
  • Built on llama.cpp work that Nomic contributes to
  • macOS build gives best results on Apple Silicon
Read more about GPT4AllWebsiteGitHub#7 Mistral AI alternative

Commercial Mistral AI alternatives

Hosted, closed-source products that compete with Mistral AI. Showing 12 of 25.

See every Mistral AI alternative on its tool page

Mistral AI alternatives: questions

What is the best open-source alternative to Mistral AI?
Ollama is the top-ranked open-source alternative to Mistral AI on Enlisted: A tool for downloading and running open large language models locally through a command line and REST API, with Docker support and many integrations. Other strong options are vLLM, llama.cpp, LocalAI and Jan.
What are the best commercial alternatives to Mistral AI?
OpenAI API Platform, xAI API, Cohere, Google AI Studio and Groq are among the hosted, closed-source alternatives to Mistral AI listed on Enlisted, which lists 25 in total. Compare their pricing and features on each tool page.
Are these Mistral AI alternatives free?
All 7 are open source, so the code is free to use under its licence, and all of them can be self-hosted on your own server or computer. 1 also offers a paid or managed cloud version if you'd rather not host it yourself.
How is this list of Mistral AI alternatives ranked?
By a score built from GitHub stars, star growth over the last 30 days and how recently the code changed. 6 of these projects shipped code in the last 30 days. Data is refreshed daily, and nobody can pay to move up.

People also look for alternatives to…

View all