7,363 open-source and SaaS tools, with GitHub stats refreshed every day.

6 alternatives ranked by real activity

Open-source OpenAI API Platform alternatives

A curated, ranked list of the 6 best open-source alternatives to OpenAI API Platform.

The best open-source alternative to OpenAI API Platform is Ollama. If that doesn't suit you, other good options are llama.cpp, vLLM, LocalAI and SGLang.

OpenAI API Platform alternatives are mainly AI infrastructure tools. 6 of them shipped code in the last 30 days, 6 can be self-hosted, and 5 use a permissive licence.

Last updated October 3, 2026 · ranked by GitHub stars, growth and recent commits

Ollama

A tool for downloading and running open large language models locally through a command line and REST API, with Docker support and many integrations.

GitHub stars
182k
Last commit
today
Latest release
v0.35.0
Licence
MIT
Self-hosted
Yes
ollama.comOllama homepage screenshot

Ollama makes it straightforward to run open large language models on your own machine. You install it on macOS, Windows or Linux, or use the official Docker image, then pull a model and chat with it from the command line. It is written in Go and released under the MIT license, and it builds on the llama.cpp project for inference.

Besides the CLI, Ollama provides a REST API for managing and running models, with official Python and JavaScript client libraries. Models can be imported and customized through a Modelfile, and an online library lists what is available. It can be connected to coding agents and assistants such as Claude Code, OpenCode, Codex and OpenClaw, and many community chat interfaces, including Open WebUI and LibreChat, work with it.

Because models run on your own hardware, Ollama can serve as a self-hosted alternative to cloud assistants such as ChatGPT and Perplexity when privacy, offline use or cost control matter. It is aimed at developers and hobbyists experimenting with open models, and at teams that want to wire local models into their own applications.

Key features

  • Run open language models locally from the CLI
  • REST API for managing and running models
  • Official Python and JavaScript libraries
  • Modelfile for customizing and importing models
  • Official Docker image
  • Integrations with coding agents and chat interfaces

Pricing: Running models locally is free, and the Free plan includes starter cloud credits. Pro costs $20, Max $100 and Team $500 per month with included usage credits; Enterprise is custom.

Read more about OllamaWebsite GitHub

llama.cpp

A dependency-free C/C++ engine for running large language models locally on CPUs and GPUs, with quantization, a CLI and an HTTP server.

GitHub stars
130k
Last commit
today
Latest release
v0.5.0
Licence
MIT
Self-hosted
Yes
llama.appllama.cpp homepage screenshot

llama.cpp is an open-source library and set of tools for running large language model inference, including vision-language models, with minimal setup. The aim is strong performance across many kinds of hardware, whether local or in the cloud. It is a plain C/C++ implementation without external dependencies, built on the ggml library, and is licensed under MIT.

The project optimizes for many platforms: Apple silicon through ARM NEON, Accelerate and Metal, x86 with AVX, AVX2, AVX512 and AMX, and several RISC-V extensions. Quantization from 1.5-bit to 8-bit integers reduces memory use and speeds up inference. GPU backends include CUDA for NVIDIA, HIP for AMD, MUSA, Vulkan and SYCL, and hybrid CPU plus GPU inference lets you partly accelerate models larger than available VRAM.

It provides a command-line interface and llama-server, which offers a REST API and a built-in web UI. You can install it from pre-built binaries, Docker or by building from source. Other local-AI tools such as Ollama build on it, which makes it relevant to developers embedding inference in their own applications and hobbyists running models on modest hardware.

Key features

  • Dependency-free C/C++ inference engine
  • Quantization from 1.5-bit to 8-bit
  • CUDA, HIP, Metal, Vulkan and SYCL backends
  • CPU plus GPU hybrid inference
  • llama-server with REST API and web UI
  • Optimized for Apple silicon and x86

Pricing: Free and open source under the MIT license.

Read more about llama.cppWebsite GitHub

vLLM

A Python library and server for fast, memory-efficient LLM inference and serving, with PagedAttention, continuous batching and broad quantization support.

GitHub stars
93k
Last commit
today
Latest release
v0.30.0
Licence
Apache-2.0
Self-hosted
Yes
vllm.aivLLM homepage screenshot

vLLM is an open-source library for running and serving large language models efficiently. It originated at UC Berkeley's Sky Computing Lab and is now developed by a large community of contributors from academia and industry. It is written in Python and released under the Apache-2.0 license.

Speed comes from techniques such as PagedAttention for attention key-value memory, batching incoming requests continuously, chunked prefill, prefix caching, CUDA and HIP graphs, and optimized attention and mixture-of-experts kernels. It supports many quantization formats, including FP8, INT8, INT4, GPTQ and AWQ, as well as speculative decoding and disaggregated prefill and decode.

On the usability side, vLLM integrates with Hugging Face models and supports parallel sampling, beam search, streaming outputs, structured outputs and tool calling, plus several parallelism modes (tensor, pipeline, data, expert and context) for distributed inference. It targets NVIDIA, AMD and TPU hardware and suits teams that serve open models in production and need high throughput.

Key features

  • PagedAttention and continuous batching
  • Quantization including FP8, INT8, GPTQ and AWQ
  • Speculative decoding support
  • Tensor, pipeline and expert parallelism
  • OpenAI-compatible API server
  • Hugging Face model integration
  • Streaming and structured outputs

Pricing: Free and open source under the Apache-2.0 license.

Read more about vLLMWebsite GitHub

LocalAI

An open-source AI engine that runs LLMs, vision, voice, image and video models on your own hardware behind OpenAI-compatible APIs, with no GPU required.

GitHub stars
49k
Last commit
today
Latest release
v4.10.0
Licence
MIT
Self-hosted
Yes
localai.ioLocalAI homepage screenshot

LocalAI is an open-source AI engine for running models of many kinds, including language, vision, voice, image and video models, on your own hardware. A GPU is not required. It is written in Go and released under the MIT license, was started by Ettore Di Giacinto and is looked after by the LocalAI team.

Its design is a small core with separate backends that are pulled on demand, so nothing unused gets installed. Backends wrap engines such as llama.cpp, vLLM, whisper.cpp, stable-diffusion and MLX, and you can write your own in any language against an open interface. It can run on CPU alone, through Vulkan, or on NVIDIA, AMD, Intel and Apple Silicon hardware.

APIs are drop-in compatible with OpenAI, Anthropic and ElevenLabs across every backend. Multi-user features include API key authentication, user quotas and role-based access, and built-in agents support tool use, RAG, MCP and skills. The project stresses that data stays on your infrastructure. It suits developers and teams who want a private, self-hosted replacement for cloud AI APIs.

Key features

  • Runs LLM, vision, voice, image and video models
  • Composable backends pulled on demand
  • OpenAI, Anthropic and ElevenLabs API compatibility
  • Runs on CPU, NVIDIA, AMD, Intel and Apple Silicon
  • API key authentication, quotas and role-based access
  • Built-in agents with tools, RAG and MCP

Pricing: Free and open source under the MIT license.

Read more about LocalAIWebsite GitHub

SGLang

SGLang is an open-source framework for serving language, vision-language and diffusion models, built for fast inference at scale.

GitHub stars
37k
Last commit
today
Latest release
v0.5.21
Licence
Apache-2.0
Self-hosted
Yes
sglang.ioSGLang homepage screenshot

SGLang is an inference framework, released as open source, for language models, vision-language models and diffusion models. It is optimized for agentic workloads, reinforcement-learning rollouts and large-scale serving. The project includes SGLang Diffusion, a built-in engine for image and video generation that ships in the same repository and Python package. It is released under the Apache-2.0 license.

Getting started takes either a prebuilt Docker image or a Python install using uv, followed by a launch command for the chosen model. A cookbook helps pick a model and hardware pair and generates a ready-to-run command. Supported hardware spans NVIDIA and AMD GPUs, Google TPUs, Intel GPUs and CPUs, Apple Silicon through Metal and MLX, and Huawei Ascend NPUs, with more integrations in progress. The wider SGLang ecosystem adds educational projects and community events.

Key features

  • Serving for LLMs, vision-language and diffusion models
  • Docker image and uv-based Python install
  • Cookbook with ready-to-run launch commands
  • Runs on NVIDIA, AMD, TPU, Intel and Ascend hardware
  • Built-in image and video generation engine
  • Tuned for agentic and RL rollout workloads

Pricing: Free and open source under the Apache-2.0 license.

Read more about SGLangWebsite GitHub

llamafile

llamafile packages a large language model and its runtime into one executable file that runs locally on most operating systems.

GitHub stars
26k
Last commit
yesterday
Latest release
0.10.6
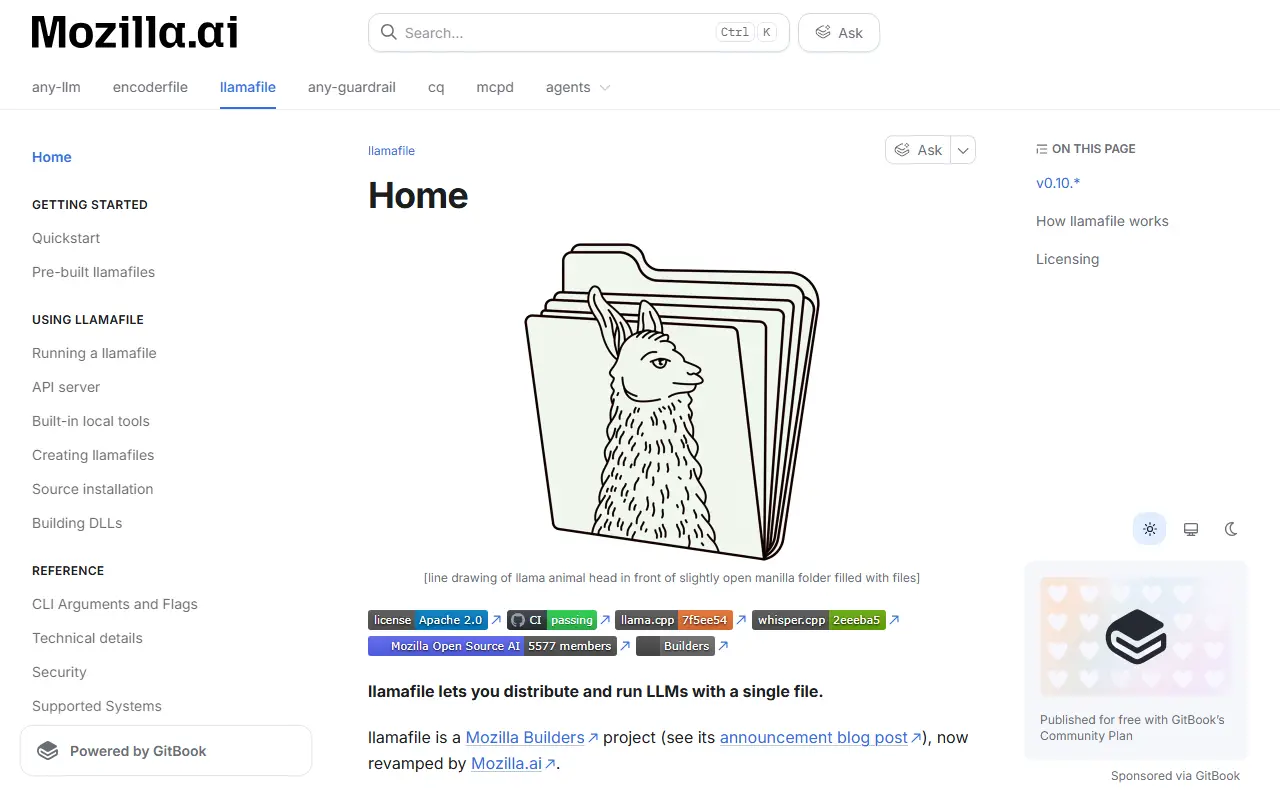
docs.mozilla.aillamafile homepage screenshot

llamafile is a Mozilla Builders project, now revamped by Mozilla.ai, that lets you distribute and run LLMs as one file. It combines llama.cpp with Cosmopolitan Libc into a framework that folds the complexity of running a model into one executable, known as a llamafile, which needs no installation and runs on your machine under most operating systems and CPU architectures. The goal is to make open models more approachable for developers and end users. The repository metadata lists the license as Other.

The project also bundles whisperfile, which applies the same single-file packaging to whisper.cpp for speech-to-text, transcribing and translating audio on the same platforms. Starting with version 0.10.0, llamafile uses a new build system that keeps it aligned with current llama.cpp, adding support for newer models while some earlier features may be missing. Previous versions remain on the releases page, and pre-built llamafiles state which server version they bundle.

Key features

  • Model and runtime in a single executable
  • Runs locally with no installation
  • Built on llama.cpp and Cosmopolitan Libc
  • Works across most OS and CPU architectures
  • whisperfile for speech-to-text and translation
  • Older versions kept on the releases page
Read more about llamafileWebsite GitHub

OpenAI API Platform alternatives: questions

What is the best open-source alternative to OpenAI API Platform?
Ollama is the top-ranked open-source alternative to OpenAI API Platform on Enlisted: A tool for downloading and running open large language models locally through a command line and REST API, with Docker support and many integrations. Other strong options are llama.cpp, vLLM, LocalAI and SGLang.
Are these OpenAI API Platform alternatives free?
All 6 are open source, so the code is free to use under its licence, and all of them can be self-hosted on your own server or computer.
How is this list of OpenAI API Platform alternatives ranked?
By a score built from GitHub stars, star growth over the last 30 days and how recently the code changed. 6 of these projects shipped code in the last 30 days. Data is refreshed daily, and nobody can pay to move up.

People also look for alternatives to…

View all