About Crawlbyte
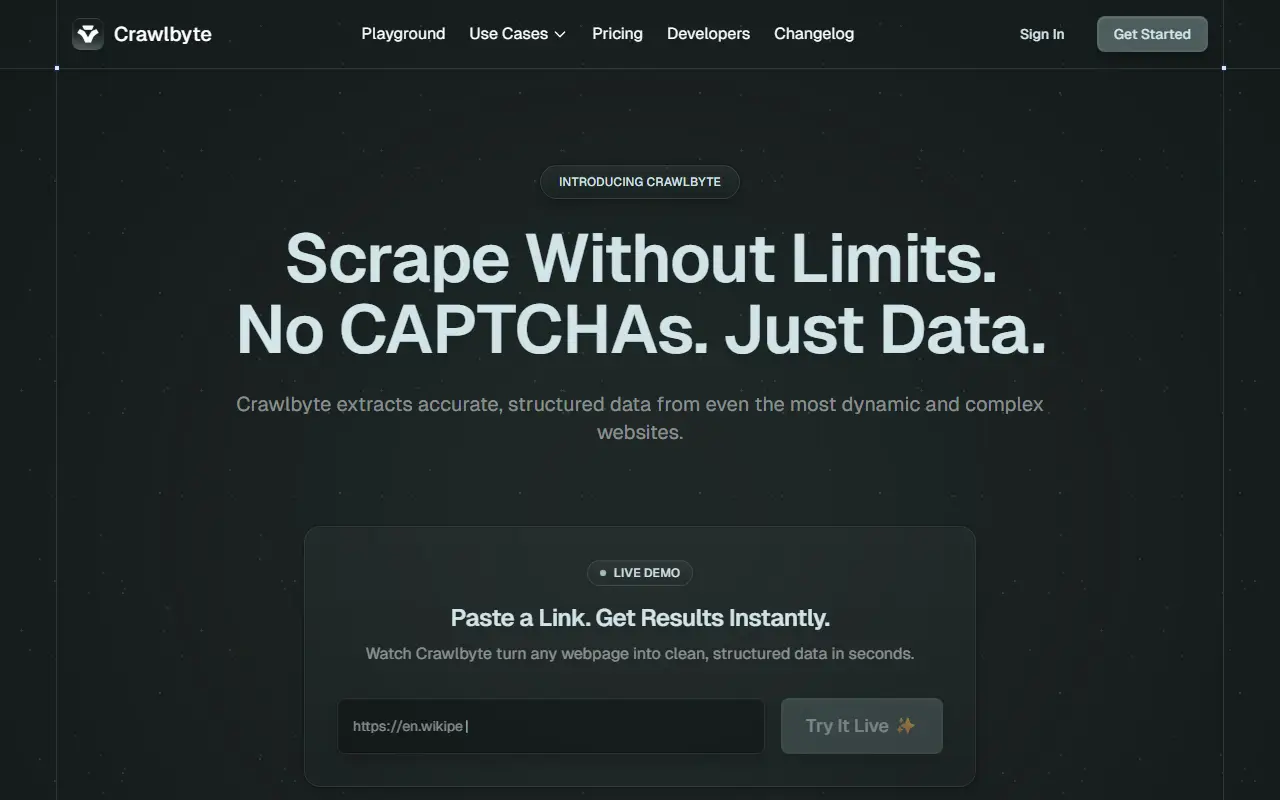
Crawlbyte extracts structured data from public websites, including dynamic and complex pages, for product, data and engineering teams. You paste a link in the live playground to see the result, or call its APIs from your own pipelines, with the service dealing with JavaScript, CAPTCHAs and other blocks only when needed.
The site lists use cases such as e-commerce price and inventory tracking, real estate listings, travel prices, market research, content aggregation, lead enrichment, business data extraction and change monitoring with alerts. It also offers developer documentation and a changelog, and a team can talk to an expert before committing.
Crawlbyte is a hosted commercial service that bills for each successful task, with plans on its pricing page. It is not available as self-hosted software.
Key features
- Structured data from dynamic websites
- Live playground for pasting a link
- APIs for production data pipelines
- Handles CAPTCHAs and blocks when needed
- Change monitoring with alerts
- Billing per successful task
Good fit for
- →Tracking competitor prices and inventory
- →Aggregating property or travel listings
- Tags
- web-scraping
- data-extraction
- api
- crawler
- price-monitoring
- lead-enrichment
- saas
Crawlbyte: questions and answers
- What is Crawlbyte used for?
- Crawlbyte is a web data extraction service that turns public websites into structured data at scale without code, billed per successful task. It is a good fit for tracking competitor prices and inventory, and aggregating property or travel listings.
- How much does Crawlbyte cost?
- Crawlbyte is a paid product with no free plan.
- Is Crawlbyte open source?
- No. Crawlbyte is proprietary (closed-source) software and can't be self-hosted. In the Data Pipelines & ETL category, open-source options include CKAN, Airflow and Apache Spark.
Open-source alternatives to Crawlbyte
See all
CKAN
Data Pipelines & ETL
CKAN is an open-source DMS (data management system) for powering data hubs and data portal
OSS★ 5.1k
Airflow
Data Pipelines & ETL
Apache Airflow - A platform to programmatically author, schedule, and monitor workflows
Apache-2.0vs Astronomer★ 47k
Apache Spark
Data Pipelines & ETL
Apache Spark - A unified analytics engine for large-scale data processing
Apache-2.0vs Databricks★ 44k
Kafka
Data Pipelines & ETL
Apache Kafka - A distributed event streaming platform
Apache-2.0vs Striim★ 34k
Kestra
Data Pipelines & ETL
Event Driven Orchestration & Scheduling Platform for Mission Critical Applications
Apache-2.0vs AWS Step Functions★ 29k
Prefect
Data Pipelines & ETL
Prefect is a workflow orchestration framework for building resilient data pipelines in Pyt
Apache-2.0vs Astronomer★ 24k
SaaS alternatives to Crawlbyte
See all
Apify
Workflow Automation
Cloud platform and marketplace for web scraping and browser automation actors
SaaS
Octoparse
Workflow Automation
Point-and-click web scraping software that extracts data without coding
SaaS
ParseHub
Workflow Automation
Point-and-click web scraper for extracting data from dynamic websites
SaaS
Browse AI
Workflow Automation
No-code web scraper and site monitor trained by recording actions in a browser
SaaS
PhantomBuster
Workflow Automation
Cloud automations for lead generation and data extraction from social platforms
SaaS
Clura
Workflow Automation
No-code tool to extract, enrich and monitor website data and send it to your team's tools
SaaS