#1
A distributed, RESTful search and analytics engine written in Java, used for full-text search, log analysis and vector search across large datasets.
- GitHub stars
- 79k
- Last commit
- today
- Latest release
- v9.5.6
- Self-hosted
- Yes
- Hosted version
- Available
elastic.co
Elasticsearch is a distributed, RESTful search engine written in Java. It stores documents as JSON, indexes them so they can be searched quickly, and exposes everything through an HTTP API, which makes it a common backbone for site search, application search and log analytics. It is built on the Apache Lucene library.
Beyond full-text queries it supports filtering, aggregations for analytics and, in recent versions, vector search for semantic and AI-assisted retrieval. Data is spread across nodes in a cluster using shards and replicas, so capacity and resilience grow by adding machines. It is the core of the Elastic Stack, usually paired with Kibana for exploration and with ingestion tools for logs and metrics.
The repository describes the project as free and open source, while its license metadata is listed as 'Other', so review the current license terms before relying on it commercially. It can be self-managed on your own servers or used as a managed service through Elastic Cloud.
Key features
- Distributed full-text search over JSON documents
- RESTful HTTP API
- Aggregations for analytics
- Vector search for semantic retrieval
- Clustering with shards and replicas

A fast search engine API written in Rust that adds typo-tolerant, filterable and hybrid semantic search to websites and apps, available self-hosted or as a cloud service.
- GitHub stars
- 60k
- Last commit
- yesterday
- Latest release
- v1.56.2
- Self-hosted
- Yes
- Hosted version
- Available
meilisearch.com
Meilisearch is a search engine exposed through an API, written in Rust and designed to be dropped into applications and websites. It aims to give developers a good search experience quickly, with features that work out of the box rather than needing extensive tuning.
Its capabilities include hybrid search that combines semantic and full-text results, search-as-you-type with a target response time under 50 milliseconds, typo tolerance, filtering and faceted search, sorting and geosearch. The topics also describe it as a vector database for AI use cases. The project maintains example applications for movies, ecommerce with facets and filters, conversational home booking, personalization and a multi-tenant CRM, which show how the features fit together.
The license is listed as 'Other', so confirm the terms for your use case. Meilisearch can be run on your own infrastructure, and Meilisearch Cloud offers it as a managed service. It is a common pick for site search, product catalogs and in-app search where a lighter alternative to a large cluster is attractive.
Key features
- Hybrid semantic and full-text search
- Instant search-as-you-type results
- Typo tolerance and fuzzy matching
- Filtering and faceted search
- Sorting and geosearch
- Vector storage for AI search
- REST API with example demo apps
Pricing: Self-hosting is free under the MIT license. Meilisearch Cloud starts at $20 per month with a 14-day free trial, billed by usage or instance resources; Enterprise is quoted on request.
#3
A fast, typo-tolerant, in-memory search engine for site and app search, pitched as an open-source Algolia alternative and an easier-to-run Elasticsearch alternative.
- GitHub stars
- 27k
- Last commit
- 2 days ago
- Latest release
- v30.2
- Licence
- GPL-3.0
- Self-hosted
- Yes
- Hosted version
- Available
typesense.org
Typesense is an open-source search engine for building fast, typo-tolerant search experiences in websites and applications. It is pitched as an open-source substitute for Algolia and Pinecone, and as a simpler option than Elasticsearch. It keeps its index in memory and is written in C++.
The project's feature topics include typo tolerance and fuzzy matching, full-text search, faceting, geosearch, synonyms, merchandising rules and instant search, and it supports semantic and hybrid search. Public demos let you try it on large datasets, such as 32 million songs from MusicBrainz, 28 million books from OpenLibrary, a recipe set, Linux kernel commit messages, an ecommerce store experience, a geosearch listing browser and semantic search over Hacker News comments.
Typesense is licensed under GPL-3.0 and can be run on your own servers, and a managed Typesense Cloud service is also available. Documentation, a roadmap, a Slack community and video introductions are provided. It suits developers who want Algolia-style search with the option to self-host and keep costs predictable.
Key features
- Typo-tolerant, in-memory search
- Faceting, filtering and synonyms
- Geosearch for location-based results
- Semantic and hybrid search
- Merchandising controls for ranking
- Self-hosted or Typesense Cloud

Kibana is the web interface for querying, visualizing and managing data stored in Elasticsearch, used for dashboards, observability and analytics.
- GitHub stars
- 21k
- Last commit
- yesterday
- Latest release
- v9.5.6
- Self-hosted
- Yes
- Hosted version
- Available
elastic.co
Kibana is the user interface that sits on top of Elasticsearch. It lets people query, analyze, visualize and manage the data stored there, turning indexes into charts, metrics views and dashboards. It is part of the Elastic Stack and is commonly used for log analysis, observability and general analytics work.
Teams build visualizations and assemble them into shared dashboards, explore documents with search, and use the interface to manage parts of an Elasticsearch deployment. The project advises running Kibana and Elasticsearch at the same version, with major versions required to match, because mismatches can cause problems and support may ask for an upgrade first.
The code is written in TypeScript. The repository lists its license as 'Other' rather than a standard SPDX identifier, so the license files should be read for the exact terms. Kibana can be downloaded and run on your own infrastructure, and Elastic also offers a hosted version through its Cloud service.
Key features
- Query and explore Elasticsearch data
- Visualizations and metrics charts
- Shared dashboards for monitoring
- Observability views for logs and metrics
- Management tools for Elasticsearch data
- Hosted option through Elastic Cloud

An Apache-licensed, distributed and RESTful search engine and observability suite for searching, analyzing and monitoring large volumes of unstructured data.
- GitHub stars
- 14k
- Last commit
- today
- Latest release
- 3.9.0
- Licence
- Apache-2.0
- Self-hosted
- Yes
- Hosted version
- Available
opensearch.org
OpenSearch is an open-source search and observability suite that makes large amounts of unstructured data searchable and analyzable. It is a distributed engine with a RESTful API, written in Java, and developed in the open by the OpenSearch community under the Apache 2.0 licence.
Teams use it for full-text search, log and event analytics, and monitoring of applications and infrastructure. The project provides downloads, documentation, forums and Slack channels, and it follows a formal release and maintainer process. Because it is distributed, clusters can be scaled across multiple nodes as data volumes grow.
OpenSearch includes certain Apache-licensed code derived from Elasticsearch, as its trademark notice explains. You can run it on your own servers, or use managed services offered by cloud providers. Security issues are reported privately by email rather than through public issues, and the project maintains a code of conduct for contributors.
Key features
- Distributed search with a RESTful API
- Full-text search over unstructured data
- Log and event analytics
- Observability and monitoring use cases
- Scales across nodes in a cluster
- Apache 2.0 licensed Java codebase
Pricing: Free and open source under Apache 2.0; managed hosting is available from cloud providers.
#6
A cloud-native open-source search engine for observability data, built in Rust to index logs and traces on object storage with an Elasticsearch-compatible API.
- GitHub stars
- 12k
- Last commit
- today
- Latest release
- v0.9.3
- Licence
- Apache-2.0
- Self-hosted
- Yes
quickwit.io
Quickwit is an open-source, cloud-native search engine designed for observability, covering log management and distributed tracing, with metrics support listed on the roadmap. It is written in Rust, builds on the Tantivy search library, and is meant to search large volumes of data kept in cheap object storage.
It provides full-text search and aggregation queries, schemaless or strict-schema indexing, and a RESTful API that is compatible with a large subset of the Elasticsearch and OpenSearch APIs, so existing clients can often be reused. It is native to Jaeger and OpenTelemetry, works as a Grafana data source and can ingest from Kafka, Kinesis and Pulsar. Compute and storage are decoupled, with stateless indexers and searchers, and data can sit on Amazon S3, Azure Blob Storage or Google Cloud Storage.
Operational features include multi-tenancy with many indexes, partitioning, retention policies and delete tasks for GDPR use cases, and a Helm chart for Kubernetes. Quickwit is licensed under Apache-2.0 and you run it yourself. It suits teams looking for lower-cost log and trace storage with a familiar search API.
Key features
- Full-text search and aggregation queries
- API compatible with Elasticsearch clients
- Native Jaeger and OpenTelemetry support
- Search directly on cloud object storage
- Decoupled compute and storage
- Ingestion from Kafka, Kinesis and Pulsar
- Retention policies and GDPR delete tasks
- Helm chart for Kubernetes
Pricing: Free and open source under the Apache-2.0 licence.
#7
Open-source database built for search that combines keyword, vector and hybrid retrieval with live indexing and an SQL interface, positioned as an alternative to Elasticsearch.
- GitHub stars
- 12k
- Last commit
- yesterday
- Latest release
- release-29.9.0
- Licence
- GPL-3.0
- Self-hosted
- Yes
manticoresearch.com
Manticore Search is an open-source database built specifically for search. It supports full-text queries, vector retrieval and a hybrid mode that combines the two in a single query, with real-time indexing and an SQL interface. The project is written in C++ and presents itself as an alternative to Elasticsearch.
Queries run on multiple threads and use all available CPU cores to keep response times low. Features listed in the README include full-text search that handles both small and large datasets, hybrid search for better relevance, and auto-embeddings that create vectors from text and can break long documents into chunks. Its topics reference BM25, MySQL protocol compatibility, JSON, stream filtering and a Sphinx heritage.
The project publishes reproducible benchmarks comparing it with other engines, and notes that results depend on the workload. Manticore Search is licensed under GPL-3.0, runs on your own infrastructure and is offered with documentation, courses, a forum and community chat. It suits teams building site search, log search or semantic search who want a lighter-weight engine than a full Elastic stack.
Key features
- Full-text search with BM25 ranking
- Vector and hybrid search in one query
- Auto-embeddings with document chunking
- Real-time indexing of new data
- SQL interface with MySQL protocol
- Multi-threaded query execution
- JSON and HTTP APIs
Pricing: Free and open source under the GPL-3.0 licence.
#8
Vespa is an open-source platform for searching, inferring over and organizing vectors, tensors, text and structured data at serving time and at any scale.
- GitHub stars
- 7.2k
- Last commit
- today
- Latest release
- v8.781.11
- Licence
- Apache-2.0
- Self-hosted
- Yes
- Hosted version
- Available
Vespa is a platform that searches, makes inferences in and organizes vectors, tensors, text and structured data, at serving time and at any scale. The GitHub repository holds all the code needed to build and run Vespa, licensed under Apache 2.0. Its topics include search engine, vector database and RAG, and the main language is Java.
The README frames the problem as use cases such as search, recommendation and personalization that must select a subset of a large corpus, evaluate machine-learned models over it, then organize, aggregate and return the results, typically in under 100 milliseconds while the data keeps changing. Vespa does these operations with high availability and performance, including across multiple nodes in parallel.
Applications can be deployed to the Vespa cloud service or on your own instance. The getting-started application is described as fully functional and production-ready, with more nodes advised for redundancy. Java components can be added to an application. A new release is built from the master branch every morning CET, Monday through Thursday, and the README says it serves hundreds of thousands of queries per second on several large internet services.
Key features
- Search and inference over vectors, tensors, text and structured data
- Evaluates machine-learned models over selected data
- High availability and distribution over multiple nodes
- Deploy to a cloud service or run your own instance
- Custom Java components in an application
- Frequent releases from the master branch
Pricing: A free trial for running applications in the cloud is offered; no paid prices are listed.
#9
Sphinx is a documentation generator that supports reStructuredText and MyST Markdown, with features like cross-referencing, multiple output formats, themes, extensions, and internationalization.
- GitHub stars
- 8.1k
- Last commit
- 4 days ago
- Latest release
- v9.2.0
sphinx-doc.org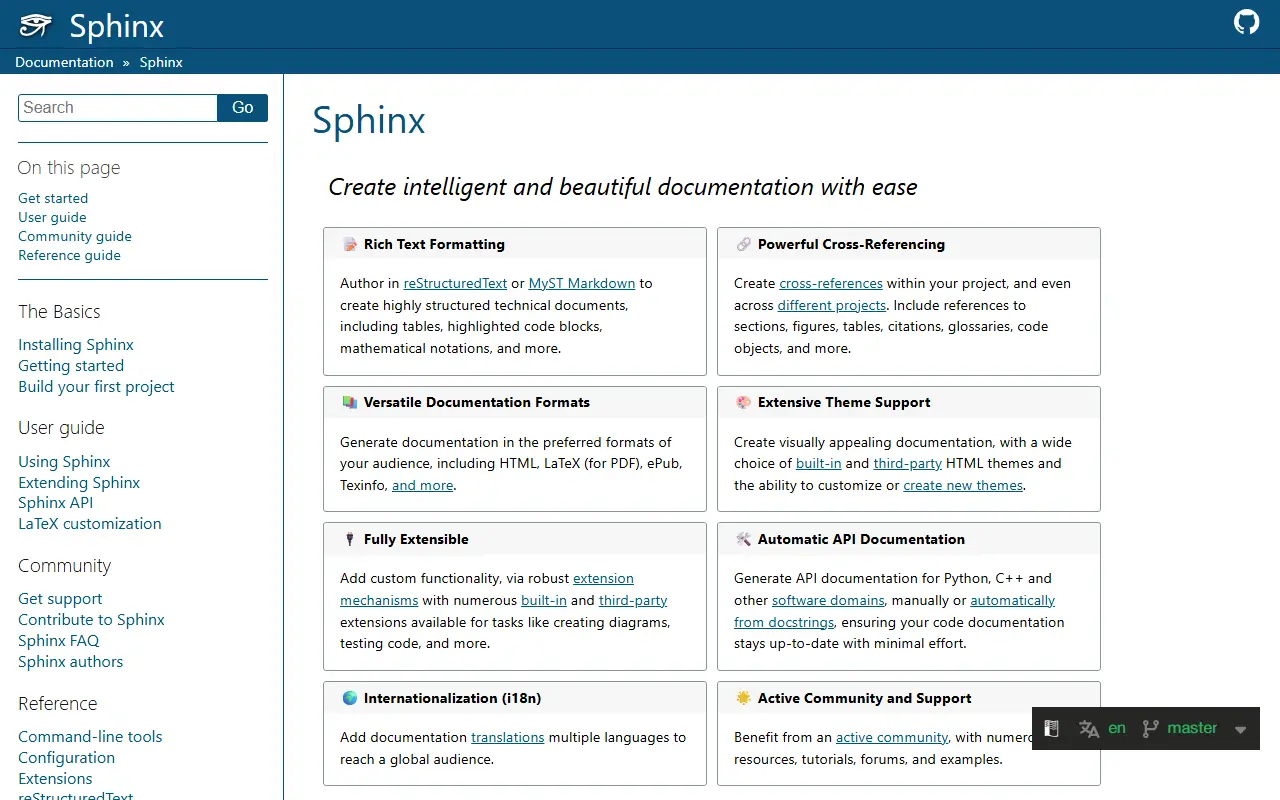
Sphinx is a documentation generator that allows authors to write in reStructuredText or MyST Markdown to create structured technical documents. It supports tables, highlighted code blocks, mathematical notations, and cross-references within and across projects.
The tool can generate documentation in formats such as HTML, LaTeX (for PDF), ePub, and Texinfo. It offers built-in and third-party HTML themes, extension mechanisms for custom functionality, and automatic API documentation for Python, C++, and other software domains.
Key features
- Rich text formatting with reStructuredText or MyST Markdown
- Cross-referencing within and across projects
- Multiple output formats: HTML, LaTeX, ePub, Texinfo
- Extensive theme support with built-in and third-party themes
- Extensible via built-in and third-party extensions
- Automatic API documentation for Python, C++, and other domains

Graylog is a free, open log management platform written in Java that collects, searches and analyzes logs, with a focus on security use cases.
- GitHub stars
- 8.2k
- Last commit
- yesterday
- Self-hosted
- Yes
graylog.org
Graylog is a log management server written in Java and described by its maintainers as free and open. It centralizes log data from many systems so teams can search, view and analyze events in one place instead of connecting to each machine individually.
The repository topics point to support for common log formats and transports, including GELF and syslog, along with Kafka and AMQP inputs. Topics also place the project in log analysis, log collection, secure logging and SIEM territory, which reflects its use for monitoring and security work. Specific features were not available when this entry was written, because the vendor website could not be read.
Key features
- Centralized log collection and search
- GELF and syslog input formats
- Kafka and AMQP integration
- Log analysis and viewing
- Security-oriented logging
2 more Amazon OpenSearch Service alternatives
Commercial Amazon OpenSearch Service alternatives
Hosted, closed-source products that compete with Amazon OpenSearch Service. Showing 12 of 15.
- View tool
Azure managed search with full-text, vector and hybrid retrieval
SaaS
- View tool
AWS enterprise search service that answers questions over indexed company documents
SaaS
- View tool
Algolia is a hosted search and discovery API that lets developers add fast, typo-tolerant search to websites and apps.
SaaS
- View tool
Elastic builds Elasticsearch, a distributed search and analytics engine used for application search, logs, vector search and security analytics.
SaaS
- View tool
Splunk Observability Cloud
Monitoring & Observability
Observability suite from Splunk covering infrastructure, APM and real user monitoring
SaaS
- View tool
Logz.io
Monitoring & Observability
Managed observability stack for logs, metrics and traces built on open tooling
SaaS
- View tool
Multi-model database and data hub platform for integrating and searching enterprise data
SaaS
- View tool
Managed vector database for semantic search and retrieval apps
SaaS
- View tool

Sumo Logic
Monitoring & Observability
Cloud log analytics and security monitoring platform
SaaS
- View tool
Humio
Monitoring & Observability
Log management and analytics platform for security and reliability issues
SaaS
- View tool
Managed service for running Postgres, MySQL, Kafka and other data systems in the cloud
SaaS
- View tool

Bonsai
Finance & Accounting
Contracts, invoicing and time tracking for freelancers
SaaS
See every Amazon OpenSearch Service alternative on its tool page
Amazon OpenSearch Service alternatives: questions
- What is the best open-source alternative to Amazon OpenSearch Service?
- Elasticsearch is the top-ranked open-source alternative to Amazon OpenSearch Service on Enlisted: A distributed, RESTful search and analytics engine written in Java, used for full-text search, log analysis and vector search across large datasets. Other strong options are Meilisearch, Typesense, Kibana and OpenSearch.
- What are the best commercial alternatives to Amazon OpenSearch Service?
- Azure AI Search, Amazon Kendra, Algolia, Elastic and Splunk Observability Cloud are among the hosted, closed-source alternatives to Amazon OpenSearch Service listed on Enlisted, which lists 15 in total. Compare their pricing and features on each tool page.
- Are these Amazon OpenSearch Service alternatives free?
- All 12 are open source, so the code is free to use under its licence, and all of them can be self-hosted on your own server or computer. 6 also offer a paid or managed cloud version if you'd rather not host it yourself.
- How is this list of Amazon OpenSearch Service alternatives ranked?
- By a score built from GitHub stars, star growth over the last 30 days and how recently the code changed. 11 of these projects shipped code in the last 30 days. Data is refreshed daily, and nobody can pay to move up.
 TrackMedia
 TrackRev