7,363 open-source and SaaS tools, with GitHub stats refreshed every day.

16 alternatives ranked by real activity

Open-source Algolia alternatives

A curated, ranked list of the 16 best open-source alternatives to Algolia.

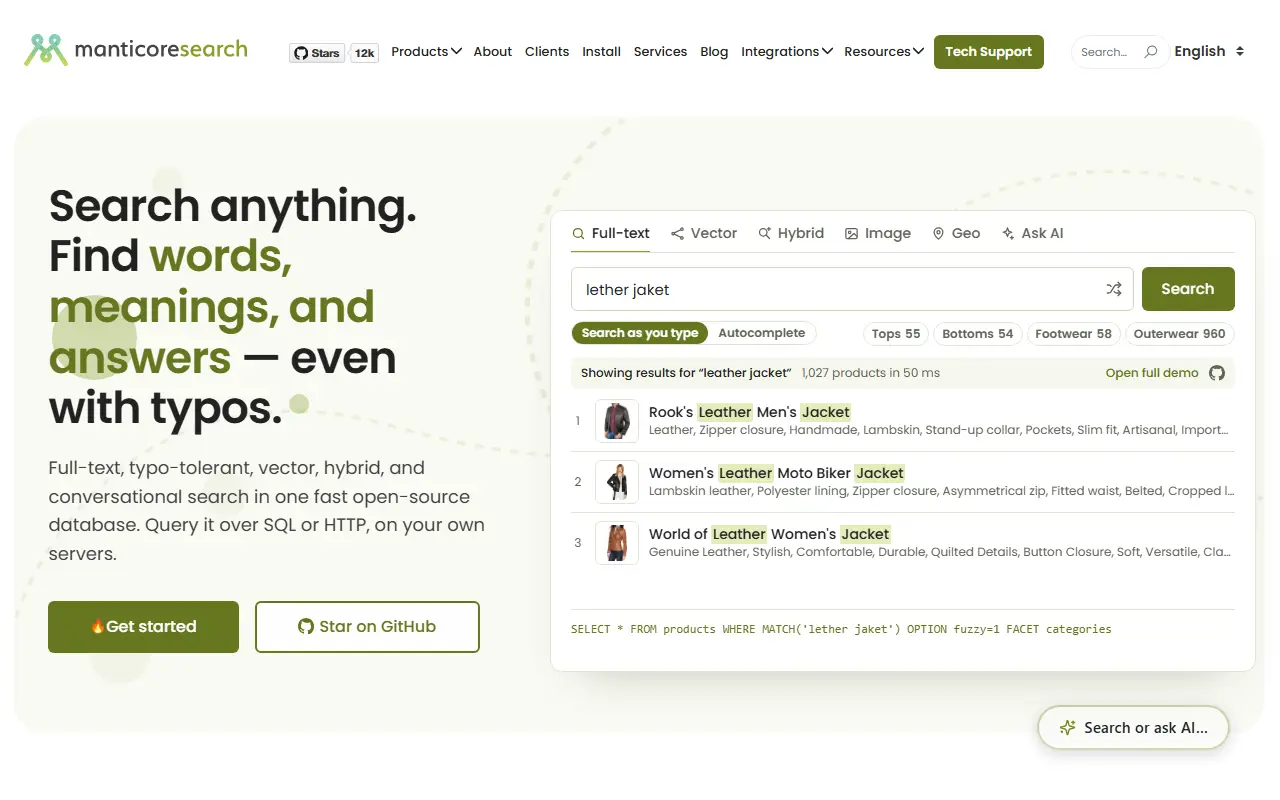
The best open-source alternative to Algolia is Elasticsearch. If that doesn't suit you, other good options are Meilisearch, Typesense, Manticore Search and Orama.

Algolia alternatives are mainly search tools. 11 of them shipped code in the last 30 days, 16 can be self-hosted, and 9 use a permissive licence.

Last updated October 2, 2026 · ranked by GitHub stars, growth and recent commits

Elasticsearch

A distributed, RESTful search and analytics engine written in Java, used for full-text search, log analysis and vector search across large datasets.

GitHub stars
78k
Last commit
today
Latest release
v9.5.4
Self-hosted
Yes
Hosted version
Available

Elasticsearch is a distributed, RESTful search engine written in Java. It stores documents as JSON, indexes them so they can be searched quickly, and exposes everything through an HTTP API, which makes it a common backbone for site search, application search and log analytics. It is built on the Apache Lucene library.

Beyond full-text queries it supports filtering, aggregations for analytics and, in recent versions, vector search for semantic and AI-assisted retrieval. Data is spread across nodes in a cluster using shards and replicas, so capacity and resilience grow by adding machines. It is the core of the Elastic Stack, usually paired with Kibana for exploration and with ingestion tools for logs and metrics.

The repository describes the project as free and open source, while its license metadata is listed as 'Other', so review the current license terms before relying on it commercially. It can be self-managed on your own servers or used as a managed service through Elastic Cloud.

Key features

  • Distributed full-text search over JSON documents
  • RESTful HTTP API
  • Aggregations for analytics
  • Vector search for semantic retrieval
  • Clustering with shards and replicas
Meilisearch

A fast search engine API written in Rust that adds typo-tolerant, filterable and hybrid semantic search to websites and apps, available self-hosted or as a cloud service.

GitHub stars
59k
Last commit
yesterday
Latest release
v1.54.3
Self-hosted
Yes
Hosted version
Available
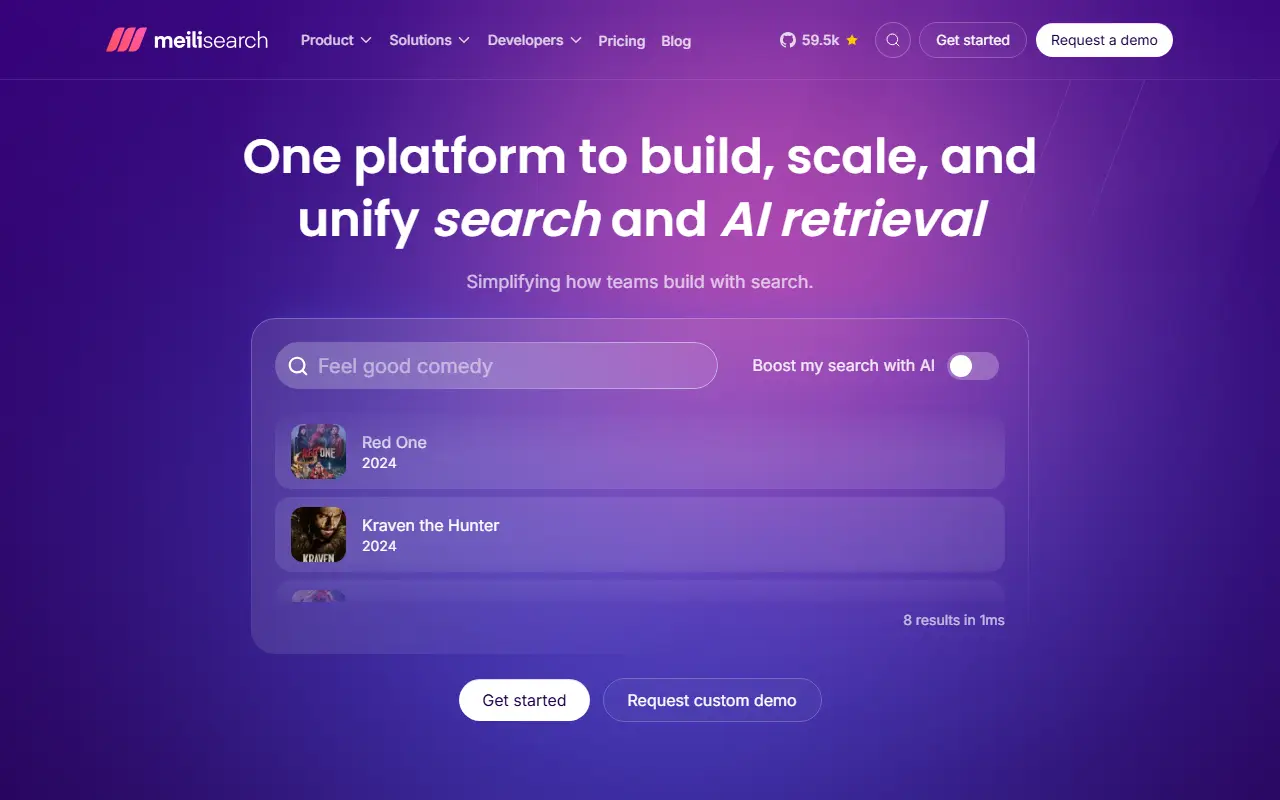
meilisearch.comMeilisearch homepage screenshot

Meilisearch is a search engine exposed through an API, written in Rust and designed to be dropped into applications and websites. It aims to give developers a good search experience quickly, with features that work out of the box rather than needing extensive tuning.

Its capabilities include hybrid search that combines semantic and full-text results, search-as-you-type with a target response time under 50 milliseconds, typo tolerance, filtering and faceted search, sorting and geosearch. The topics also describe it as a vector database for AI use cases. The project maintains example applications for movies, ecommerce with facets and filters, conversational home booking, personalization and a multi-tenant CRM, which show how the features fit together.

The license is listed as 'Other', so confirm the terms for your use case. Meilisearch can be run on your own infrastructure, and Meilisearch Cloud offers it as a managed service. It is a common pick for site search, product catalogs and in-app search where a lighter alternative to a large cluster is attractive.

Key features

  • Hybrid semantic and full-text search
  • Instant search-as-you-type results
  • Typo tolerance and fuzzy matching
  • Filtering and faceted search
  • Sorting and geosearch
  • Vector storage for AI search
  • REST API with example demo apps

Pricing: Self-hosting is free under the MIT license. Meilisearch Cloud starts at $20 per month with a 14-day free trial, billed by usage or instance resources; Enterprise is quoted on request.

Typesense

A fast, typo-tolerant, in-memory search engine for site and app search, pitched as an open-source Algolia alternative and an easier-to-run Elasticsearch alternative.

GitHub stars
27k
Last commit
yesterday
Latest release
v30.2
Licence
GPL-3.0
Self-hosted
Yes
Hosted version
Available
typesense.orgTypesense homepage screenshot

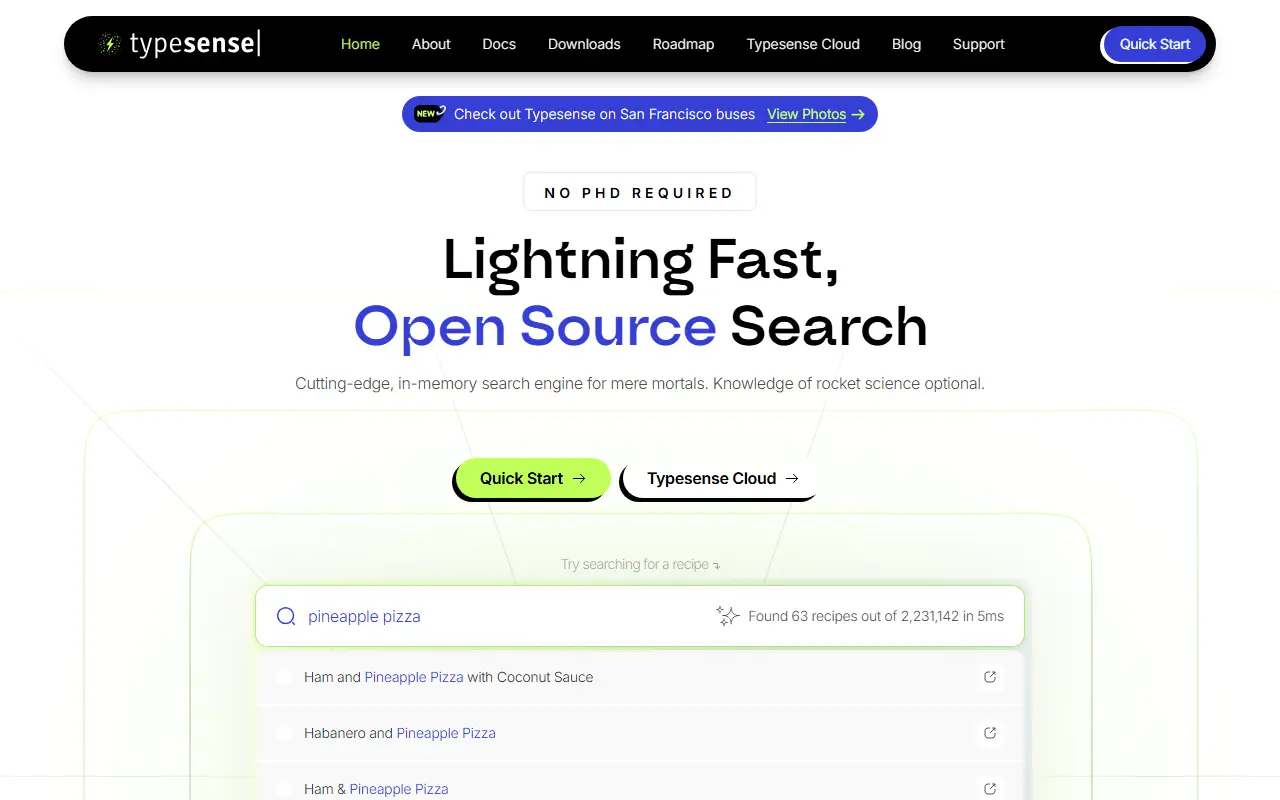
Typesense is an open-source search engine for building fast, typo-tolerant search experiences in websites and applications. It is pitched as an open-source substitute for Algolia and Pinecone, and as a simpler option than Elasticsearch. It keeps its index in memory and is written in C++.

The project's feature topics include typo tolerance and fuzzy matching, full-text search, faceting, geosearch, synonyms, merchandising rules and instant search, and it supports semantic and hybrid search. Public demos let you try it on large datasets, such as 32 million songs from MusicBrainz, 28 million books from OpenLibrary, a recipe set, Linux kernel commit messages, an ecommerce store experience, a geosearch listing browser and semantic search over Hacker News comments.

Typesense is licensed under GPL-3.0 and can be run on your own servers, and a managed Typesense Cloud service is also available. Documentation, a roadmap, a Slack community and video introductions are provided. It suits developers who want Algolia-style search with the option to self-host and keep costs predictable.

Key features

  • Typo-tolerant, in-memory search
  • Faceting, filtering and synonyms
  • Geosearch for location-based results
  • Semantic and hybrid search
  • Merchandising controls for ranking
  • Self-hosted or Typesense Cloud

Orama

A search engine and retrieval pipeline in TypeScript that runs in the browser, on a server or at the edge, supporting full-text, vector and hybrid search.

GitHub stars
11k
Last commit
4 days ago
Latest release
v3.1.18
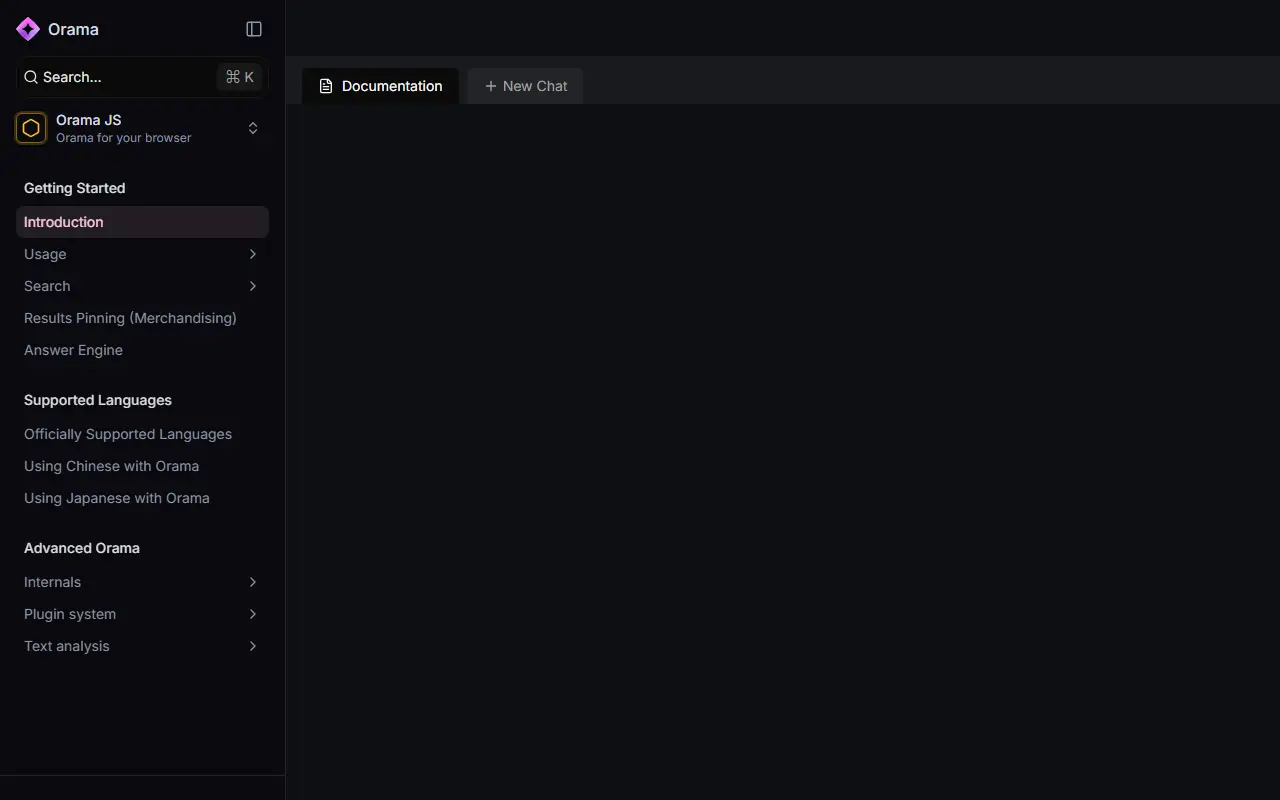
docs.orama.comOrama homepage screenshot

Orama is a search engine written in TypeScript that can be embedded wherever JavaScript runs, including browsers, servers and edge networks. Beyond keyword search it also supports vector search and a hybrid mode, and it aims to serve as the retrieval part of RAG pipelines.

Highlighted features include full-text search alongside semantic vector lookup, a hybrid mode, GenAI chat sessions, search filters, geosearch, pinning rules for merchandising, facets, field boosting, typo tolerance, exact match, BM25 ranking, stemming and tokenization in 30 languages, and a plugin system. A schema defines the indexed fields, and ten data types are supported, including strings, numbers, booleans, enums, geopoints and arrays of these.

Orama installs with npm, yarn, pnpm or bun, can be imported straight into a browser module and works with Deno. The repository lists the licence as Other, and the project offers documentation and a Slack channel. It suits developers adding fast on-site search or AI retrieval to apps without running a separate search server.

Key features

  • Full-text, vector and hybrid search
  • Typo tolerance and BM25 ranking
  • Facets, filters and geosearch
  • Stemming in 30 languages
  • GenAI chat sessions
  • Extensible through a plugin system
  • Runs in browser, server or edge

Vespa

An open-source platform for search, recommendation and personalization that serves vectors, tensors, text and structured data with machine-learned ranking at any scale.

GitHub stars
7.1k
Last commit
today
Latest release
v8.753.16
Licence
Apache-2.0
Self-hosted
Yes
Hosted version
Available

Vespa is a platform for applications that must pick a subset of data from a large, changing corpus, evaluate machine-learned models over it, organize and aggregate the results and return them quickly. Typical examples are search, recommendation and personalization, and the platform adds vector search and retrieval-augmented generation as well, as shown in its topics.

Doing this over large data sets distributed across many nodes and evaluated in parallel is hard, and Vespa handles it with high availability and performance. It handles searching, running inference over and organizing vectors, tensors, text and structured data while serving. According to the README, Vespa has been developed over many years and runs behind several large internet services.

The repository contains all the code needed to build and run Vespa yourself under the Apache 2.0 licence, and new releases are made from the master branch on weekday mornings. You can deploy applications to the Vespa Cloud service, which offers a free trial, or run your own instance following the getting started guide. It is written in Java and C++ and suits teams building large-scale search and recommendation systems.

Key features

  • Search over text, vectors and tensors
  • Machine-learned model inference at serving time
  • Structured data filtering and aggregation
  • Distributed, highly available serving
  • Real-time updates while serving queries
  • Cloud service with a free trial

Pricing: Free and open source under Apache 2.0; Vespa Cloud is a managed service with a free trial.

RediSearch

RediSearch is the Redis query engine for indexing and searching Redis data, with full-text, vector and geospatial search plus aggregations.

GitHub stars
6.2k
Last commit
yesterday
Latest release
v2.10.31
Self-hosted
Yes
Hosted version
Available
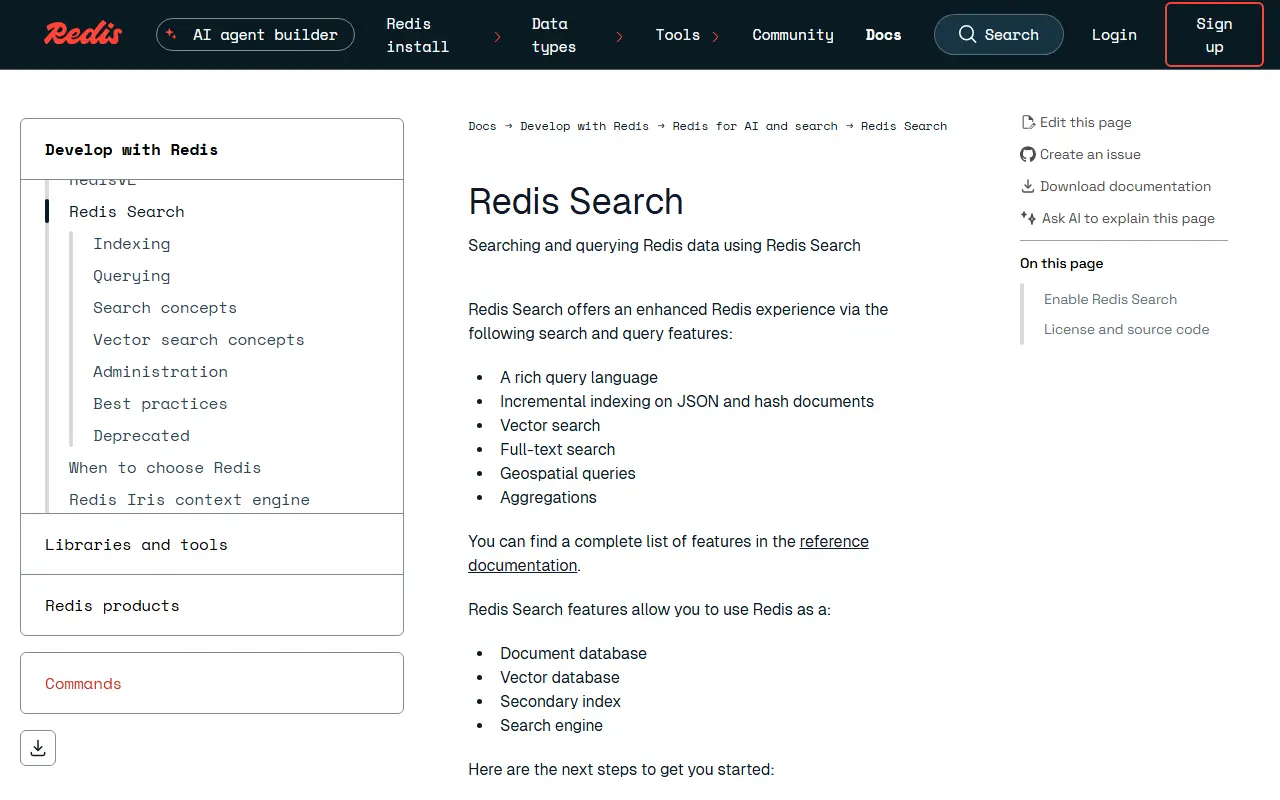
redis.ioRediSearch homepage screenshot

RediSearch is a query and indexing engine for Redis. It lets you declare indexes over data stored in Redis and then query that data with a dedicated query language, adding secondary indexes, full-text search, vector similarity lookups, geospatial queries and aggregations to the key-value store.

It uses compressed inverted indexes to keep indexing fast and memory use low, and its search features include exact-phrase matching and fuzzy search. It began as a Redis module, and the repository lists Rust as its main language. Starting with Redis 8, the Redis Query Engine is built into Redis itself, so standalone releases of the module are no longer published and you do not install it separately. The README also notes that 32-bit systems are not supported.

The code is published under terms that GitHub lists as 'Other', so review the license before commercial use. RediSearch is used by running it inside your own Redis servers, or through the managed Redis cloud service the vendor offers. It suits teams that already rely on Redis and want search or vector lookups without adding another datastore.

Key features

  • Secondary indexing over Redis data
  • Full-text search with fuzzy matching
  • Vector similarity search
  • Geospatial queries on indexed data
  • Aggregations over indexed data
  • Compressed inverted indexes with low memory footprint

Marqo

Marqo is an AI-native ecommerce search and discovery platform, with an open-source multi-modal search engine repository maintained alongside it.

GitHub stars
5k
Last commit
1 mo ago
Latest release
2.26.0
Licence
Apache-2.0
Self-hosted
Yes
Hosted version
Available
marqo.aiMarqo homepage screenshot

Marqo builds AI-native search and product discovery for online brands in categories such as fashion, beauty, electronics and home goods. Using semantic search and personalization, it learns from browsing clicks, orders and other events to infer what shoppers want and return relevant search results and recommendations.

The vendor says its platform helps commerce teams improve search relevance, raise conversion and order value, and reduce manual merchandising through automated ranking and optimization. The repository also hosts the open-source search engine project, with topics covering multi-modal search and machine learning. A notice at the top of the README clarifies the status of the open-source project relative to the commercial platform, so read it before adopting the code.

The code is written in Python under the Apache-2.0 license. You can run the open-source engine yourself, or buy the managed ecommerce platform from the vendor. It suits online retailers and developers evaluating vector search for product catalogs.

Key features

  • Semantic product search
  • Personalized search results and recommendations
  • Clickstream and purchase data learning
  • Automated ranking and merchandising
  • Multi-modal search support
  • Open-source engine in Python

tinysearch

Tiny full-text search engine for static websites, written in Rust and compiled to WebAssembly so search runs entirely in the visitor's browser.

GitHub stars
3k
Last commit
18 days ago
Latest release
v0.11.1
Licence
Apache-2.0
endler.devtinysearch homepage screenshot

Tinysearch is a lightweight, fast full-text search engine designed for static websites. It is written in Rust and compiled to WebAssembly, so the search index and query logic run in the browser with no search server. It can be used with static site generators such as Jekyll, Hugo, Zola, Cobalt, or Pelican, and it is released under the Apache-2.0 license.

It is a Rust and WebAssembly port of an approach to full-text search that uses Bloom filters, and the project presents it as a lighter alternative to lunr.js and elasticlunr, which load a lot of JavaScript for small sites. The README gives an example of the author's own site: an index of 73 posts produces a WASM payload of 179 kB, or 83 kB gzipped.

By default it stores a sorted vocabulary with exact posting lists that map each word to the pages that contain it. It suits bloggers and documentation maintainers who want instant client-side search on a statically hosted site without adding a backend service or sending queries to a third party.

Key features

  • Full-text search that runs in the browser
  • Rust core compiled to WebAssembly
  • Works with Jekyll, Hugo, Zola, Cobalt, and Pelican
  • Small index and payload size
  • No backend or search server required

Pricing: Free and open source under the Apache-2.0 license.

SeekStorm

Rust search engine offering vector and lexical search as an in-process library or a multi-tenancy server, with REST clients in several languages.

GitHub stars
1.9k
Last commit
20 days ago
Latest release
v3.3.13
Licence
Apache-2.0
Self-hosted
Yes
seekstorm.comSeekStorm homepage screenshot

SeekStorm is a native vector and lexical search engine written in Rust, available as an in-process library and as a multi-tenancy search server. Development started in 2015, it has been in production since 2020, it was ported to Rust in 2023, and it was open sourced in 2024. It is a work in progress and is released under the Apache-2.0 license.

Search capabilities include full-text BM25 search, vector and hybrid search, faceting, geosearch, and real-time indexing, according to its topics. There are REST clients for Rust, Python, TypeScript, C#, and Java, and an instant search adapter that redirects an existing Algolia InstantSearch.js frontend to a SeekStorm backend without rewriting the UI, plus a widget library for building a fresh interface.

SeekStorm suits developers who need embedded search inside an application, or a self-hosted search server for multiple tenants, as an alternative to hosted services like Algolia or heavier engines.

Key features

  • In-process search library and multi-tenancy server
  • Lexical BM25 and vector search
  • Hybrid search with faceting and geosearch
  • REST clients for Rust, Python, TypeScript, C#, and Java
  • Adapter for Algolia InstantSearch.js frontends
  • Real-time indexing

Pricing: Self-hosting the open-source engine is free. SeekStorm Cloud is usage-based with a $20 monthly commitment and a spending cap you can set; Enterprise is custom.

6 more Algolia alternatives

Algolia alternatives: questions

What is the best open-source alternative to Algolia?
Elasticsearch is the top-ranked open-source alternative to Algolia on Enlisted: A distributed, RESTful search and analytics engine written in Java, used for full-text search, log analysis and vector search across large datasets. Other strong options are Meilisearch, Typesense, Manticore Search and Orama.
Are these Algolia alternatives free?
All 16 are open source, so the code is free to use under its licence, and all of them can be self-hosted on your own server or computer. 7 also offer a paid or managed cloud version if you'd rather not host it yourself.
How is this list of Algolia alternatives ranked?
By a score built from GitHub stars, star growth over the last 30 days and how recently the code changed. 11 of these projects shipped code in the last 30 days. Data is refreshed daily, and nobody can pay to move up.

People also look for alternatives to…

View all