About Nvidia
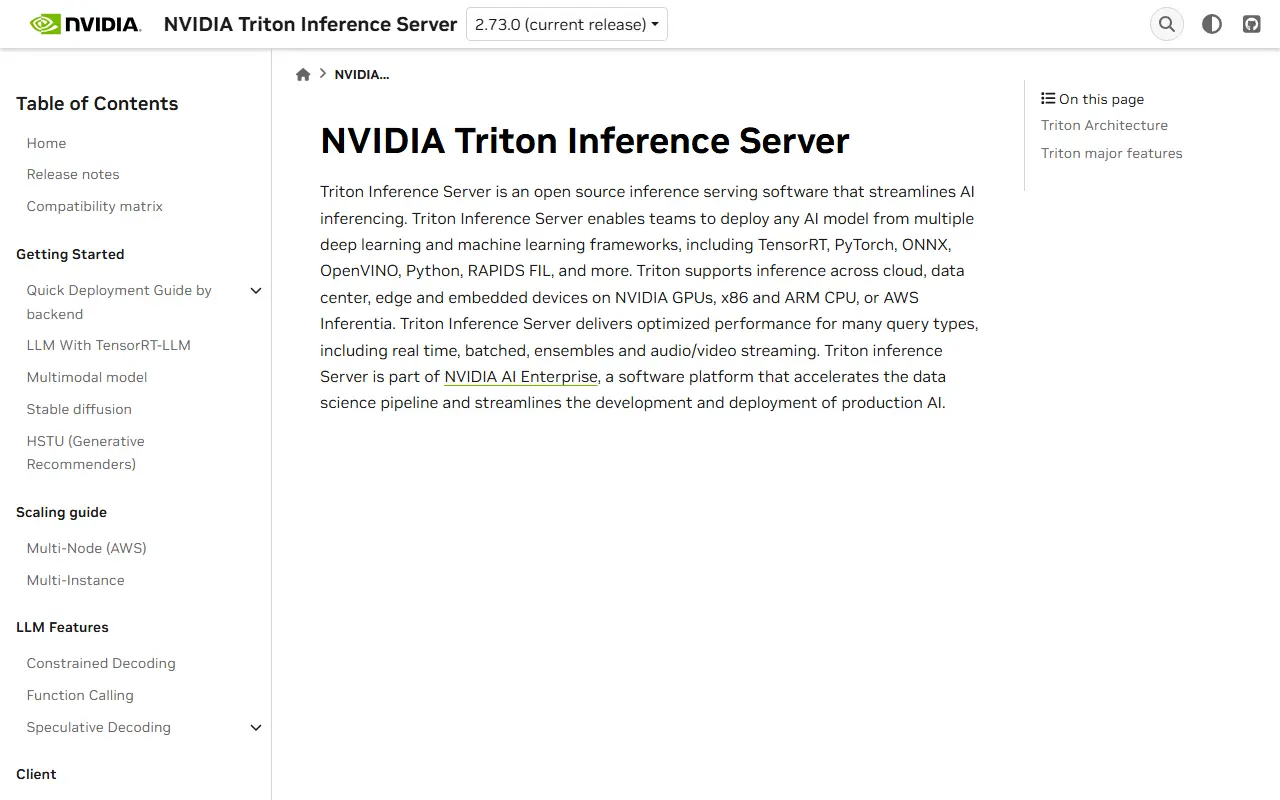
NVIDIA Triton Inference Server is a software platform designed for optimized inference of AI models in cloud and edge environments. It supports a variety of model backends including TensorRT-LLM, vLLM, PyTorch, ONNX, and OpenVINO, among others.
The server provides features for concurrent model execution, scheduling, batching, model pipelines, and state management. It includes client libraries for Python and C/C++, and supports HTTP/REST and gRPC protocols, as well as an OpenAI-compatible API.
Key features
- Supports multiple model backends including TensorRT-LLM, vLLM, PyTorch, ONNX, and OpenVINO
- Provides concurrent model execution and scheduling with batching
- Supports model pipelines via ensembles and business logic scripting
- Includes state management and request cancellation
- Offers metrics, tracing, and caching capabilities
- Provides client libraries for Python and C/C++
Good fit for
- Serving large language models
- Serving vision and embedding models
- Benchmarking and tuning model performance
Nvidia: questions and answers
- What is Nvidia used for?
- NVIDIA Triton Inference Server is an optimized cloud and edge inferencing solution that supports multiple backends and provides APIs for model serving. It is a good fit for serving large language models, serving vision and embedding models, and benchmarking and tuning model performance.
- Is Nvidia open source?
- Yes. Nvidia is open source under the BSD-3-Clause licence. Its source code is on GitHub at triton-inference-server/server and is written mainly in Python.
- Is Nvidia free?
- Yes. Nvidia is open source, so the software itself is free to use.
- Can I self-host Nvidia?
- Yes. Nvidia can be self-hosted on your own server or infrastructure.
- What is Nvidia an alternative to?
- Nvidia is an open-source alternative to Fireworks AI, Baseten, NVIDIA AI Enterprise and Cloudflare Workers AI. Other open-source alternatives to Fireworks AI include BentoML, vLLM and Ray.
- Is Nvidia actively maintained?
- Yes. The most recent commit to Nvidia was on 13 October 2026, and the latest release is v2.73.0, published on 30 September 2026. The project has 11k stars on GitHub.
Open-source alternatives to Nvidia
See all
BentoML
AI Infrastructure
The easiest way to serve AI apps and models - Build Model Inference APIs, Job queues, LLM
Apache-2.0vs Amazon SageMaker★ 8.9k
vLLM
AI Infrastructure
A high-throughput and memory-efficient inference and serving engine for LLMs
Apache-2.0vs Amazon Bedrock★ 94k
Ray
Hosting & PaaS
Ray is an AI compute engine. Ray consists of a core distributed runtime and a set of AI Li
Apache-2.0vs OpenRouter★ 44k
SGLang
AI Infrastructure
SGLang is a high-performance serving framework for large language models and multimodal mo
Apache-2.0vs Amazon Bedrock★ 37k
MLflow
AI Infrastructure
The open source AI engineering platform for agents, LLMs, and ML models. MLflow enables te
Apache-2.0vs Weights & Biases★ 28k
Kubeflow
AI Tools
The Cloud Native AI Platform
Apache-2.0vs Together AI★ 16k
SaaS alternatives to Nvidia
See all
Fireworks AI
AI Infrastructure
Inference platform for running and fine-tuning generative AI models at low latency
SaaS
Baseten
AI Infrastructure
Inference platform for deploying and scaling AI models in production
SaaS
NVIDIA AI Enterprise
AI Infrastructure
Software suite of NIM microservices, frameworks and tools for running production AI
SaaS
Cloudflare Workers AI
AI Infrastructure
Serverless inference service for running AI models on Cloudflare's network
SaaS
SambaNova
AI Infrastructure
AI inference cloud and platform running open models on custom chips
SaaS
Cerebras
AI Infrastructure
AI inference and training cloud built on wafer-scale chips
SaaS