#1
Apache Kafka is an open-source platform for distributed event streaming, used in data pipelines, streaming analytics and data integration.
- GitHub stars
- 34k
- Last commit
- yesterday
- Licence
- Apache-2.0
- Self-hosted
- Yes
kafka.apache.org
Apache Kafka is a platform for distributed event streaming. Teams use it to move and process streams of events for data pipelines, streaming analytics, data integration and business-critical applications. The code lives in the Apache Software Foundation repository, is written mainly in Java with Scala for parts of the broker, and is released under the Apache-2.0 license.
Kafka is installed software that you run yourself. The project builds and tests against recent Java versions, supports Scala 2.13 only, and documents how to build a JAR and start a broker through its quickstart. The repository also contains client and streams modules, along with test tooling for unit and integration runs. Because Kafka is operated as infrastructure, adopters typically run clusters on their own servers or on Kubernetes, though managed services from other vendors exist.
Key features
- Distributed event streaming platform
- Durable publish and subscribe topics
- Client libraries and a streams module
- Suited to data pipelines and integration
- Runs on Java with Scala 2.13
- Quickstart for building and running a broker
Pricing: Free and open source under the Apache-2.0 license.
#2
An open-source data movement platform with hundreds of connectors for ELT pipelines from APIs, databases and files into warehouses, lakes and AI applications.
- GitHub stars
- 22k
- Last commit
- today
- Latest release
- v2.0.0
- Self-hosted
- Yes
- Hosted version
- Available
airbyte.com
Airbyte is an open-source data movement platform for moving data from APIs, databases and files into data warehouses, data lakes and AI applications. Its premise is that only an open-source project can reach the long tail of data sources while letting engineers tailor existing connectors, with the aim of moving data from any source to any destination.
It offers a catalog of 600 or more connectors for APIs, databases, warehouses, lakes and AI applications, with warehouse destinations such as BigQuery, Redshift and Snowflake, and topics also mention change data capture. The README distinguishes products by job: Airbyte Open Source or Airbyte Cloud for ELT and ETL into warehouses, lakes or databases, and Airbyte Agents, a managed data and context layer, plus an open-source Agent SDK for giving AI agents and MCP clients real-time access to business data.
Airbyte is written in Python and Java, and its license is listed as 'Other' on GitHub because the project uses a mix of licenses, so review the terms for your use. It can be self-hosted or run as the managed Airbyte Cloud, and suits data teams that need many integrations without writing each pipeline by hand.
Key features
- 600+ source and destination connectors
- ELT pipelines into warehouses and lakes
- Change data capture support
- Customizable open-source connectors
- Agent SDK for AI agent data access
- Self-hosted or Airbyte Cloud
Pricing: The open-source Core edition is free to self-host. Managed cloud starts at $20 a month (Standard) or $189 a month for 40 credits (Plus); Pro and Enterprise Flex are custom. 30-day trial.
#3
Apache Flink is a framework and distributed processing engine for stateful computations over unbounded and bounded data streams, designed to run in all common cluster environments.
- GitHub stars
- 26k
- Last commit
- yesterday
- Licence
- Apache-2.0
- Self-hosted
- Yes
flink.apache.org
Apache Flink is a framework and distributed processing engine for stateful computations over unbounded and bounded data streams. It has been designed to run in all common cluster environments, perform computations at in-memory speed and at any scale.
Flink provides correctness guarantees including exactly-once state consistency, event-time processing, and sophisticated late data handling. It offers layered APIs such as SQL on stream and batch data, DataStream API, and ProcessFunction for time and state.
Key features
- Exactly-once state consistency
- Event-time processing
- Sophisticated late data handling
- Layered APIs including SQL, DataStream API, and ProcessFunction
- Flexible deployment and high-availability setup
- Scale-out architecture with support for very large state and incremental checkpoints

An open-source change data capture platform that streams row-level database changes as events to Kafka and other consumers with low latency.
- GitHub stars
- 13k
- Last commit
- yesterday
- Licence
- Apache-2.0
- Self-hosted
- Yes
debezium.io
Debezium is an open-source platform for change data capture. You configure it to monitor your databases, and your applications then consume an event for each row-level change. Only committed changes are visible, so consumers do not need to deal with transactions that are rolled back.
It provides one consistent model for change events across different database systems, so applications are insulated from the details of each engine. Changes are recorded in durable, replicated logs, which means a consumer can be stopped and restarted and still receive every event it missed. This removes the need for database-specific triggers or ad hoc change-monitoring code, which the project describes as hard to get right when ordering and low impact on the database both matter.
Debezium is built with Java and Kafka Connect in mind, as the project topics show, and is licensed under Apache-2.0, with the ANTLR grammars in its DDL parser module under the MIT licence. It runs as part of your own data infrastructure and suits data engineers building event streaming pipelines, cache invalidation or data replication.
Key features
- Row-level change data capture from databases
- Single event model across database types
- Only committed changes are exposed
- Durable, replicated change logs
- Restartable consumers that catch up on missed events
- Kafka Connect based modules
Pricing: Free and open source under the Apache-2.0 licence.
#5
An open-source event streaming platform that ingests data from databases, streams and webhooks, processes it incrementally with SQL and serves fresh results at low latency.
- GitHub stars
- 9.4k
- Last commit
- today
- Latest release
- v3.1.1
- Licence
- Apache-2.0
- Self-hosted
- Yes
go.risingwave.com
RisingWave is an event streaming platform, positioned for agentic AI and real-time applications, that continuously takes in data, transforms it and serves it. It is meant to replace the familiar chain of Debezium (change data capture), Kafka (transport), Flink (processing) and a serving database with one system, removing the latency and operational work of each hop.
Sources include webhooks from SaaS applications, native change data capture from PostgreSQL and MySQL, event streams such as Kafka, Pulsar and Kinesis, and batch data from S3 and warehouses, all unified under a SQL interface where streams and tables can be joined. Processing is incremental: if upstream data changes, just the affected results get recomputed, which keeps materialized views up to date without full recomputation. Results are queryable directly, and the topics mention PostgreSQL compatibility and Apache Iceberg.
RisingWave is written in Rust and licensed under Apache-2.0. It can be tried with Docker or Kubernetes using the quick start guide, and it suits data engineers who want streaming pipelines defined in SQL instead of several separate services.
Key features
- Ingestion from CDC, Kafka, webhooks and batch sources
- Incremental stream processing in SQL
- Always up-to-date materialized views
- Low-latency serving of query results
- Interface compatible with PostgreSQL clients
- Docker and Kubernetes deployment
Pricing: Free and open source under the Apache-2.0 licence.
#6
An open-source ETL and ELT platform built on DuckDB that you deploy yourself, with visual or SQL pipelines, dbt, CDC, data quality and an MCP server.
- GitHub stars
- 1.6k
- Last commit
- today
- Latest release
- v0.8.0
- Licence
- Apache-2.0
- Self-hosted
- Yes
duckle.org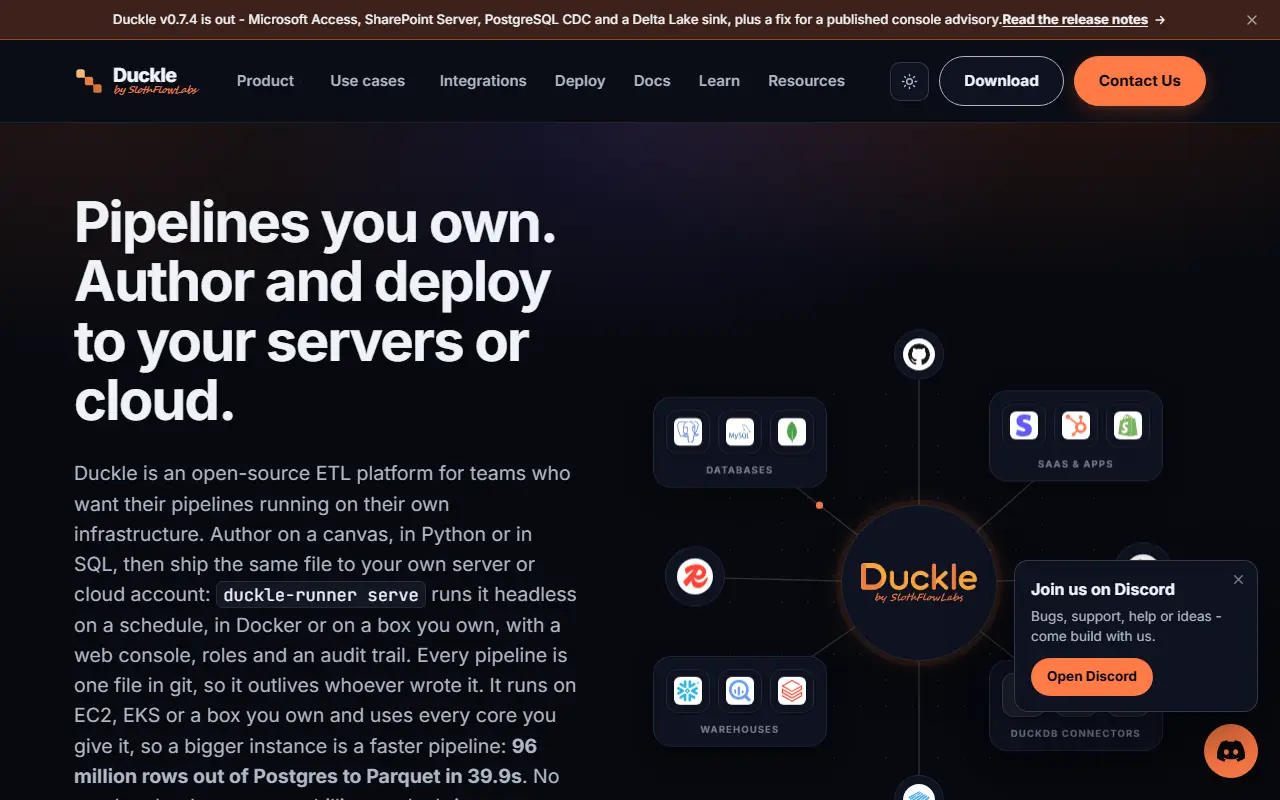
Duckle is an open-source ETL and ELT platform for teams that want their data pipelines running on their own infrastructure. You build pipelines on a visual canvas, in Python or in SQL, then ship the same file to your own server or cloud account, where a headless runner executes it on a schedule.
Pipelines compile to SQL on DuckDB and use all the cores available, so a larger machine runs them faster. The platform lists support for a large catalog of components, dbt, change data capture, data quality checks, reverse ETL and lineage, along with a web console, roles, an audit trail and an MCP server so AI agents such as Claude or Cursor can work with it. Each pipeline is a single file that can live in git.
Duckle is written in Rust and licensed under Apache-2.0, and it runs headless in Docker or on a plain server, with Kubernetes among its topics. It states there is no vendor cloud and no per-row billing. It is an independent project by SlothFlowLabs and is not affiliated with DuckDB Labs or MotherDuck. It suits data engineers who want a self-hosted alternative to managed pipeline services.
Key features
- Visual canvas, Python, or SQL pipeline authoring
- Runs on DuckDB across all CPU cores
- dbt, CDC, and reverse ETL support
- Data quality checks and lineage
- Web console with roles and audit trail
- MCP server for AI agents
Pricing: Free and open source under the Apache-2.0 licence, with no vendor cloud or per-row billing according to the README.
#7
Materialize is a streaming SQL database that keeps views over live data continuously up to date, for operational dashboards, AI context and read offload.
- GitHub stars
- 6.4k
- Last commit
- today
- Latest release
- v26.50.0
- Self-hosted
- Yes
- Hosted version
- Available
materialize.com
Materialize is a streaming data platform that builds incrementally updated, consistent views over transactional data from across an organization. Users define views in SQL, and Materialize keeps the results fresh as new data arrives, so applications and AI agents can read current answers without custom pipelines.
It speaks a PostgreSQL-compatible SQL dialect and ingests change data from sources such as Kafka, PostgreSQL, MySQL and SQL Server through change data capture. The README names common adoption patterns, including query offload in a CQRS style, where complex reads move off the main database, plus fresh context for AI and RAG pipelines, operational dashboards and more dynamic customer experiences. The engine is written in Rust.
The source is published under terms that GitHub lists as 'Other', which reflects a source-available model rather than a standard open-source license, and Materialize can be deployed wherever your infrastructure runs. A managed cloud service from the vendor is also available.
Key features
- Incrementally maintained materialized views in SQL
- PostgreSQL-compatible SQL interface
- Change data capture from Postgres, MySQL and SQL Server
- Kafka streaming ingestion
- Query offload from transactional databases
- Fresh data for AI and RAG pipelines
Pricing: Free self-managed Community License up to 24GiB memory, plus a free cloud trial. Cloud compute is $1.50 per Compute Credit; the self-managed Enterprise License is an annual quote.
#8
Redpanda is a streaming data platform that provides Kafka-compatible real-time data streaming, connectors, and SQL querying, with an agentic data plane for governing AI agent access and actions.
- GitHub stars
- 13k
- Last commit
- 1 mo ago
- Latest release
- v26.2.2
- Hosted version
- Available
redpanda.com
Redpanda is a streaming data platform designed for developers. It offers Kafka-compatible real-time data streaming with a C++ engine and no dependencies on ZooKeeper or JVM. The platform includes Redpanda Connect with over 300 connectors for declarative YAML pipelines and Redpanda SQL, a PostgreSQL-compatible distributed OLAP engine for querying live and historical data.
The platform also provides an Agentic Data Plane for running AI agents in production on enterprise data. This includes features for secure AI agent data access, governance policy enforcement, guardrails, kill switches, full transcripts of interactions, real-time observability, automated evaluations, and token budget enforcement. It supports building agents with Redpanda AI Agents or bringing custom agents, and governs tool calls through MCP Gateway and AI Gateway.
Key features
- Kafka-compatible streaming with C++ engine, no ZooKeeper, no JVM
- Redpanda Connect with 300+ connectors and declarative YAML pipelines
- Redpanda SQL: PostgreSQL-compatible distributed OLAP engine
- Agentic Data Plane for governing AI agent data access and actions
- Enforce governance policies, guardrails, and kill switches for agents
- Full transcripts, real-time observability, automated evaluations, and token budget enforcement

Dozer is a free, AGPL-licensed, open-source real-time data movement tool written in Rust that uses change data capture to stream data from databases into warehouses and other sinks.
- GitHub stars
- 1.6k
- Last commit
- 2 yr ago
- Latest release
- v0.4.0
- Licence
- AGPL-3.0
- Self-hosted
- Yes
getdozer.io
Dozer is a real-time data movement platform that uses change data capture (CDC) to stream data continuously from source databases into destinations such as data warehouses. It is aimed at data engineering teams who need faster, simpler CDC pipelines than assembling Debezium and Kafka themselves, with native support for stateless transformations along the way.
It supports a range of source connectors including Postgres, MySQL, Snowflake, Kafka, MongoDB, Amazon S3, Google Cloud Storage, Oracle and Aerospike, with extraction and resuming support varying by connector and some sources reserved for the enterprise edition. On the sink side, it supports ClickHouse, Postgres, MySQL and BigQuery in the open-source edition, with Oracle and Aerospike sinks reserved for enterprise. The project notes its own typical use is moving data into ClickHouse to build data APIs and integrations with LLMs.
Dozer is configured through a single configuration file and is written in Rust for performance, claiming to be significantly faster than a Debezium-plus-Kafka setup for comparable CDC workloads. It is released under the AGPL-3.0 license, with full documentation available for setup and configuration details.
Key features
- Change data capture from multiple source databases
- Streaming data movement into warehouses
- Stateless transformations built in
- Single configuration file setup
- ClickHouse, Postgres, MySQL and BigQuery sinks
Pricing: The core is free and open source under the AGPL-3.0 license; some connectors and sinks (including Oracle and Aerospike) are reserved for a separate paid Enterprise edition.
Commercial Striim alternatives
Hosted, closed-source products that compete with Striim.
Striim alternatives: questions
- What is the best open-source alternative to Striim?
- Kafka is the top-ranked open-source alternative to Striim on Enlisted: Apache Kafka is an open-source platform for distributed event streaming, used in data pipelines, streaming analytics and data integration. Other strong options are Airbyte, Flink, Debezium and RisingWave.
- What are the best commercial alternatives to Striim?
- Oracle GoldenGate, Estuary, Confluent, Talend and Hevo Data are among the hosted, closed-source alternatives to Striim listed on Enlisted, which lists 10 in total. Compare their pricing and features on each tool page.
- Are these Striim alternatives free?
- All 9 are open source, so the code is free to use under its licence, and all of them can be self-hosted on your own server or computer. 3 also offer a paid or managed cloud version if you'd rather not host it yourself.
- How is this list of Striim alternatives ranked?
- By a score built from GitHub stars, star growth over the last 30 days and how recently the code changed. 7 of these projects shipped code in the last 30 days. Data is refreshed daily, and nobody can pay to move up.
 TrackMedia
 TrackRev