4 open-source alternatives ranked by real activity

Open-source Diffbot alternatives

A curated, ranked list of the 4 best open-source alternatives to Diffbot.

The best open-source alternative to Diffbot is Firecrawl. If that doesn't suit you, other good options are Crawl4AI, Maxun and Anakin.

Commercial alternatives to Diffbot include Zyte, Browse AI, ParseHub and Tavily. See all 28.

Diffbot alternatives are mainly AI tools, but some are also workflow automation tools. 3 of them shipped code in the last 30 days, 4 can be self-hosted, and 1 uses a permissive licence.

Last updated November 12, 2026 · ranked by GitHub stars, growth and recent commits

Firecrawl

Firecrawl is an open-source web data API that enables AI agents to search, scrape, and interact with web pages, providing LLM-ready data.

GitHub stars
201k
Last commit
yesterday
Latest release
v2.11.0
Licence
AGPL-3.0
Hosted version
Available
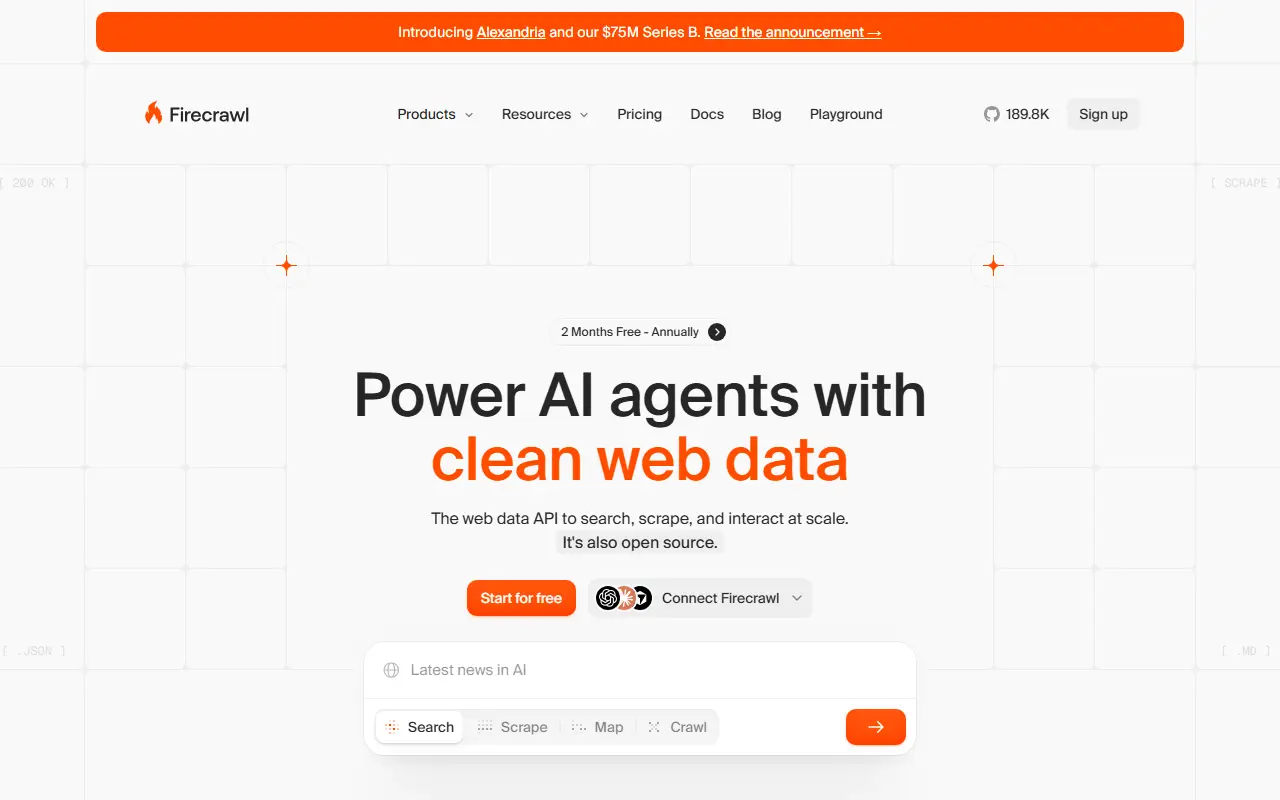
firecrawl.devFirecrawl homepage screenshot

Firecrawl is a web data API designed for AI agents. It provides search, scraping, and interaction capabilities to gather data from the web. The service is open source and offers access to more sources through Alexandria.

It is aimed at developers and companies building AI applications that need to retrieve and process web content. The API supports multiple programming languages including Python, Node.js, and cURL, and can output data in formats like Markdown, JSON, and screenshots.

Key features

  • Search the web and get full content from results
  • Scrape websites and get LLM-ready data in Markdown, JSON, screenshot, etc.
  • Interact with scraped pages using AI prompts or code
  • Map and crawl websites
  • Agent for autonomous data gathering
  • Open source

Crawl4AI

An open-source web crawler and scraper that turns any URL into clean Markdown, typed JSON, or search results for LLMs and AI agents.

GitHub stars
87k
Last commit
3 days ago
Latest release
v0.9.5
Licence
Apache-2.0
Self-hosted
Yes
Hosted version
Available
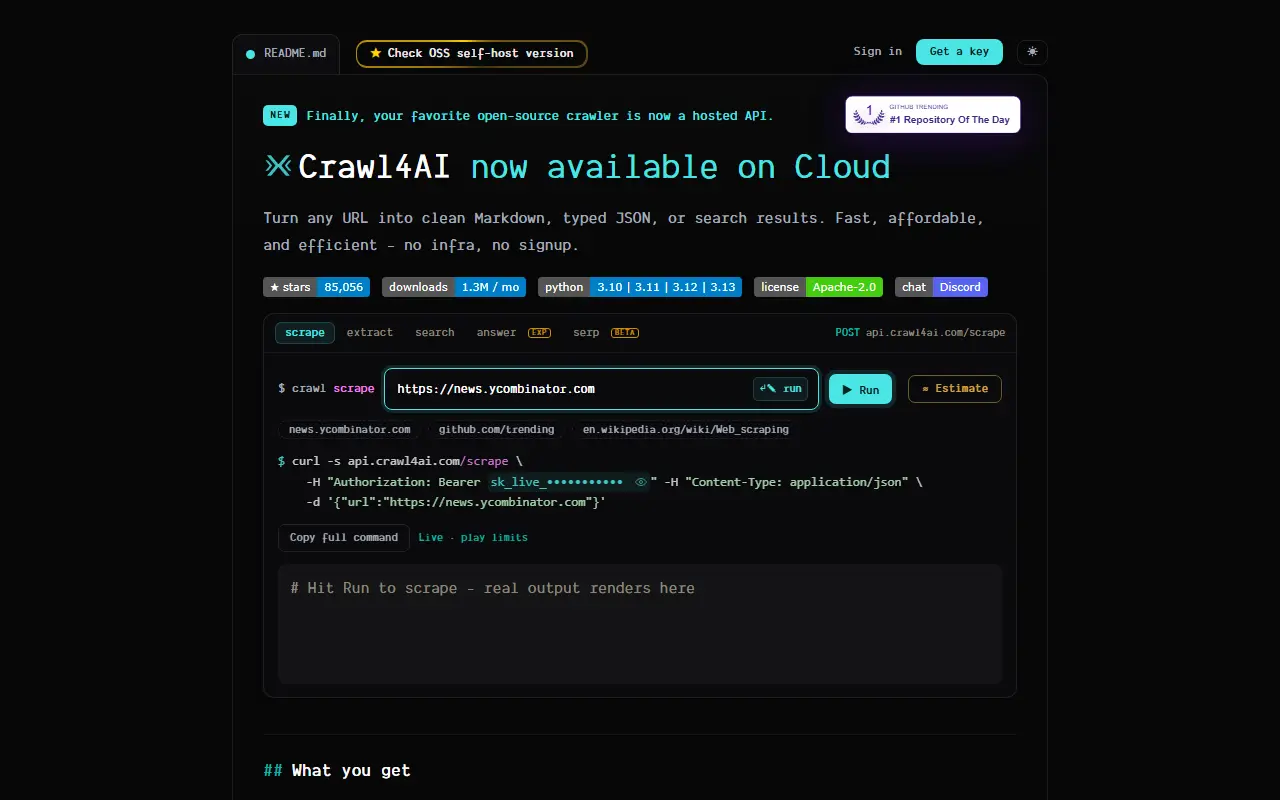
crawl4ai.comCrawl4AI homepage screenshot

Crawl4AI is an open-source web crawler and scraper designed for LLMs and AI agents. It converts any website into clean, LLM-ready Markdown, typed JSON, or search results. The software can be self-hosted or used via a cloud-hosted API with a key.

The hosted API provides endpoints for scraping, extracting structured data, searching, answering questions, and retrieving Google search results. It is designed to work with AI agents such as Claude Code, Codex, OpenCode, and Cursor.

Key features

  • Converts any URL into clean Markdown with boilerplate stripped
  • Extracts typed JSON records from a URL using plain-English instructions
  • Returns ranked search results as JSON
  • Provides direct answers with sources (experimental)
  • Retrieves Google search results as structured data for rank tracking (beta)
  • Supports queues, jobs, retries, and proxies at scale

Maxun

An open-source web data platform for scraping, crawling, searching and monitoring websites, turning pages into structured APIs with a no-code approach and AI extraction.

GitHub stars
18k
Last commit
4 days ago
Latest release
v0.1.0
Licence
AGPL-3.0
Self-hosted
Yes
Hosted version
Available
maxun.devMaxun homepage screenshot

Maxun is an open-source platform for getting structured data out of websites. Its pitch is to turn any site into an API: you can scrape pages, crawl links, search, monitor for changes and use AI-powered extraction, without having to hand-code a scraper for every site. Topics tag it as a no-code, RPA and browser-automation tool.

It is built on Playwright-style browser automation, written in TypeScript, and is meant to be used through a visual interface so that people who do not code can create data-extraction robots. The project offers a hosted app and documentation, tutorials and a Discord community, and it can be self-hosted. The README is heavily sponsored by proxy providers, which reflects how scraping at scale usually needs rotating proxies, though those are third-party services that are not part of Maxun itself.

Maxun is licensed under AGPL-3.0, which requires sharing source changes if you offer a modified version as a network service. It suits analysts, marketers and developers who regularly pull data from websites without official APIs, and who want a managed or self-run alternative to custom scraping scripts.

Key features

  • Turns websites into structured APIs
  • Scraping, crawling and search
  • Change monitoring of web pages
  • AI-assisted data extraction
  • No-code robot creation
  • Self-hosted or hosted app

Pricing: Self-hosting the open-source edition is free. Maxun Cloud costs $19 (Starter), $99 (Growth) or $399 (Pro) per month by credit allowance, with a 7-day free trial; Premium is custom.

Anakin

Self-hostable web scraping API in Go that turns websites into clean Markdown or structured JSON, with an anti-detect browser and automatic proxy selection.

GitHub stars
3.9k
Last commit
2 mo ago
Latest release
v0.1.1
Licence
AGPL-3.0
Self-hosted
Yes
anakin.ioAnakin homepage screenshot

AnakinScraper OSS is an open-source web scraping API aimed at AI use cases. It converts web pages into markdown ready for language models or into structured data, and it can be self-hosted with a single command with no cloud dependencies. It is written in Go and released under the AGPL-3.0 license.

The README highlights an anti-detect browser based on Camoufox, a Firefox build, smart proxy selection using Thompson Sampling, a handler chain that falls back from plain HTTP to a browser and then an API, and structured JSON extraction using Gemini. It can start with go run without a database and ships as one small Go binary, in contrast to the Node.js or Python based tools it compares itself against, including Firecrawl, Crawlee, and Scrapy.

It is meant to power RAG pipelines, AI agents, and data extraction at scale. Anyone scraping should check the target site's terms and applicable law. It suits developers who want a private, self-run alternative to hosted scraping APIs.

Key features

  • Websites to markdown or structured JSON
  • Anti-detect browser based on Camoufox
  • Smart proxy selection
  • Handler chain from HTTP to browser to API
  • Single Go binary, no database required
  • One-command self-hosting

Pricing: A free Starter plan includes 300 credits. Pro is $19, Scale $100 and Business $500 per month on monthly billing, about a third cheaper billed annually; Enterprise is custom.

Commercial Diffbot alternatives

Hosted, closed-source products that compete with Diffbot. Showing 12 of 28.

See every Diffbot alternative on its tool page

Diffbot alternatives: questions

What is the best open-source alternative to Diffbot?
Firecrawl is the top-ranked open-source alternative to Diffbot on Enlisted: Firecrawl is an open-source web data API that enables AI agents to search, scrape, and interact with web pages, providing LLM-ready data. Other strong options are Crawl4AI, Maxun and Anakin.
What are the best commercial alternatives to Diffbot?
Zyte, Browse AI, ParseHub, Tavily and Bright Data are among the hosted, closed-source alternatives to Diffbot listed on Enlisted, which lists 28 in total. Compare their pricing and features on each tool page.
Are these Diffbot alternatives free?
All 4 are open source, so the code is free to use under its licence, and all of them can be self-hosted on your own server or computer. 3 also offer a paid or managed cloud version if you'd rather not host it yourself.
How is this list of Diffbot alternatives ranked?
By a score built from GitHub stars, star growth over the last 30 days and how recently the code changed. 3 of these projects shipped code in the last 30 days. Data is refreshed daily, and nobody can pay to move up.

People also look for alternatives to…

View all